API Pricing & Plans
Claude Fable 5.1 API Pricing: What Changed and What You'll Pay
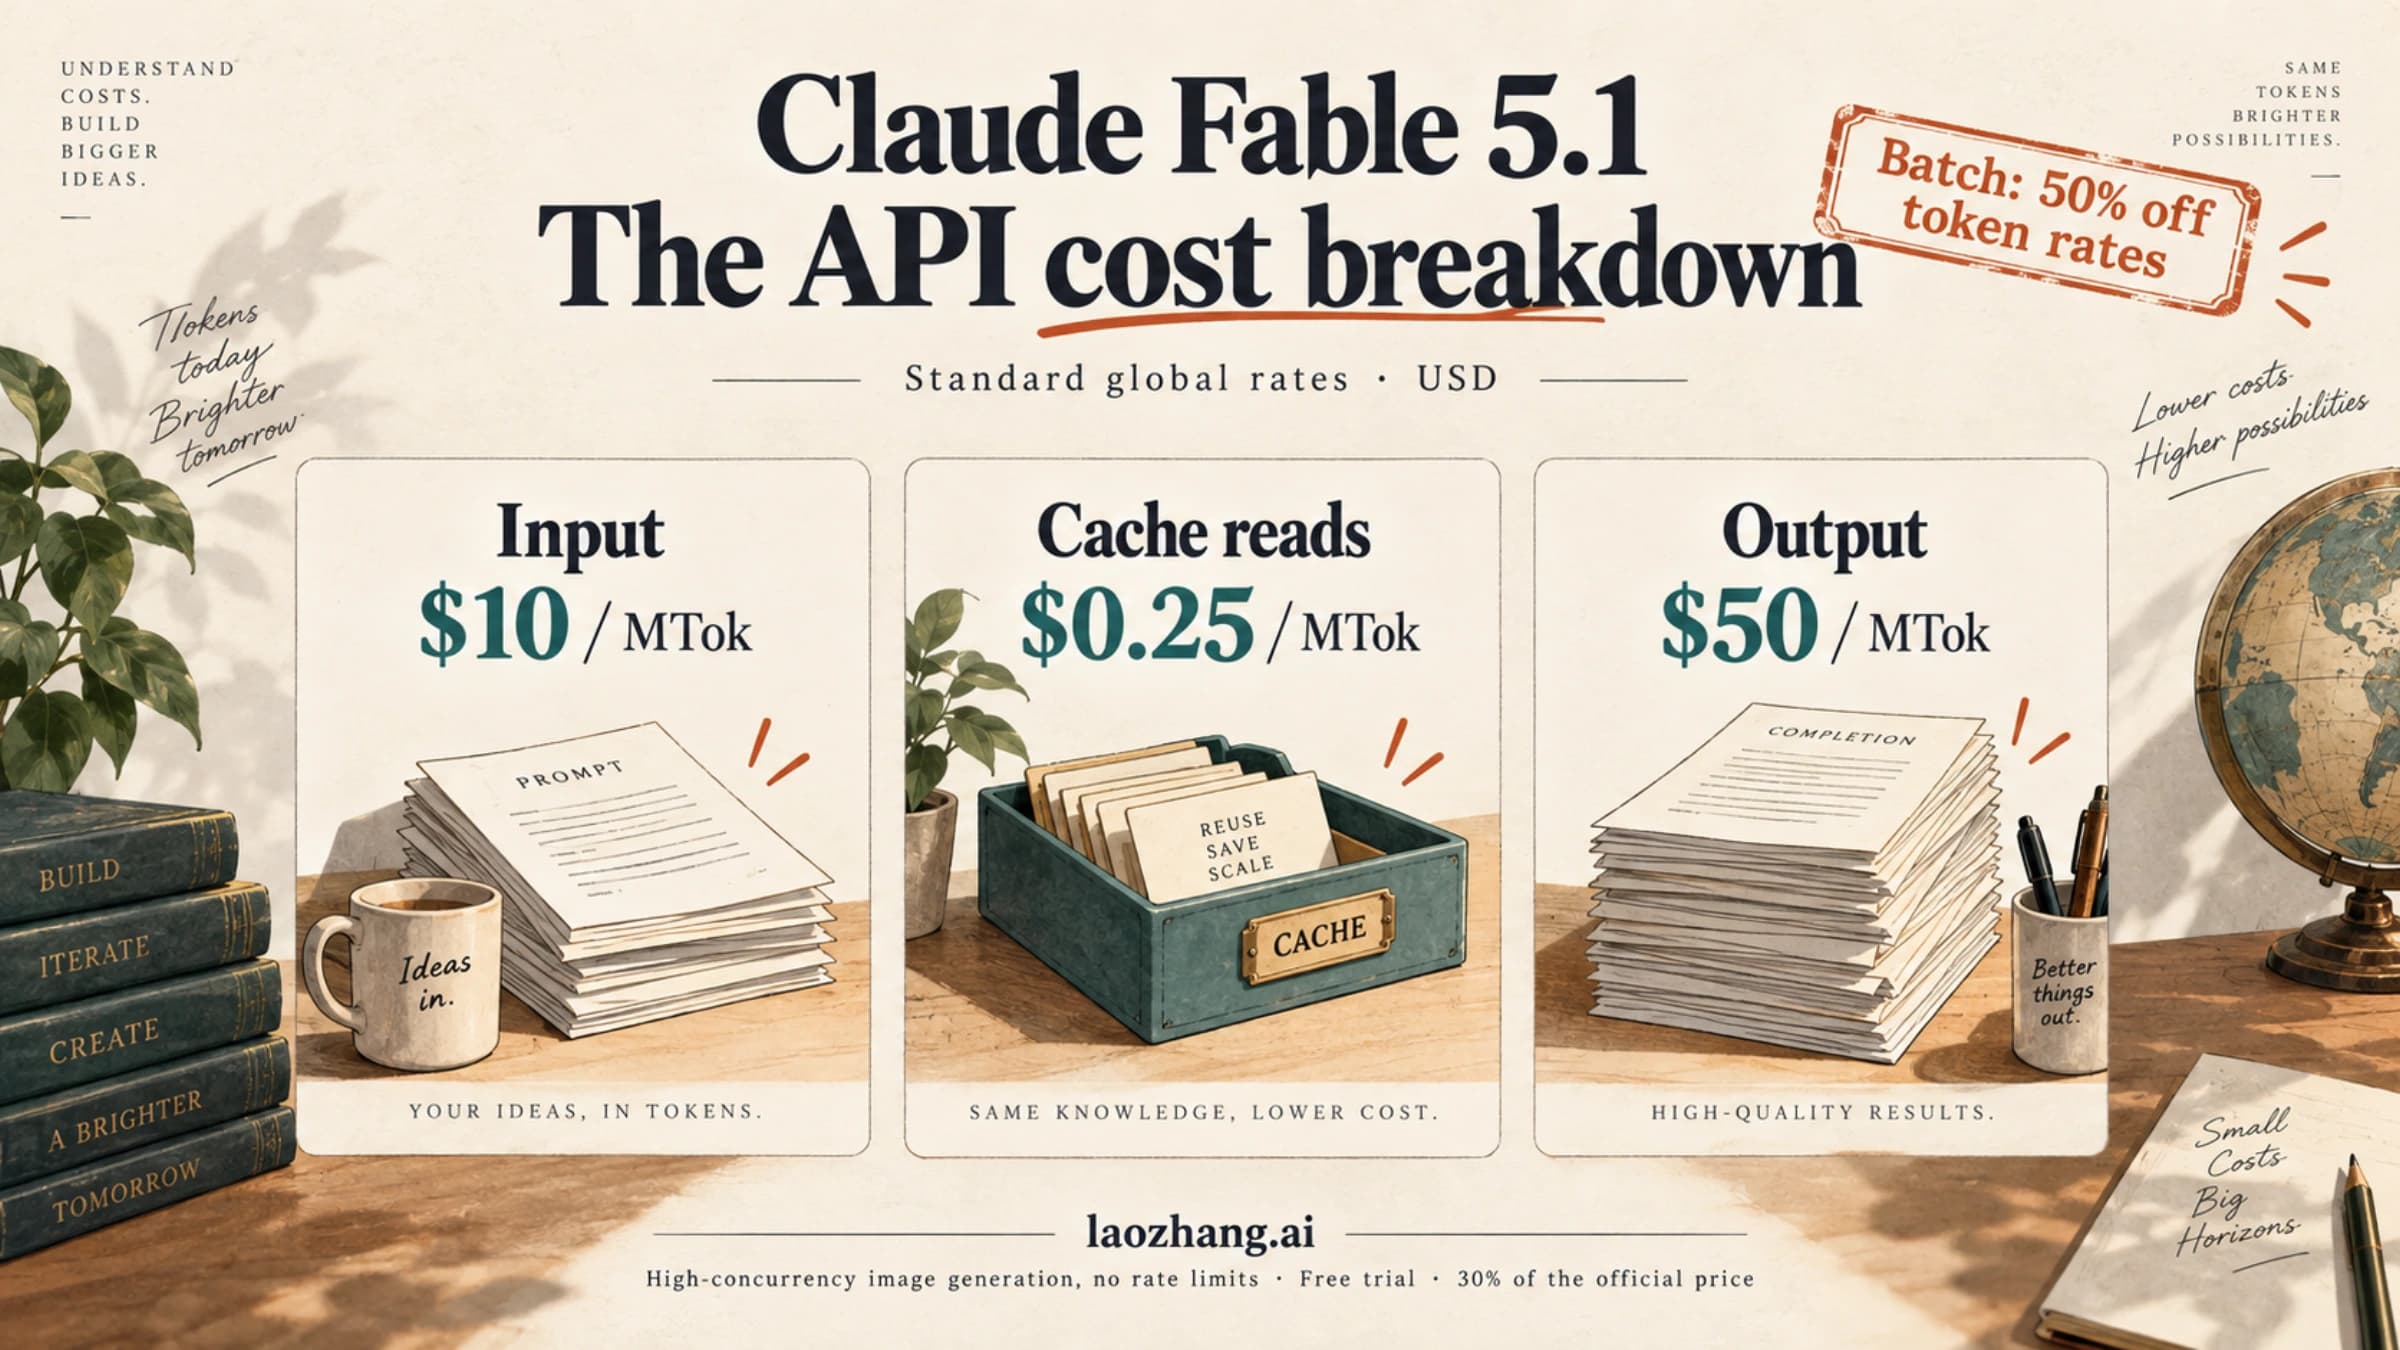
Claude Fable 5.1 costs $10 per million input and $50 per million output tokens. Only cache reads got cheaper, $1 to $0.25, so savings track your cache use.
12 min
Claude Fable 5.1 costs $10 per million input and $50 per million output tokens. Only cache reads got cheaper, $1 to $0.25, so savings track your cache use.
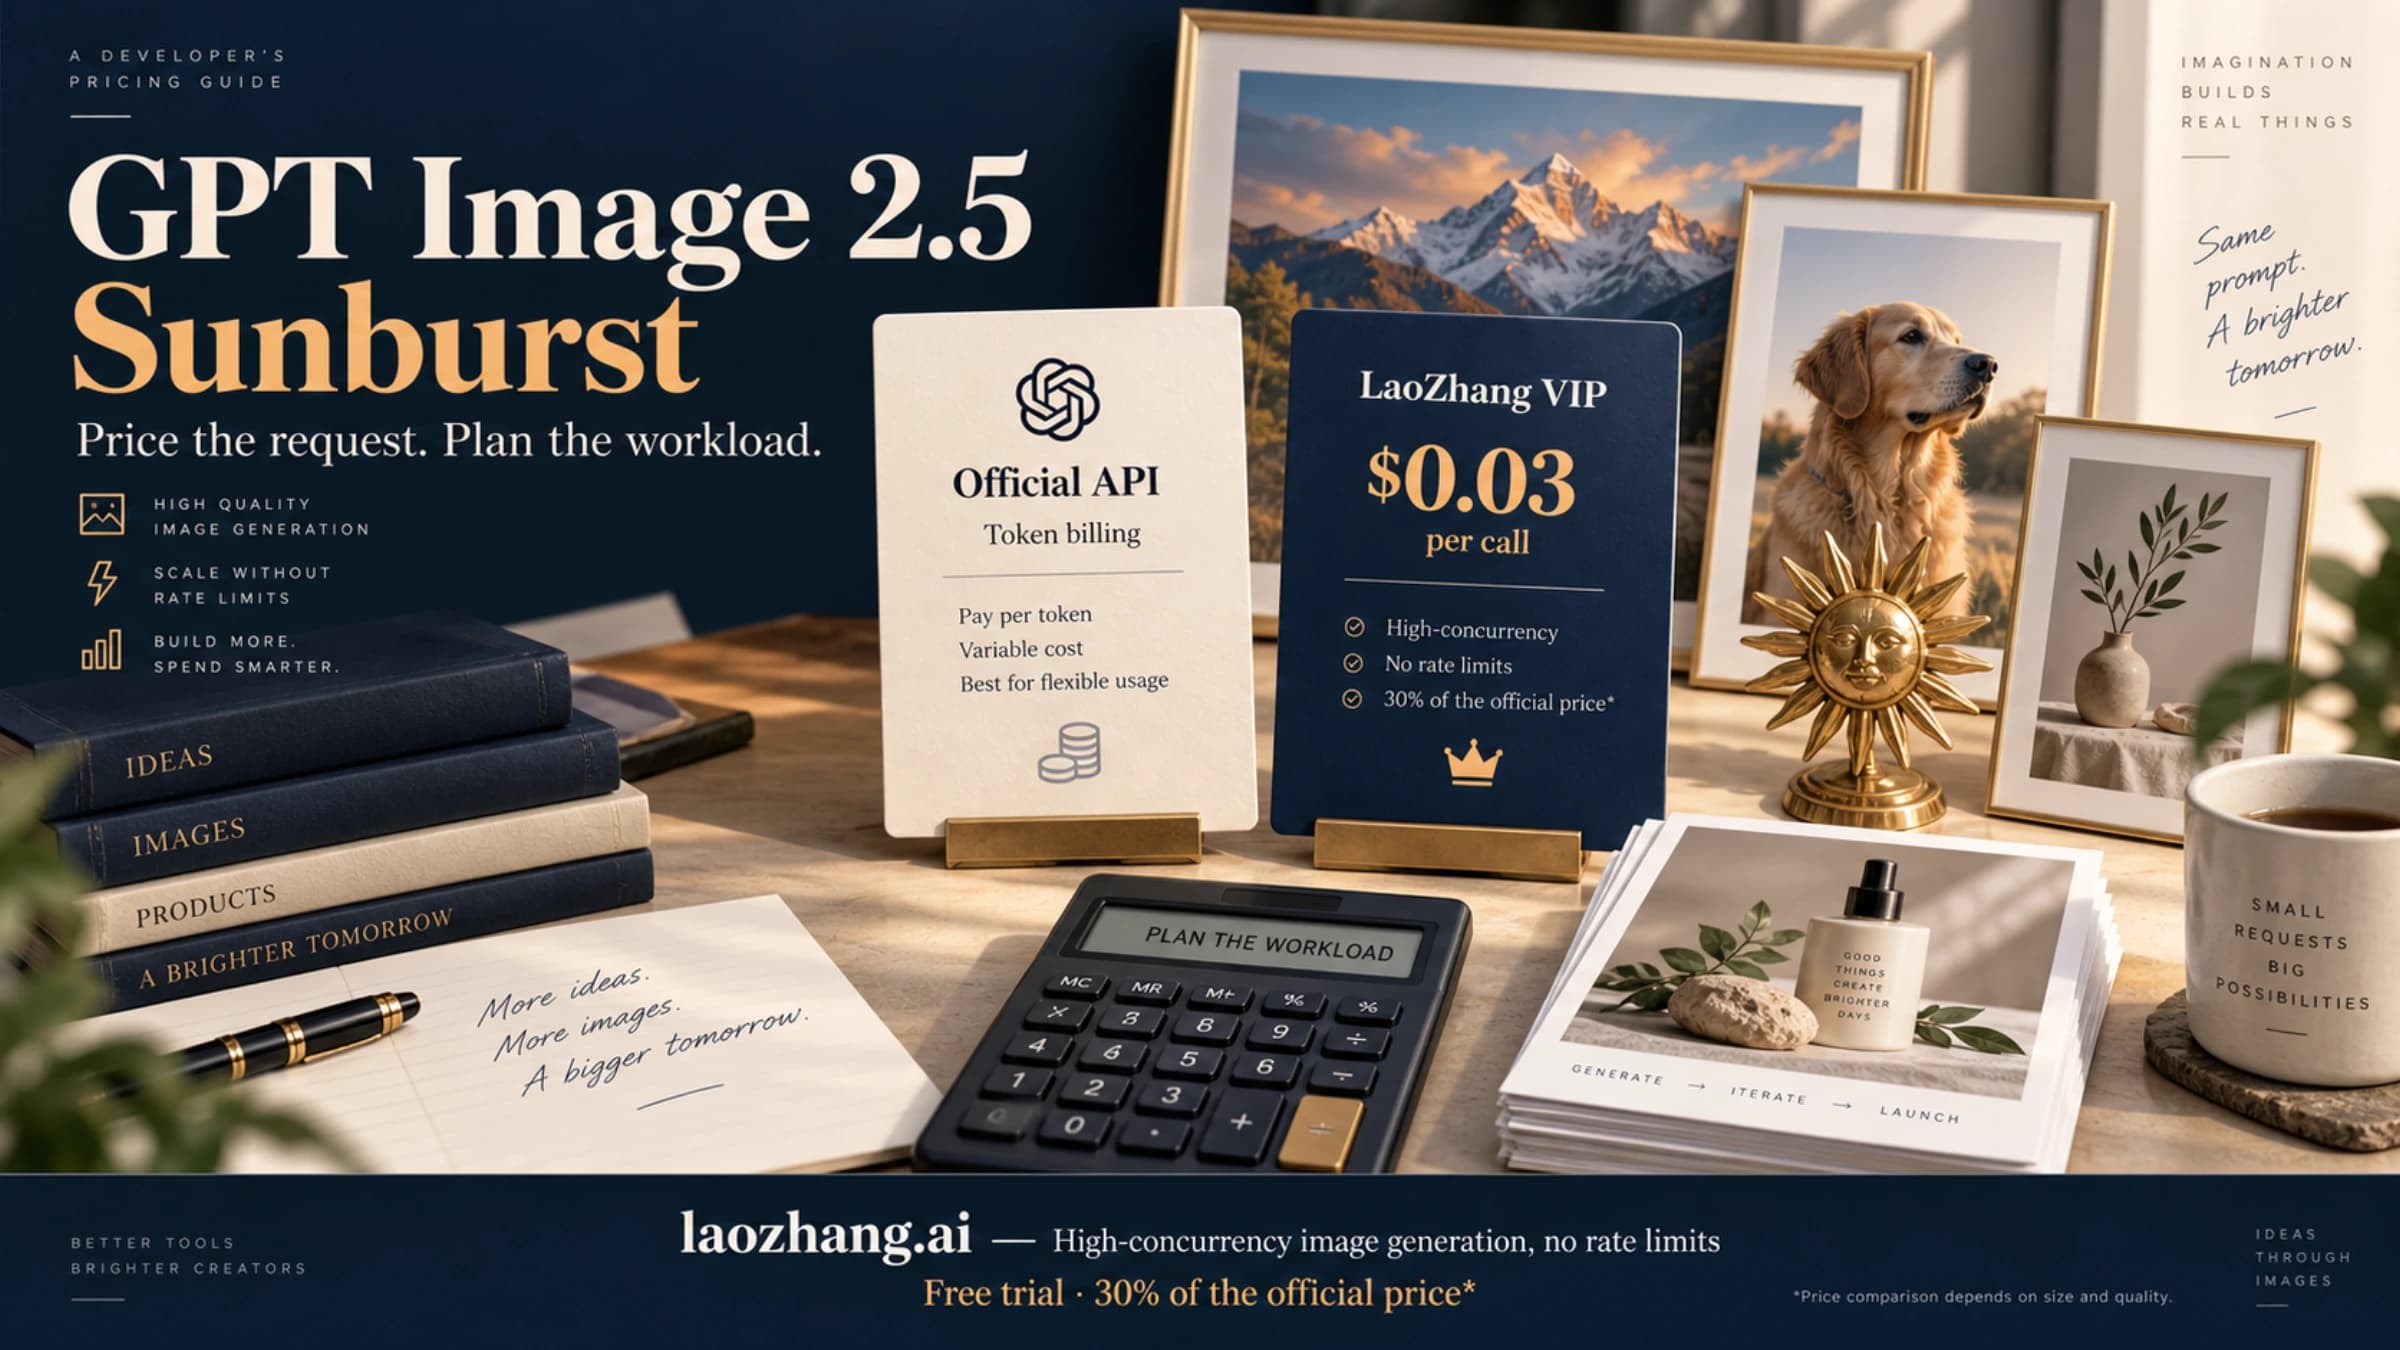
Compare GPT Image 2.5 Sunburst and Flare token costs with LaoZhang’s $0.03/call VIP option, including quality settings, editing charges, and monthly budgets.
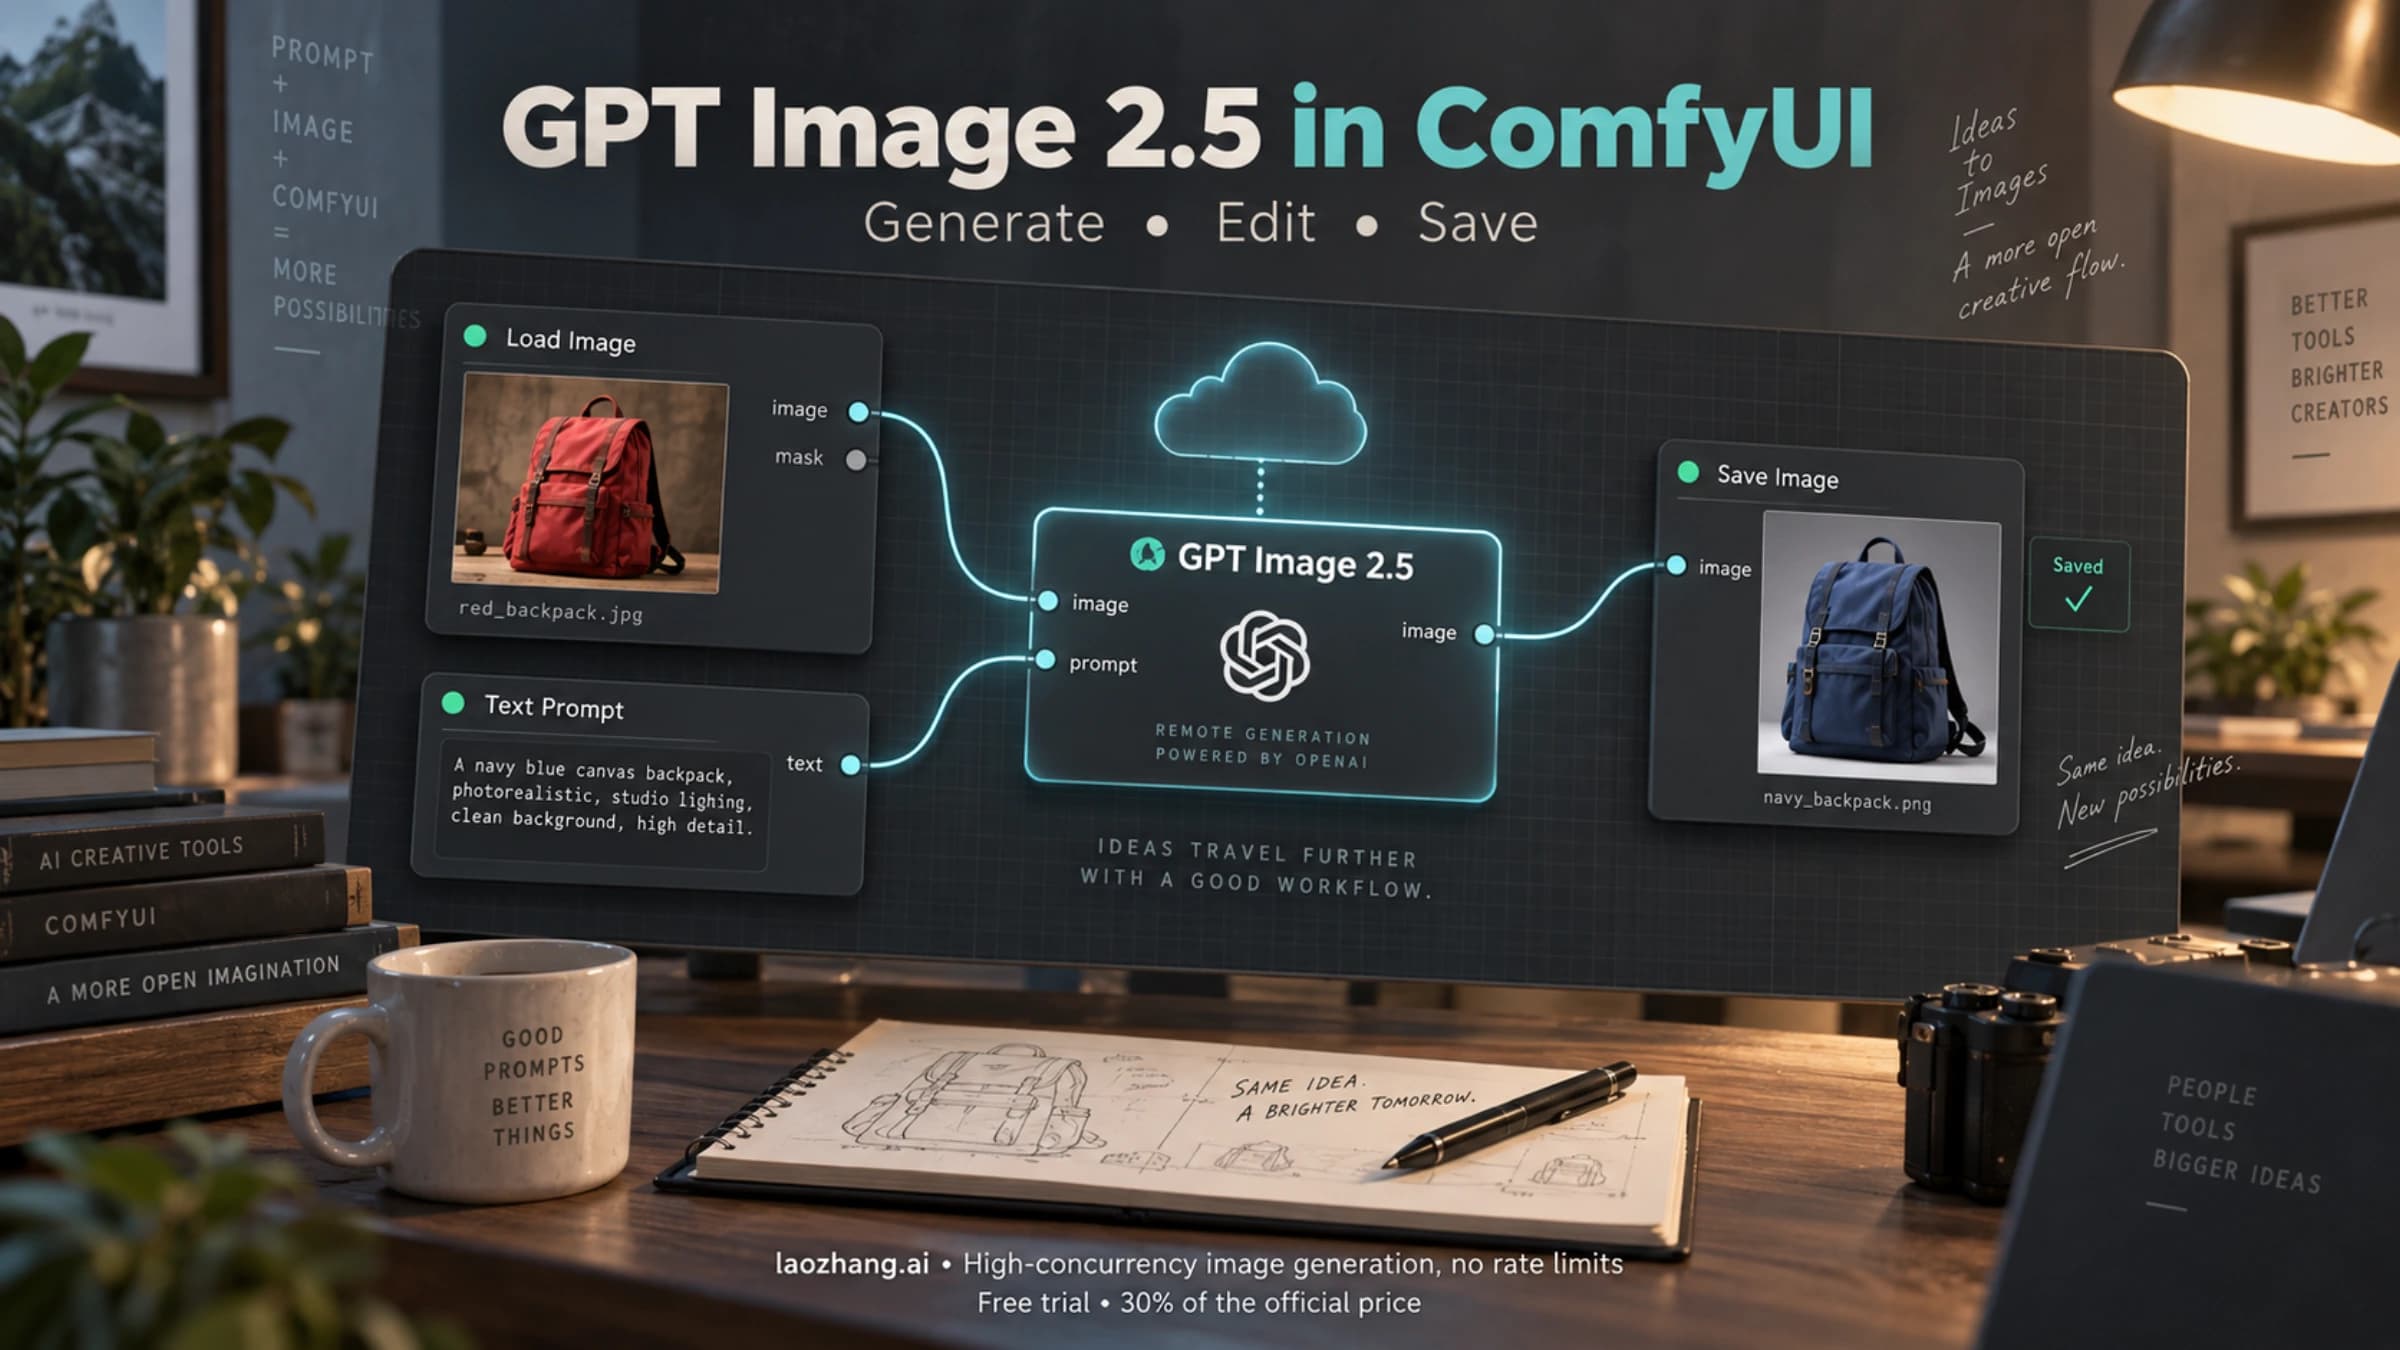
GPT Image 2.5 runs in ComfyUI 0.35.0+ as a Partner Node billed in Comfy credits, not an OpenAI key. A 1024×1024 image costs about $0.0084 at low quality.
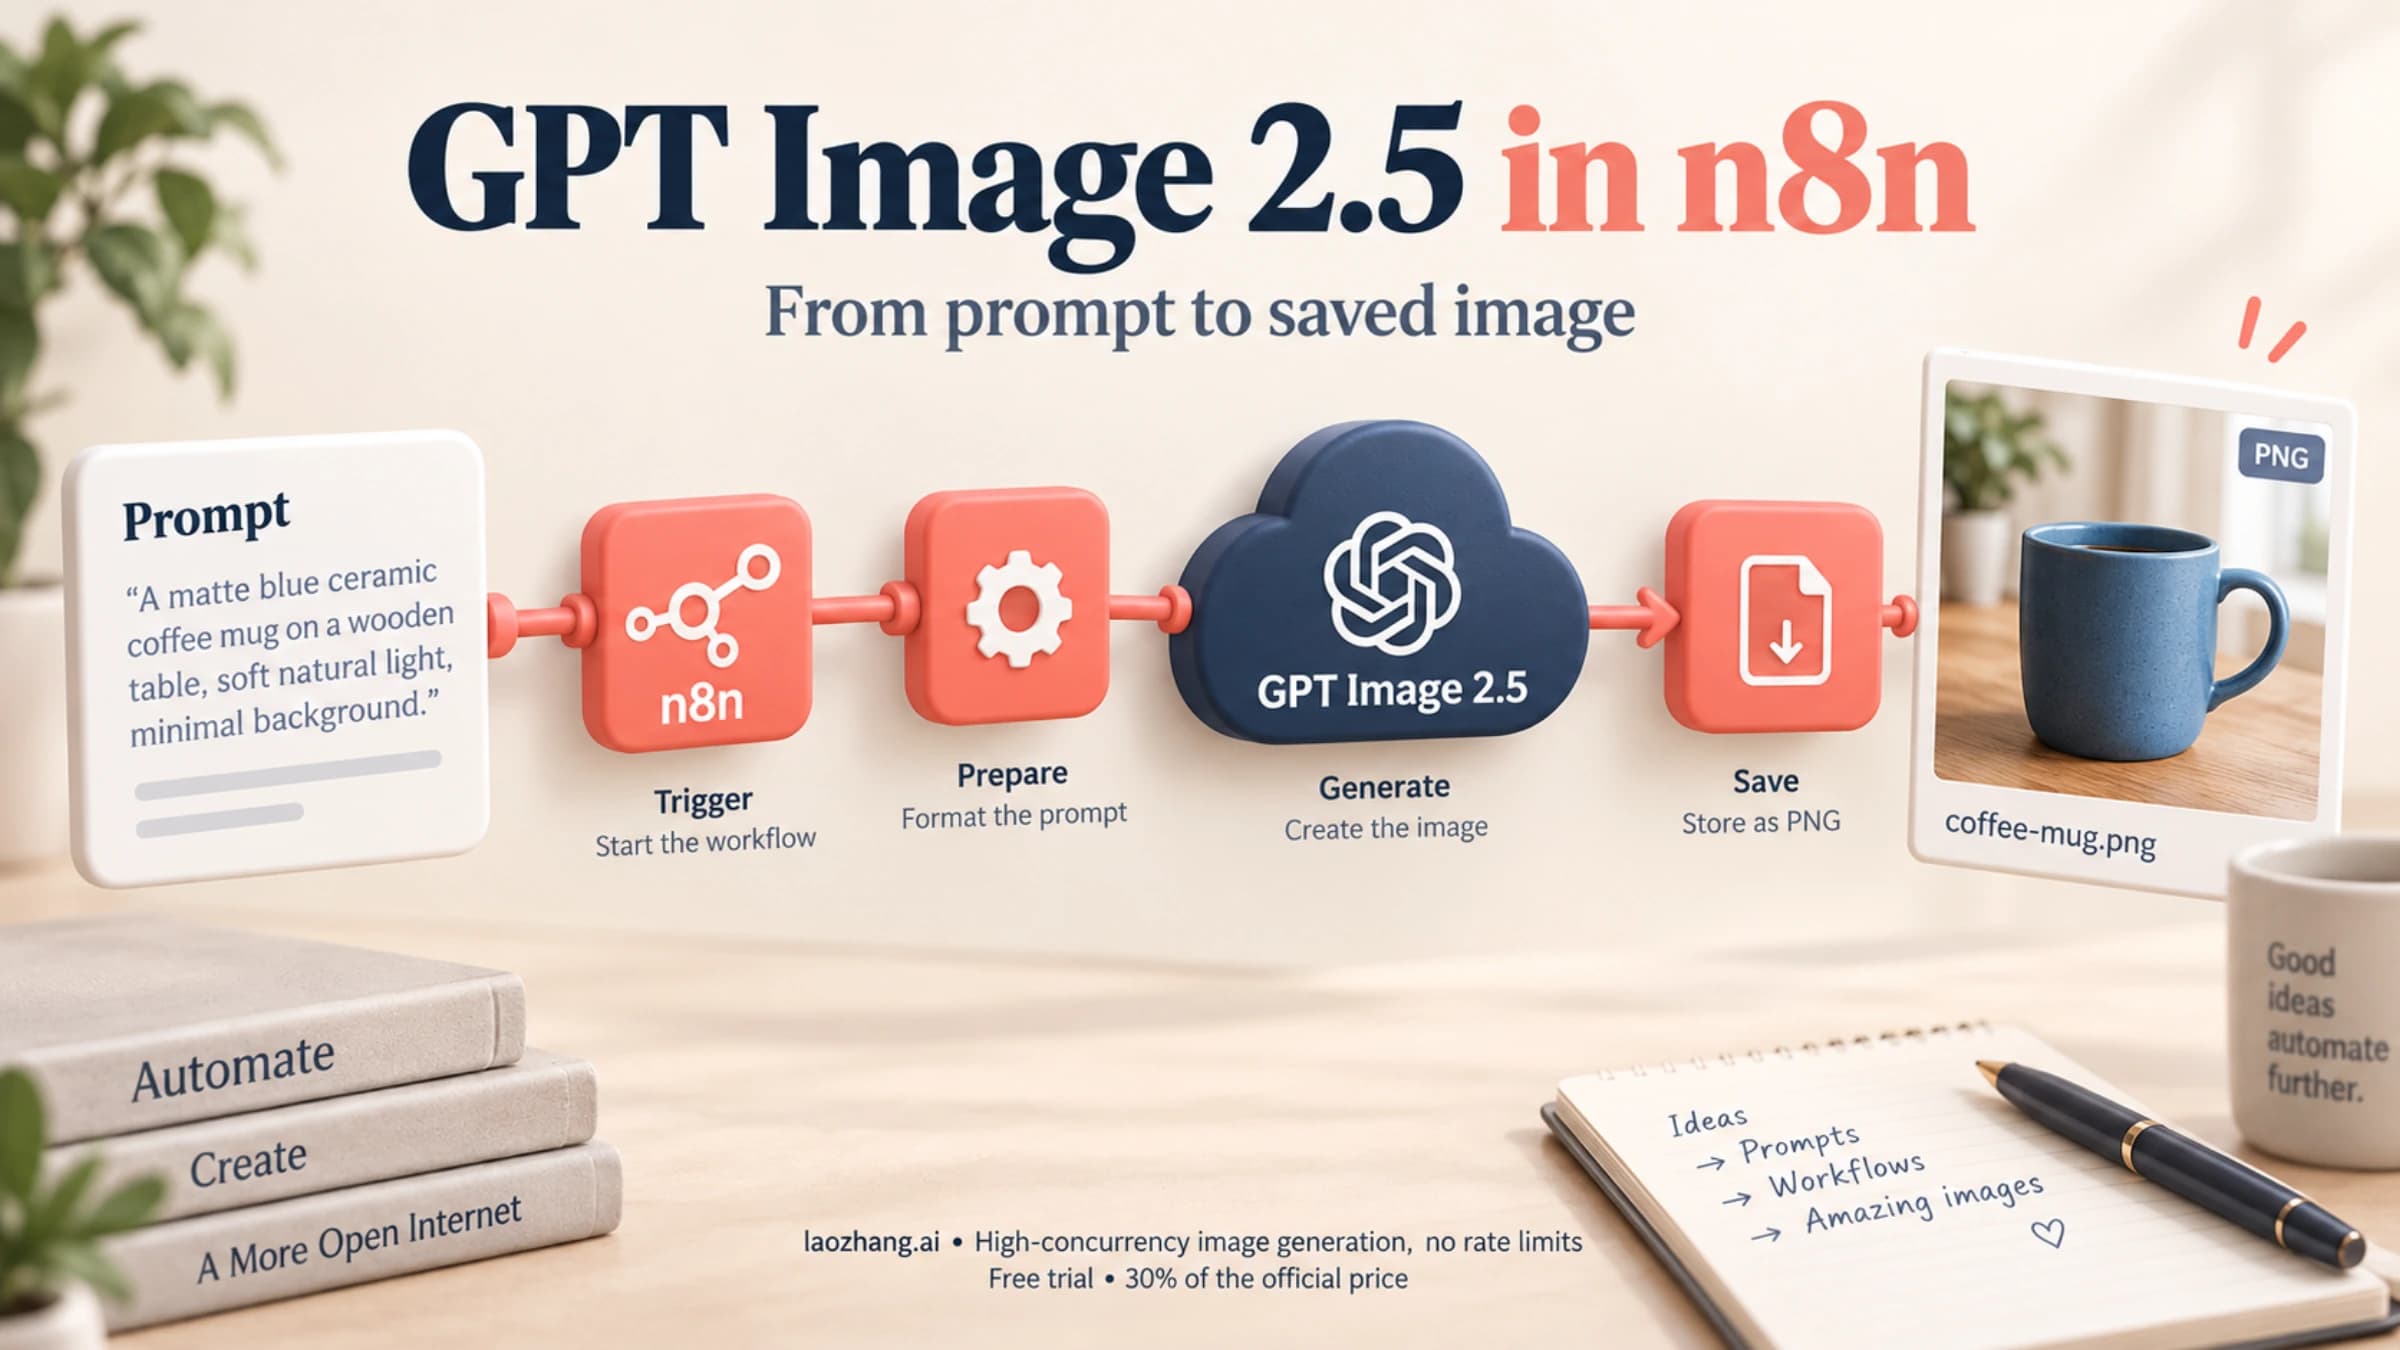
n8n's OpenAI node runs GPT Image 2.5 up to high quality and 1536 px but drops token usage. For xhigh, 4K, transparency or URL replies, use HTTP Request.
Start with Flare for drafts and volume; use Sunburst when an edit must keep a product or layout intact. Same cost per attempt; tests put Flare 25–45% faster.
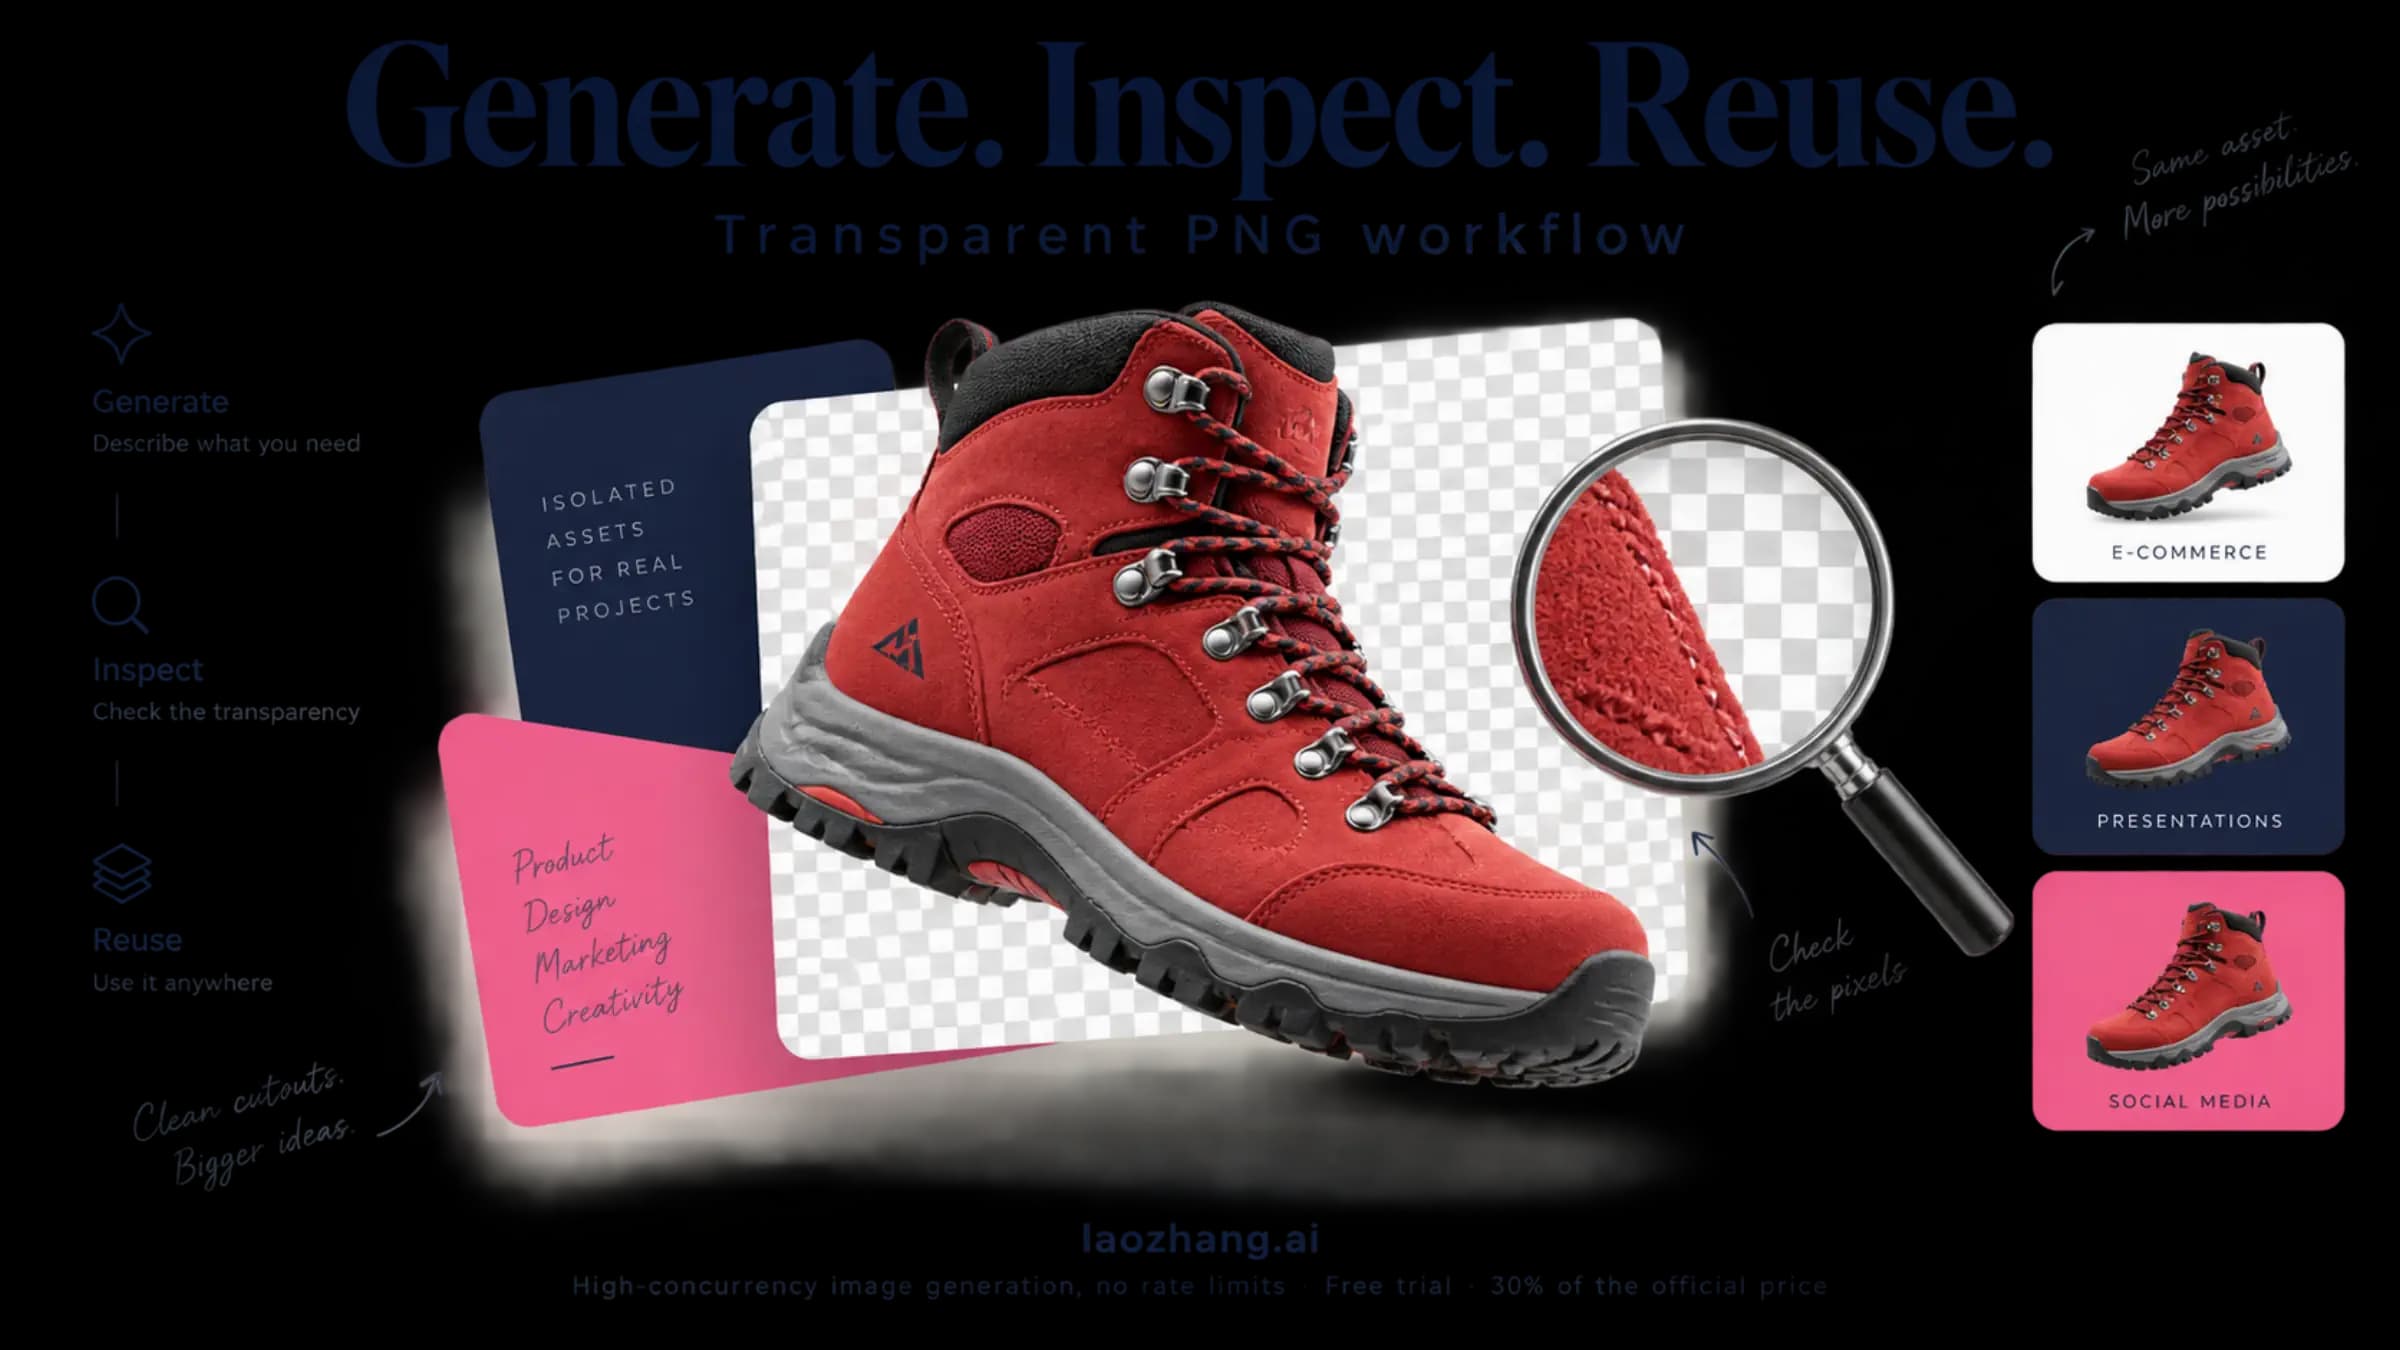
Use a one-color tool for flat logos, a background remover for photos, and ChatGPT for new art. Save as PNG, then test it on a dark background before sending.
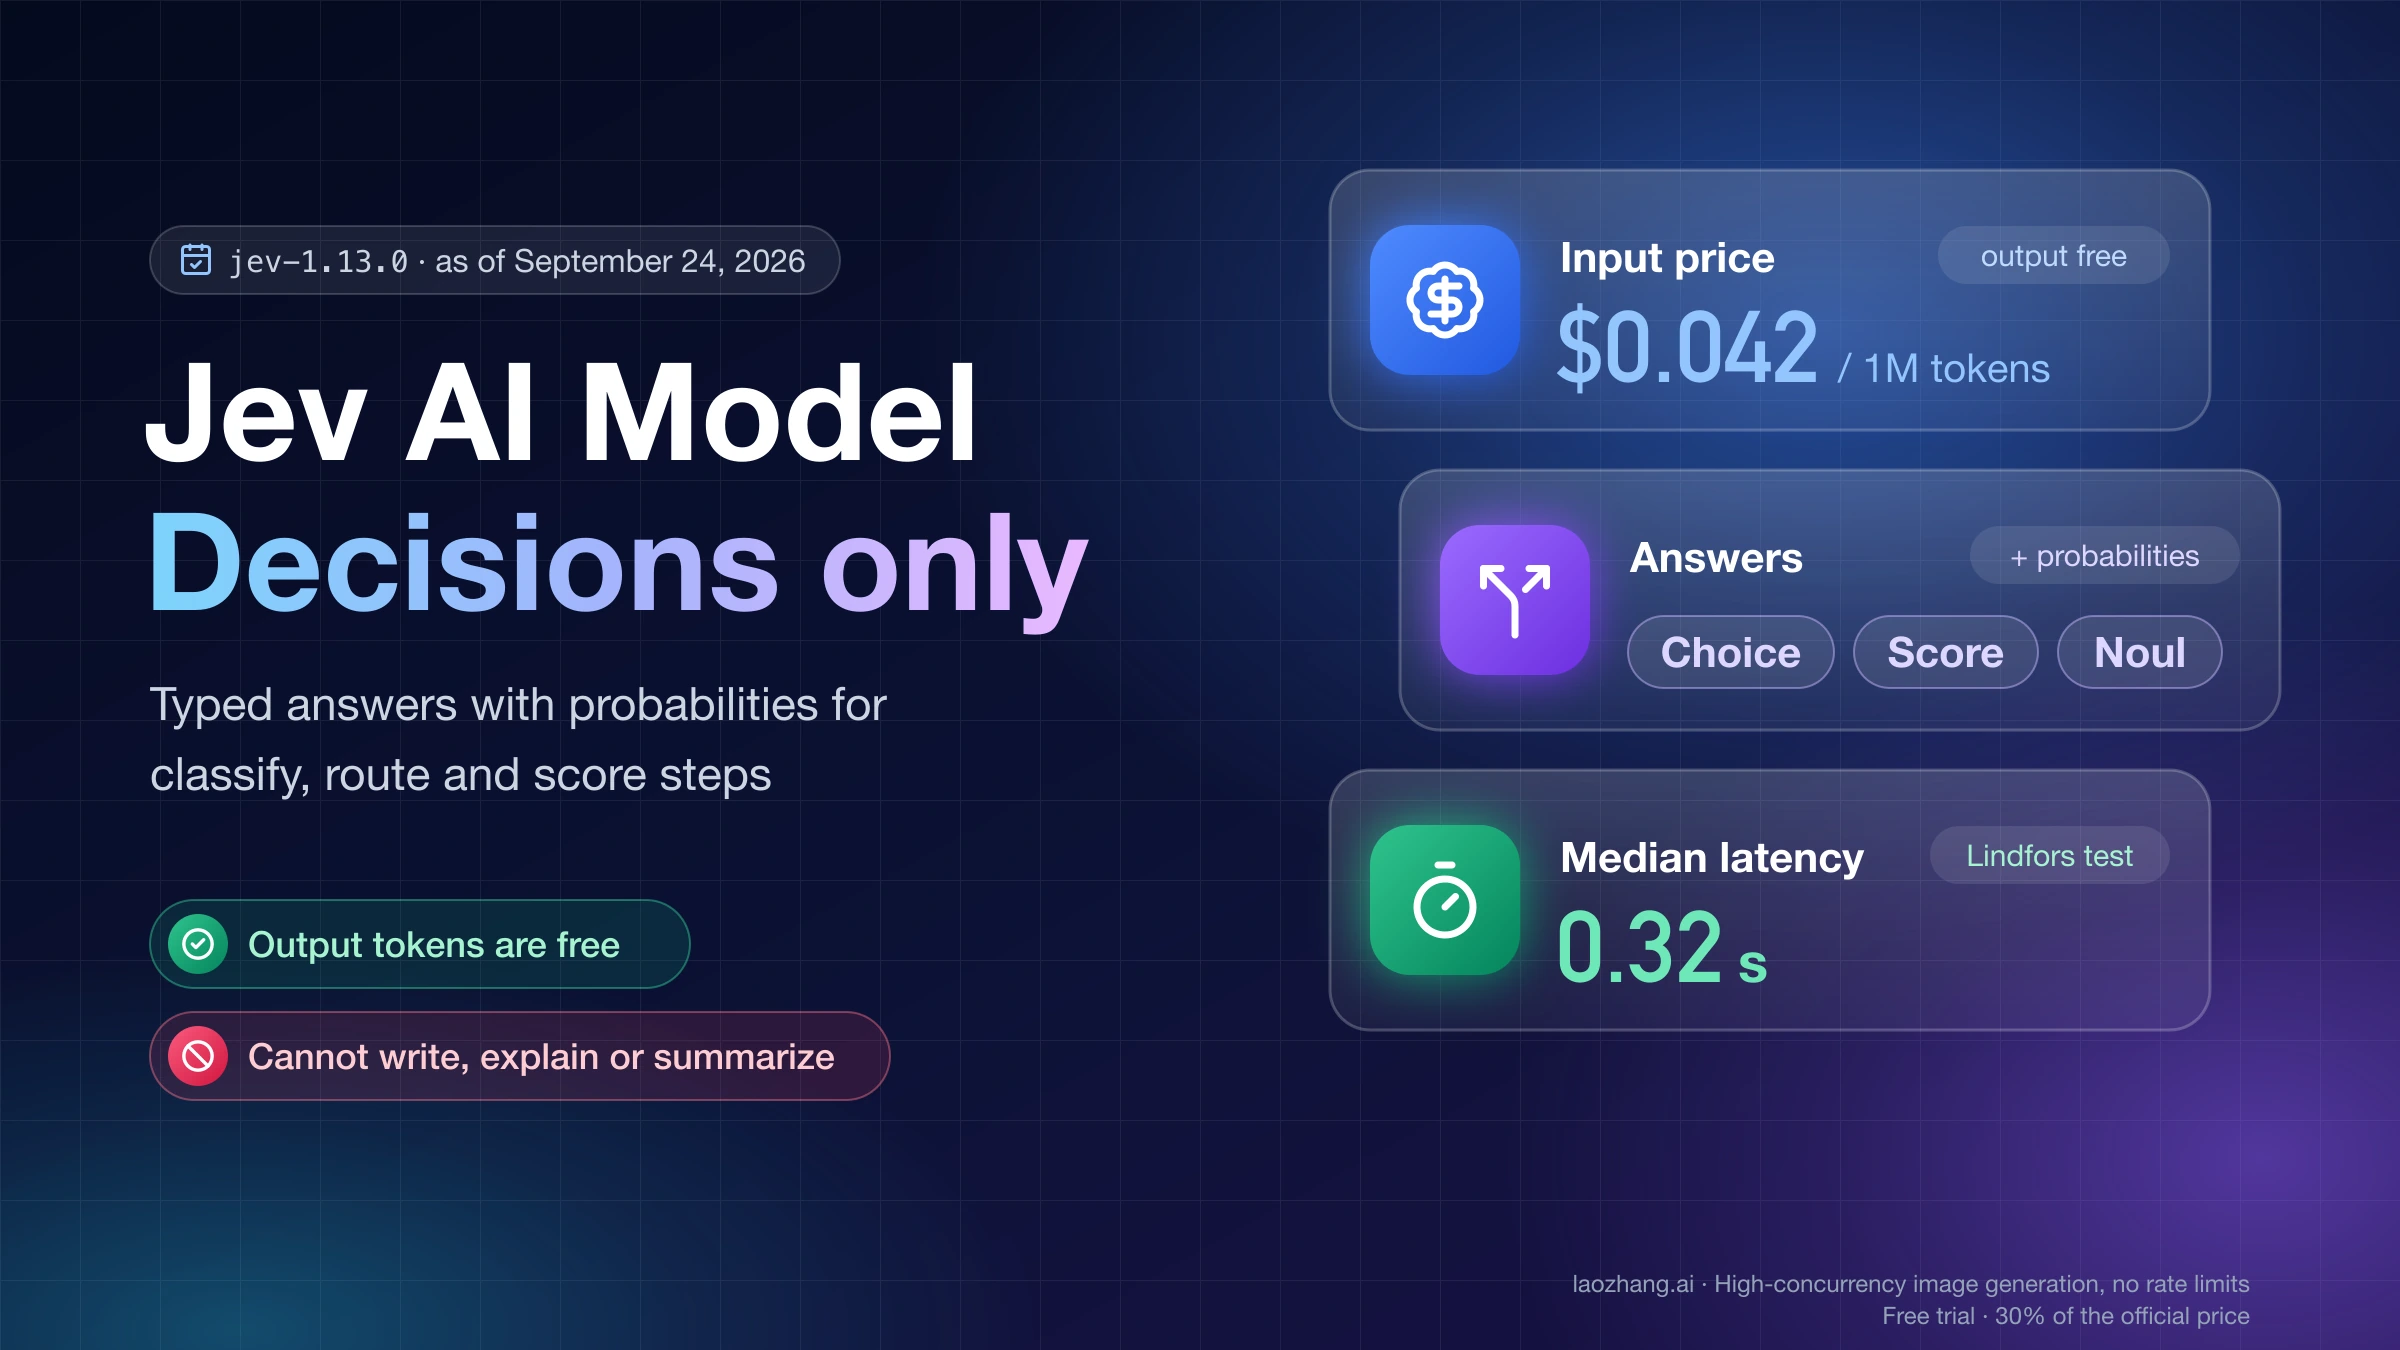
Jev from TypeSafe AI returns a choice, score or yes-probability instead of text, for $0.042 per million input tokens. It suits narrow decisions, not writing.
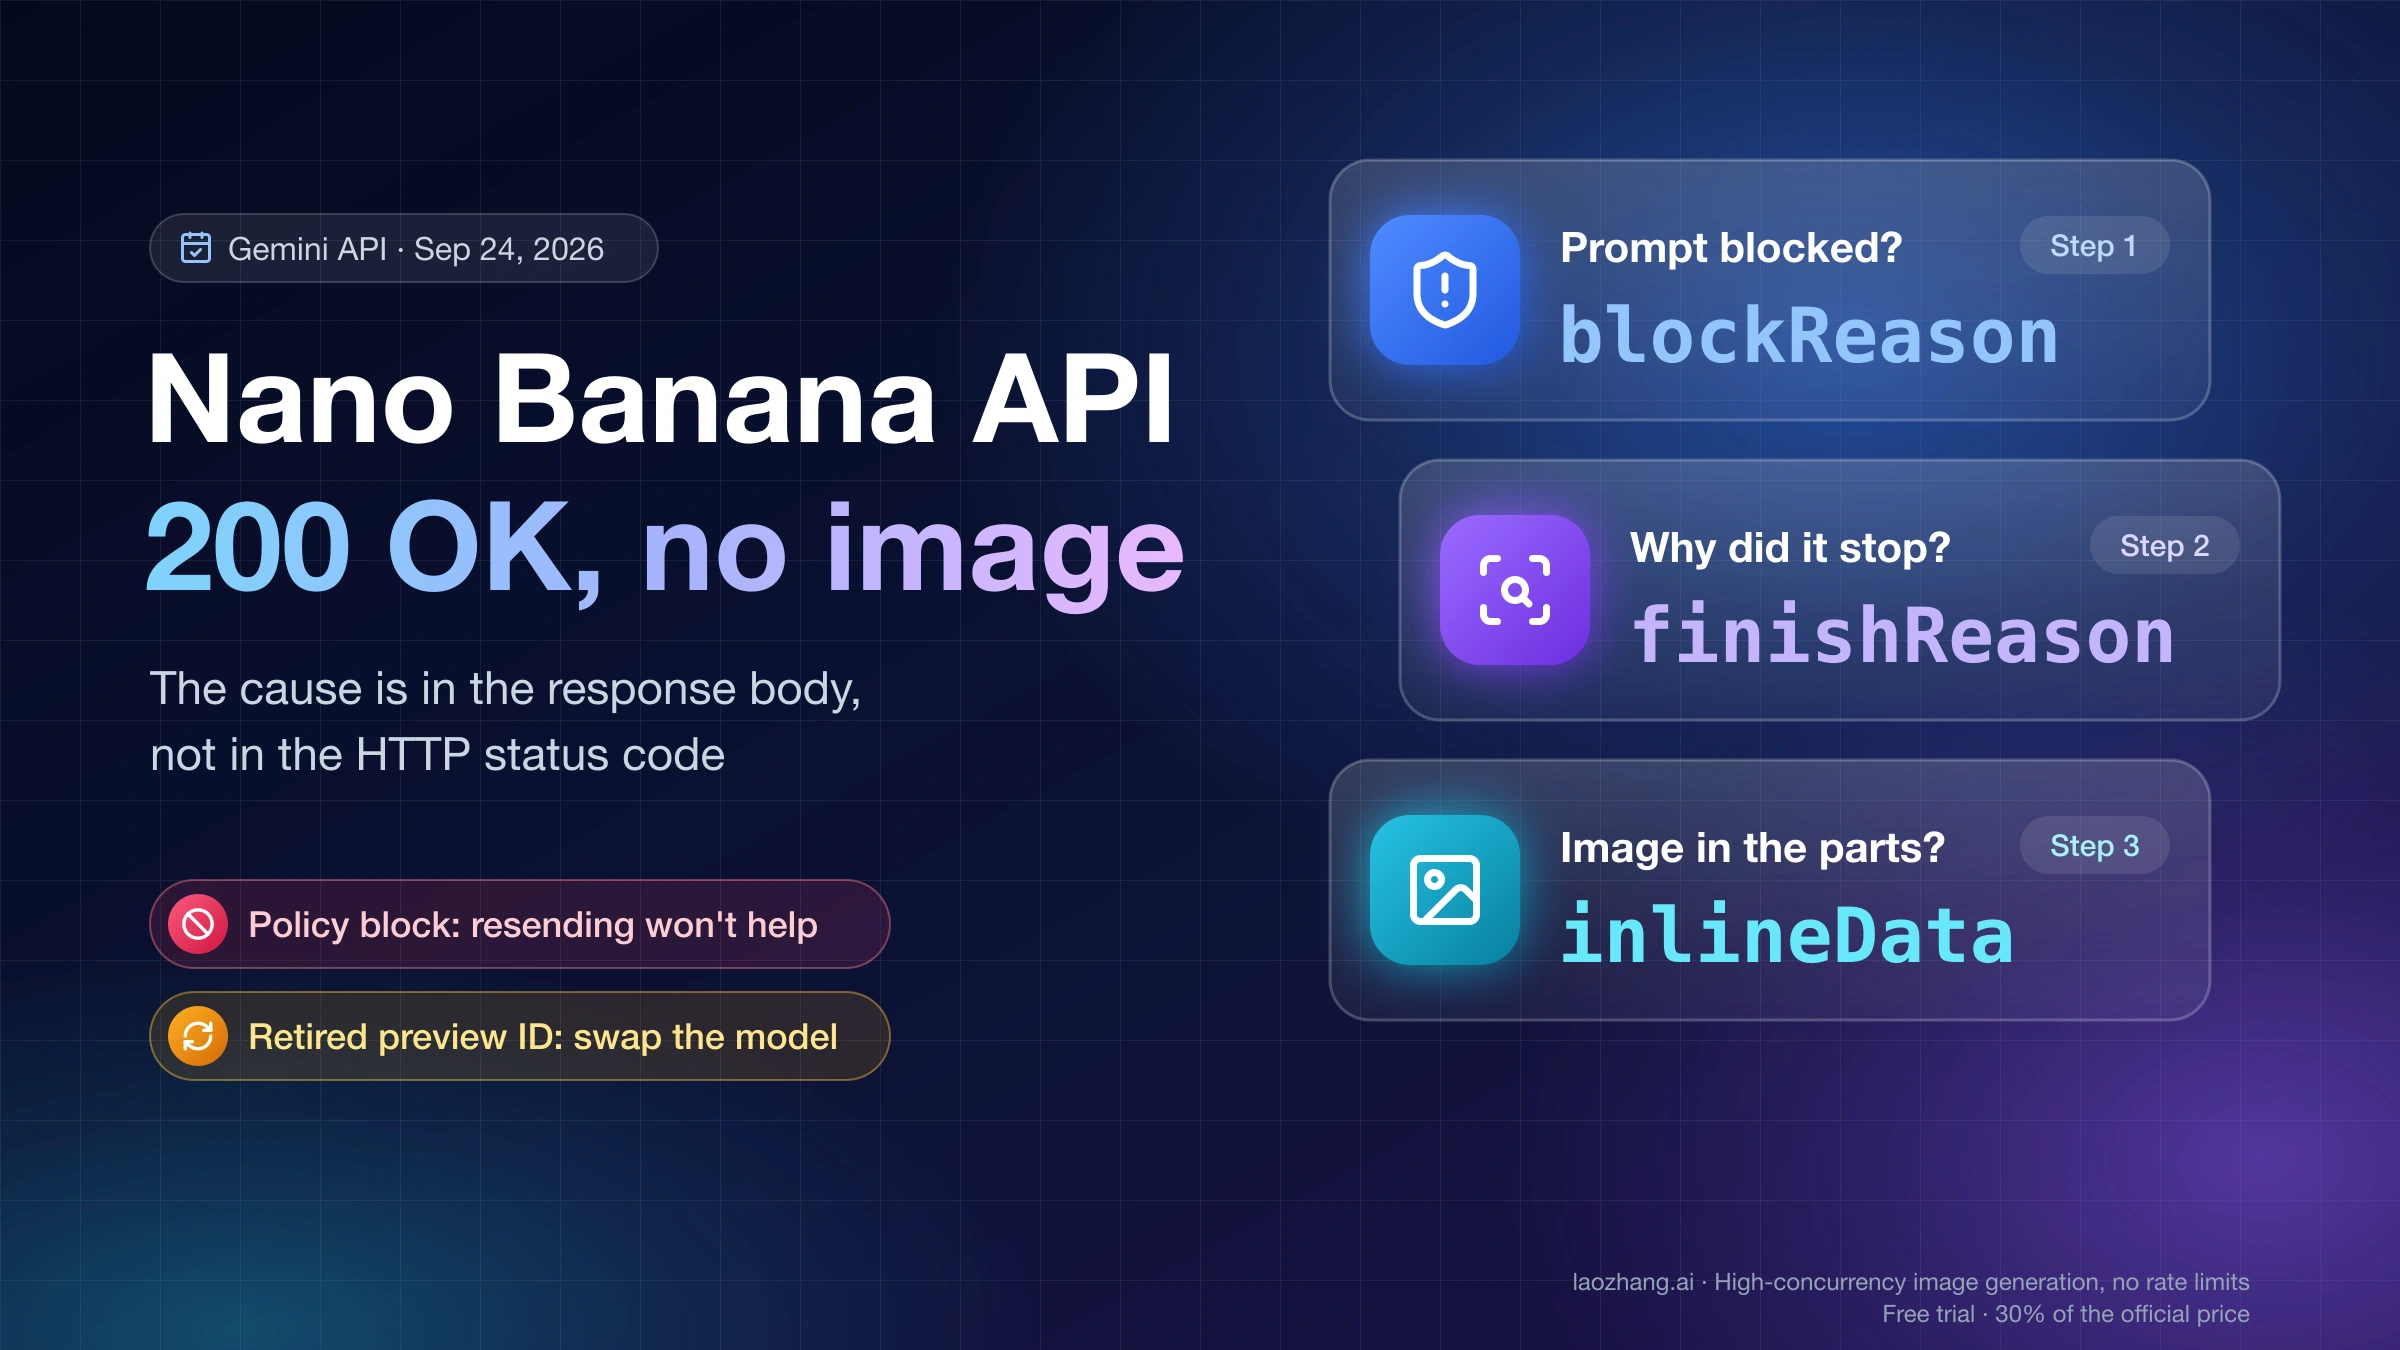
No image from the Nano Banana API usually means a text-only reply, a policy block or cut-off output. The raw response shows which, and whether a retry helps.
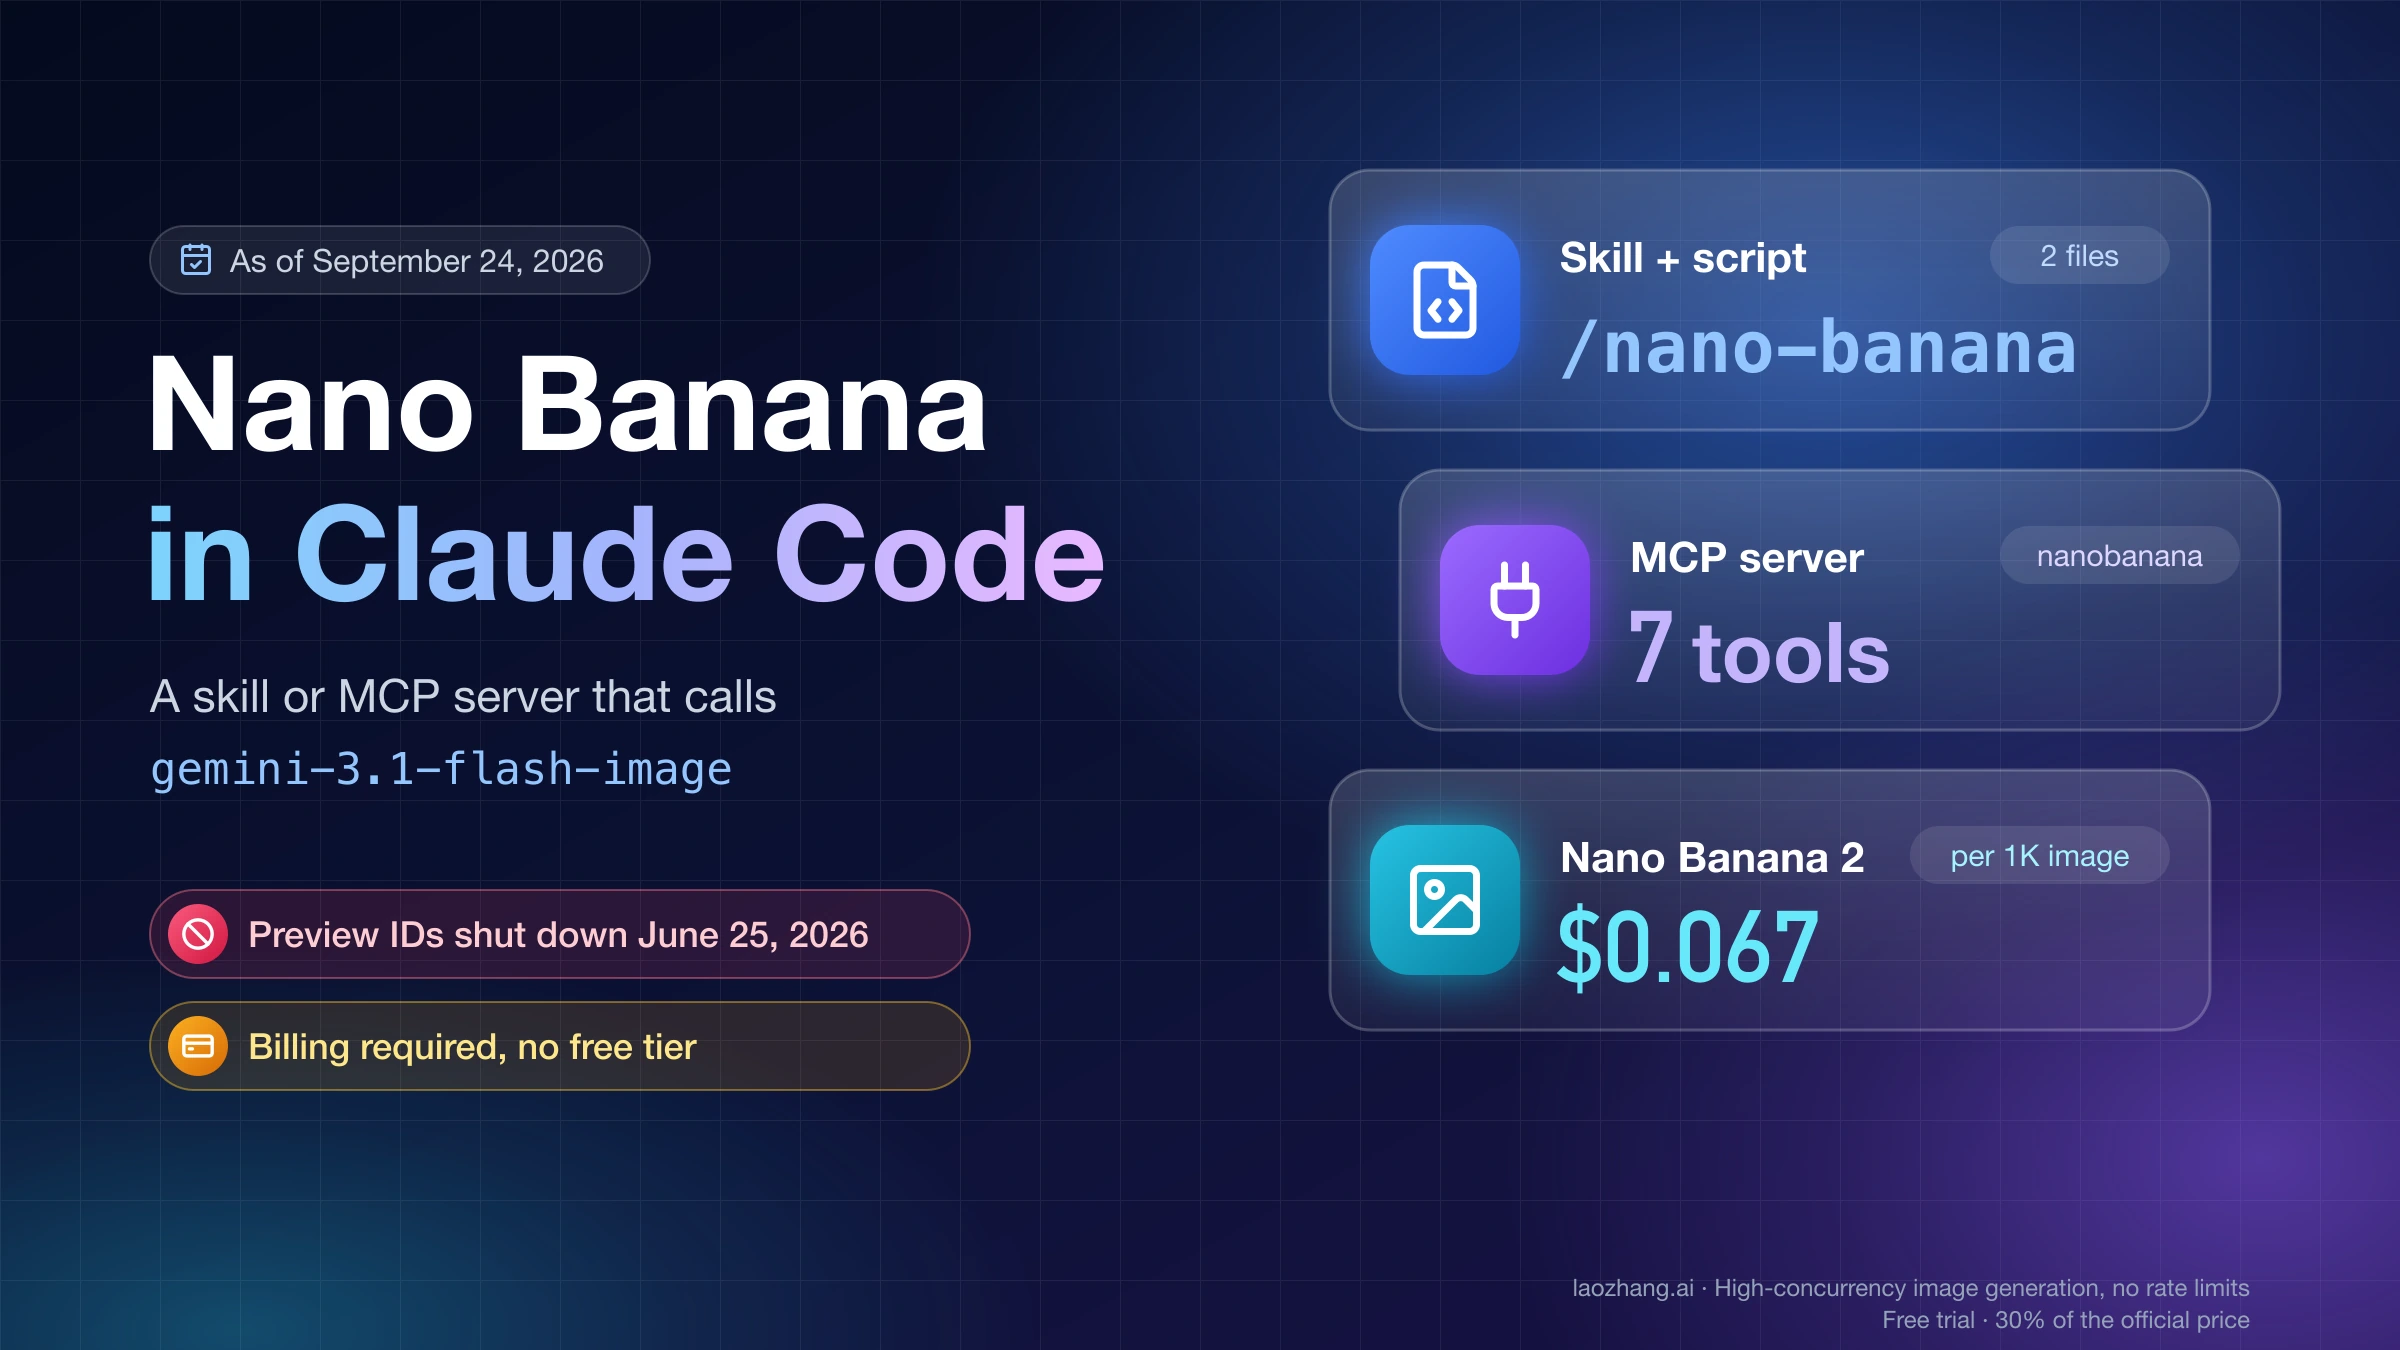
Use a Claude Code skill or MCP server that calls gemini-3.1-flash-image. Preview IDs shut down June 25, 2026; billing is required, about $0.067 per 1K image.
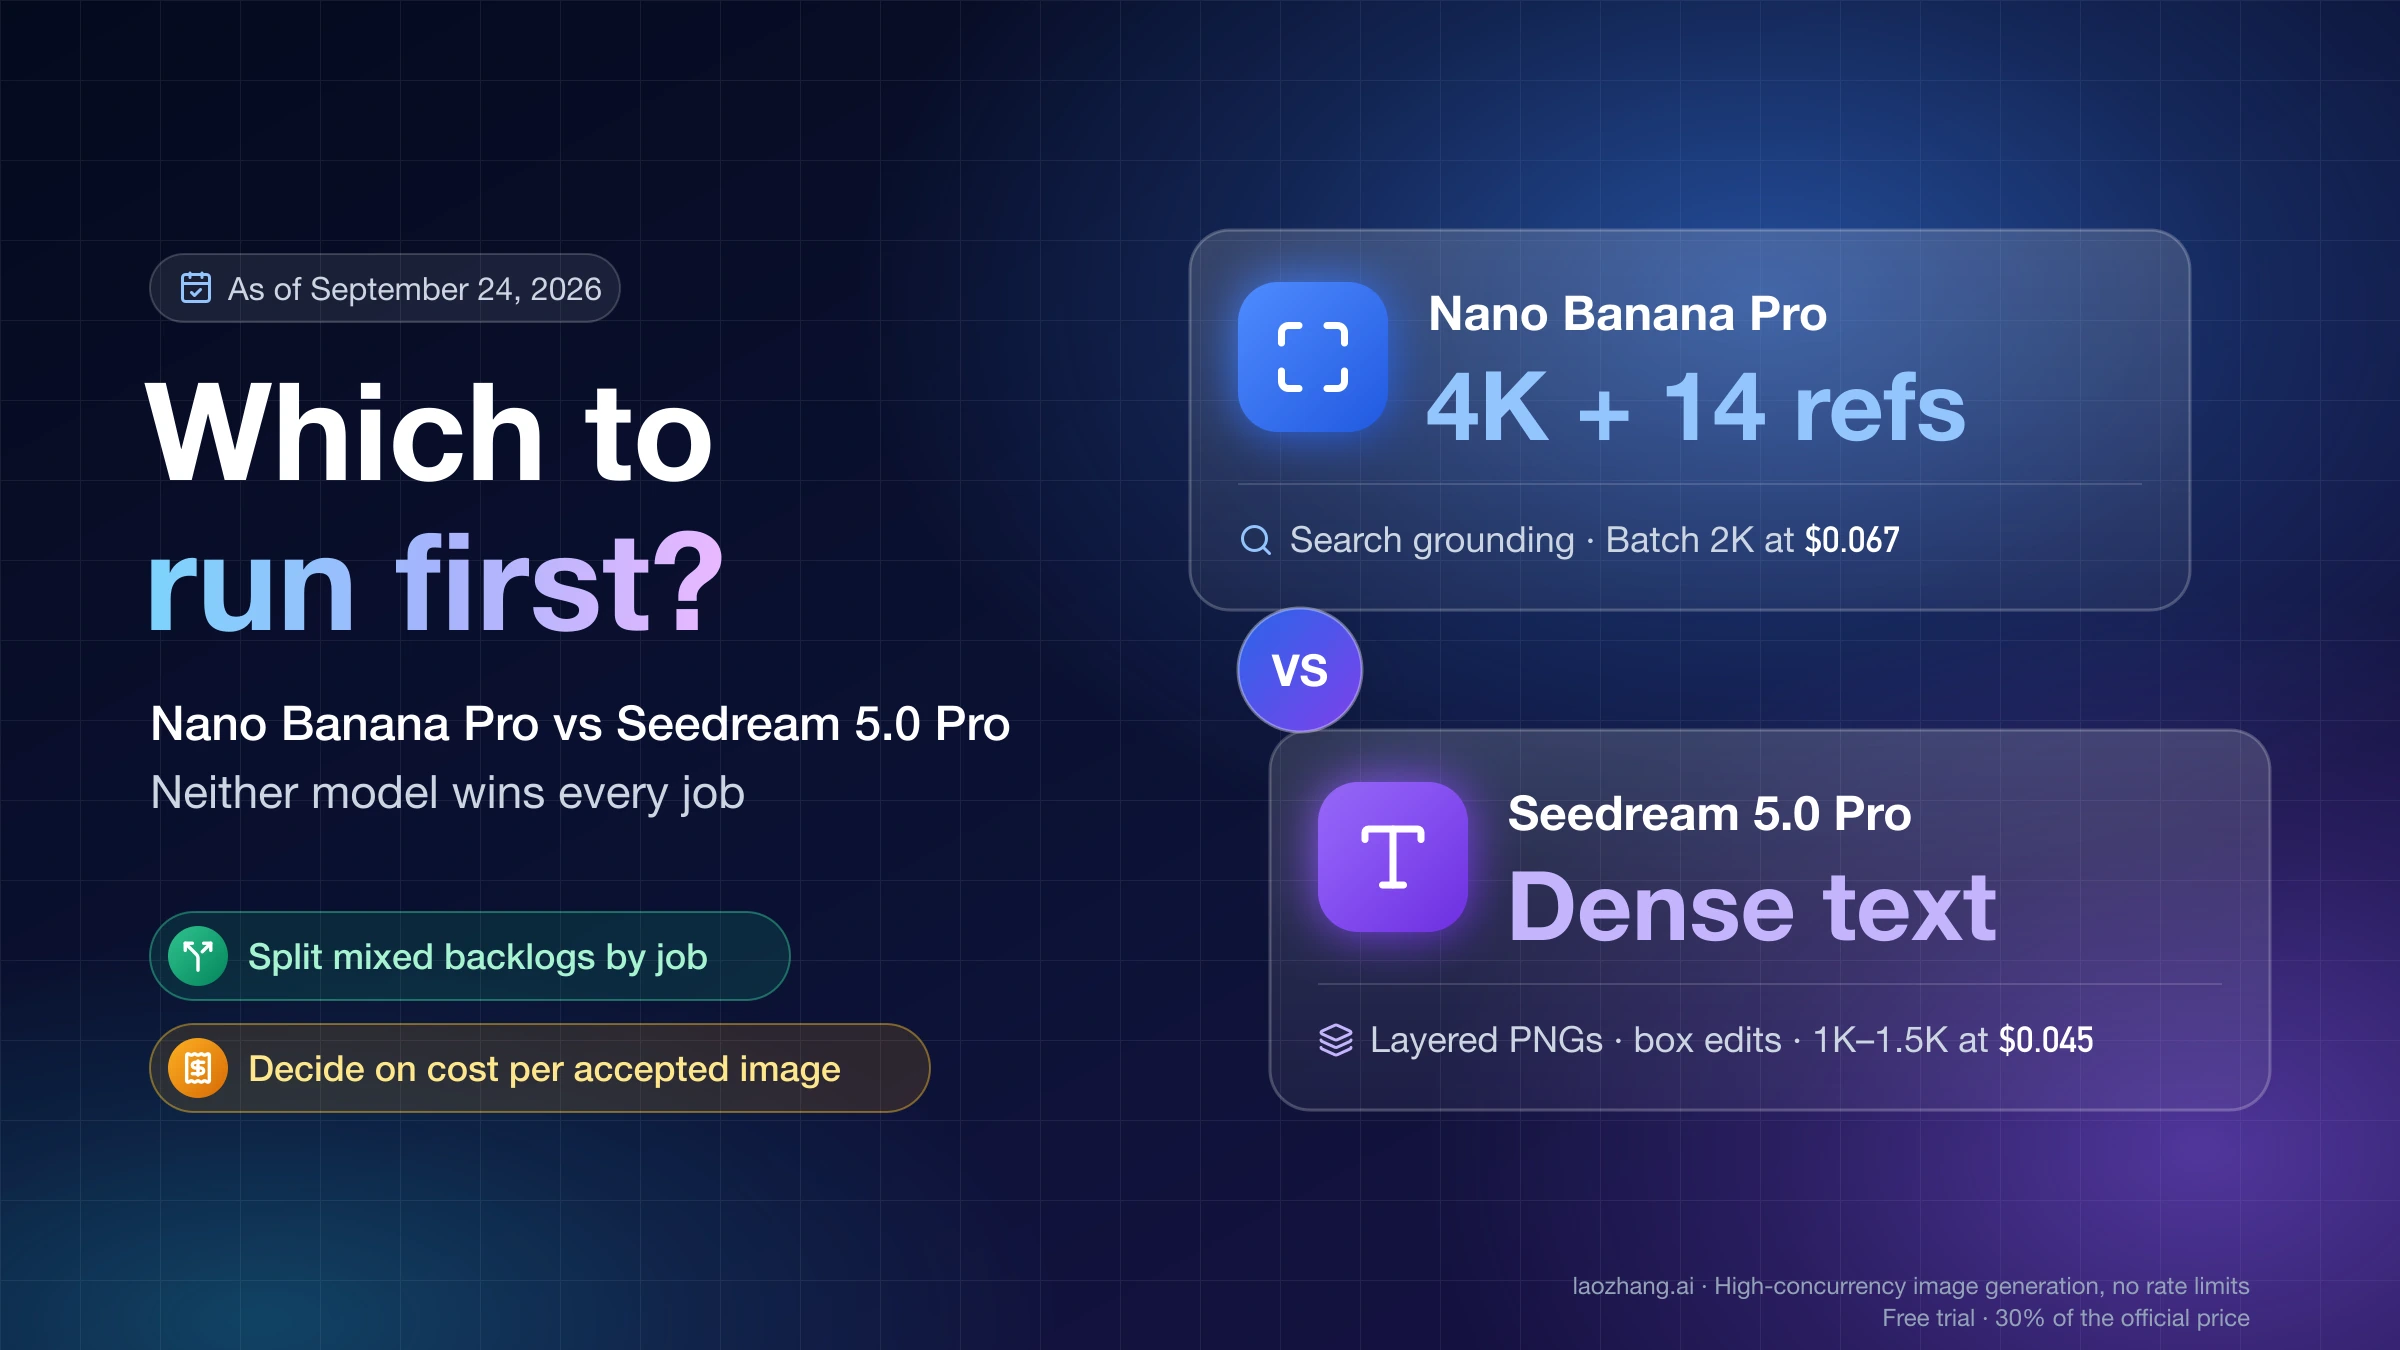
No single winner: Seedream 5.0 Pro costs less per standard 2K attempt and outputs layers; Nano Banana Pro alone offers 4K, 14 references and Search grounding.
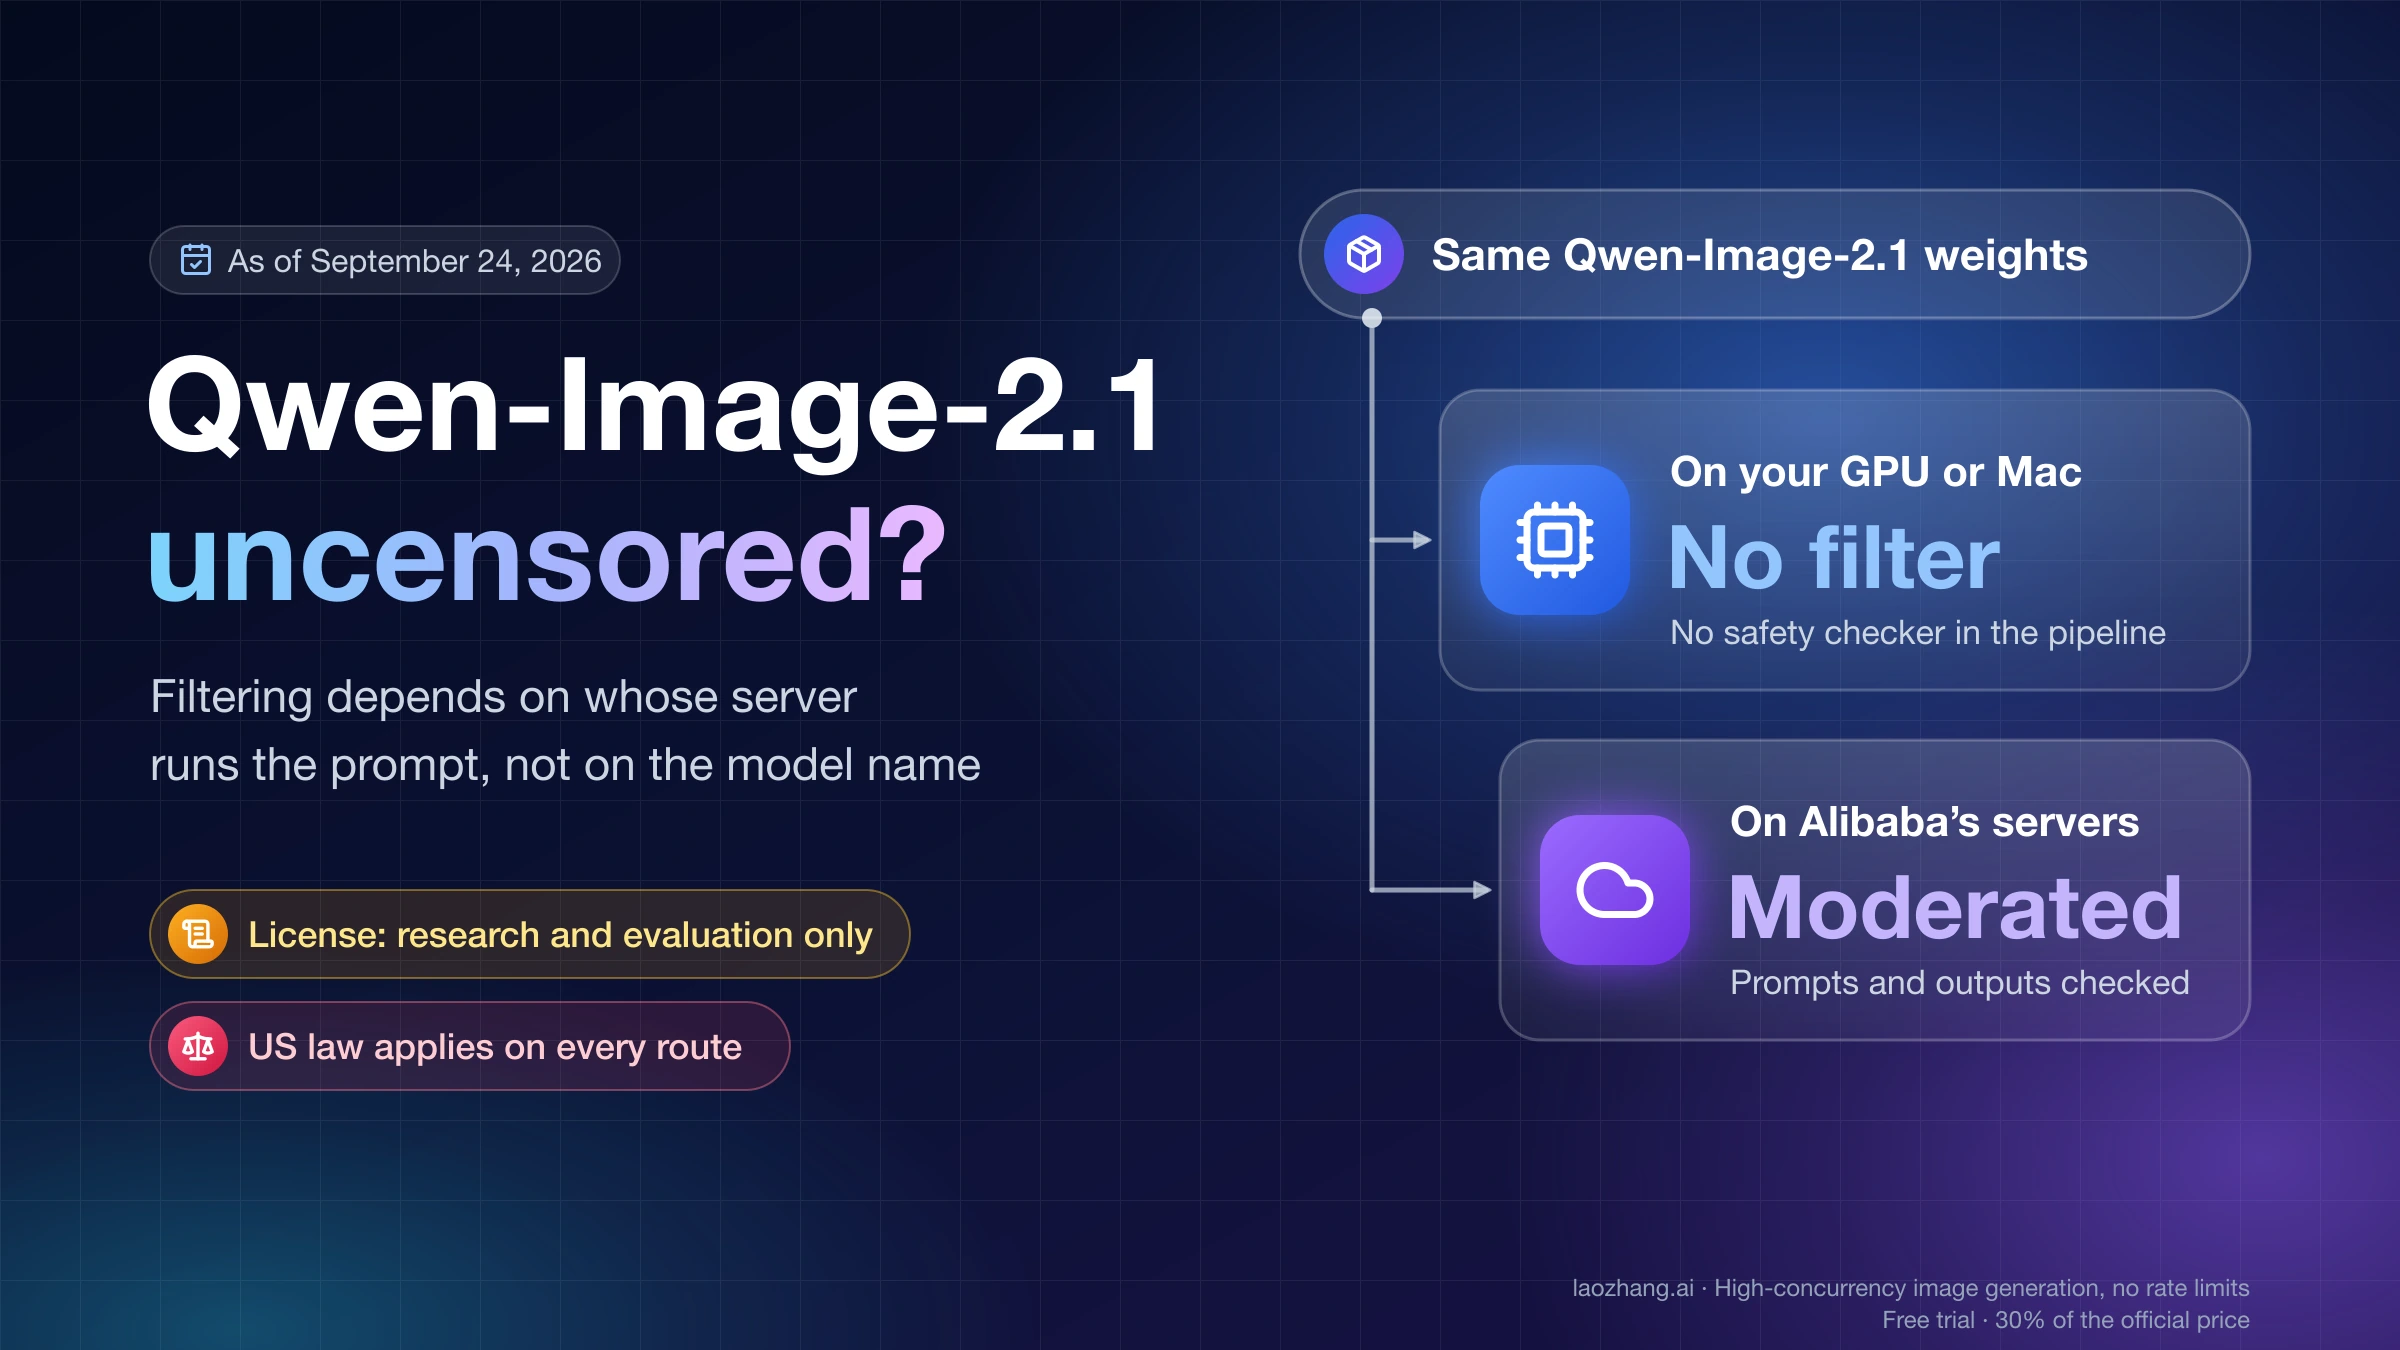
Official Qwen-Image-2.1 weights have no safety checker; Alibaba-hosted versions filter prompts. The “Uncensored GGUF” is the same model, still non-commercial.
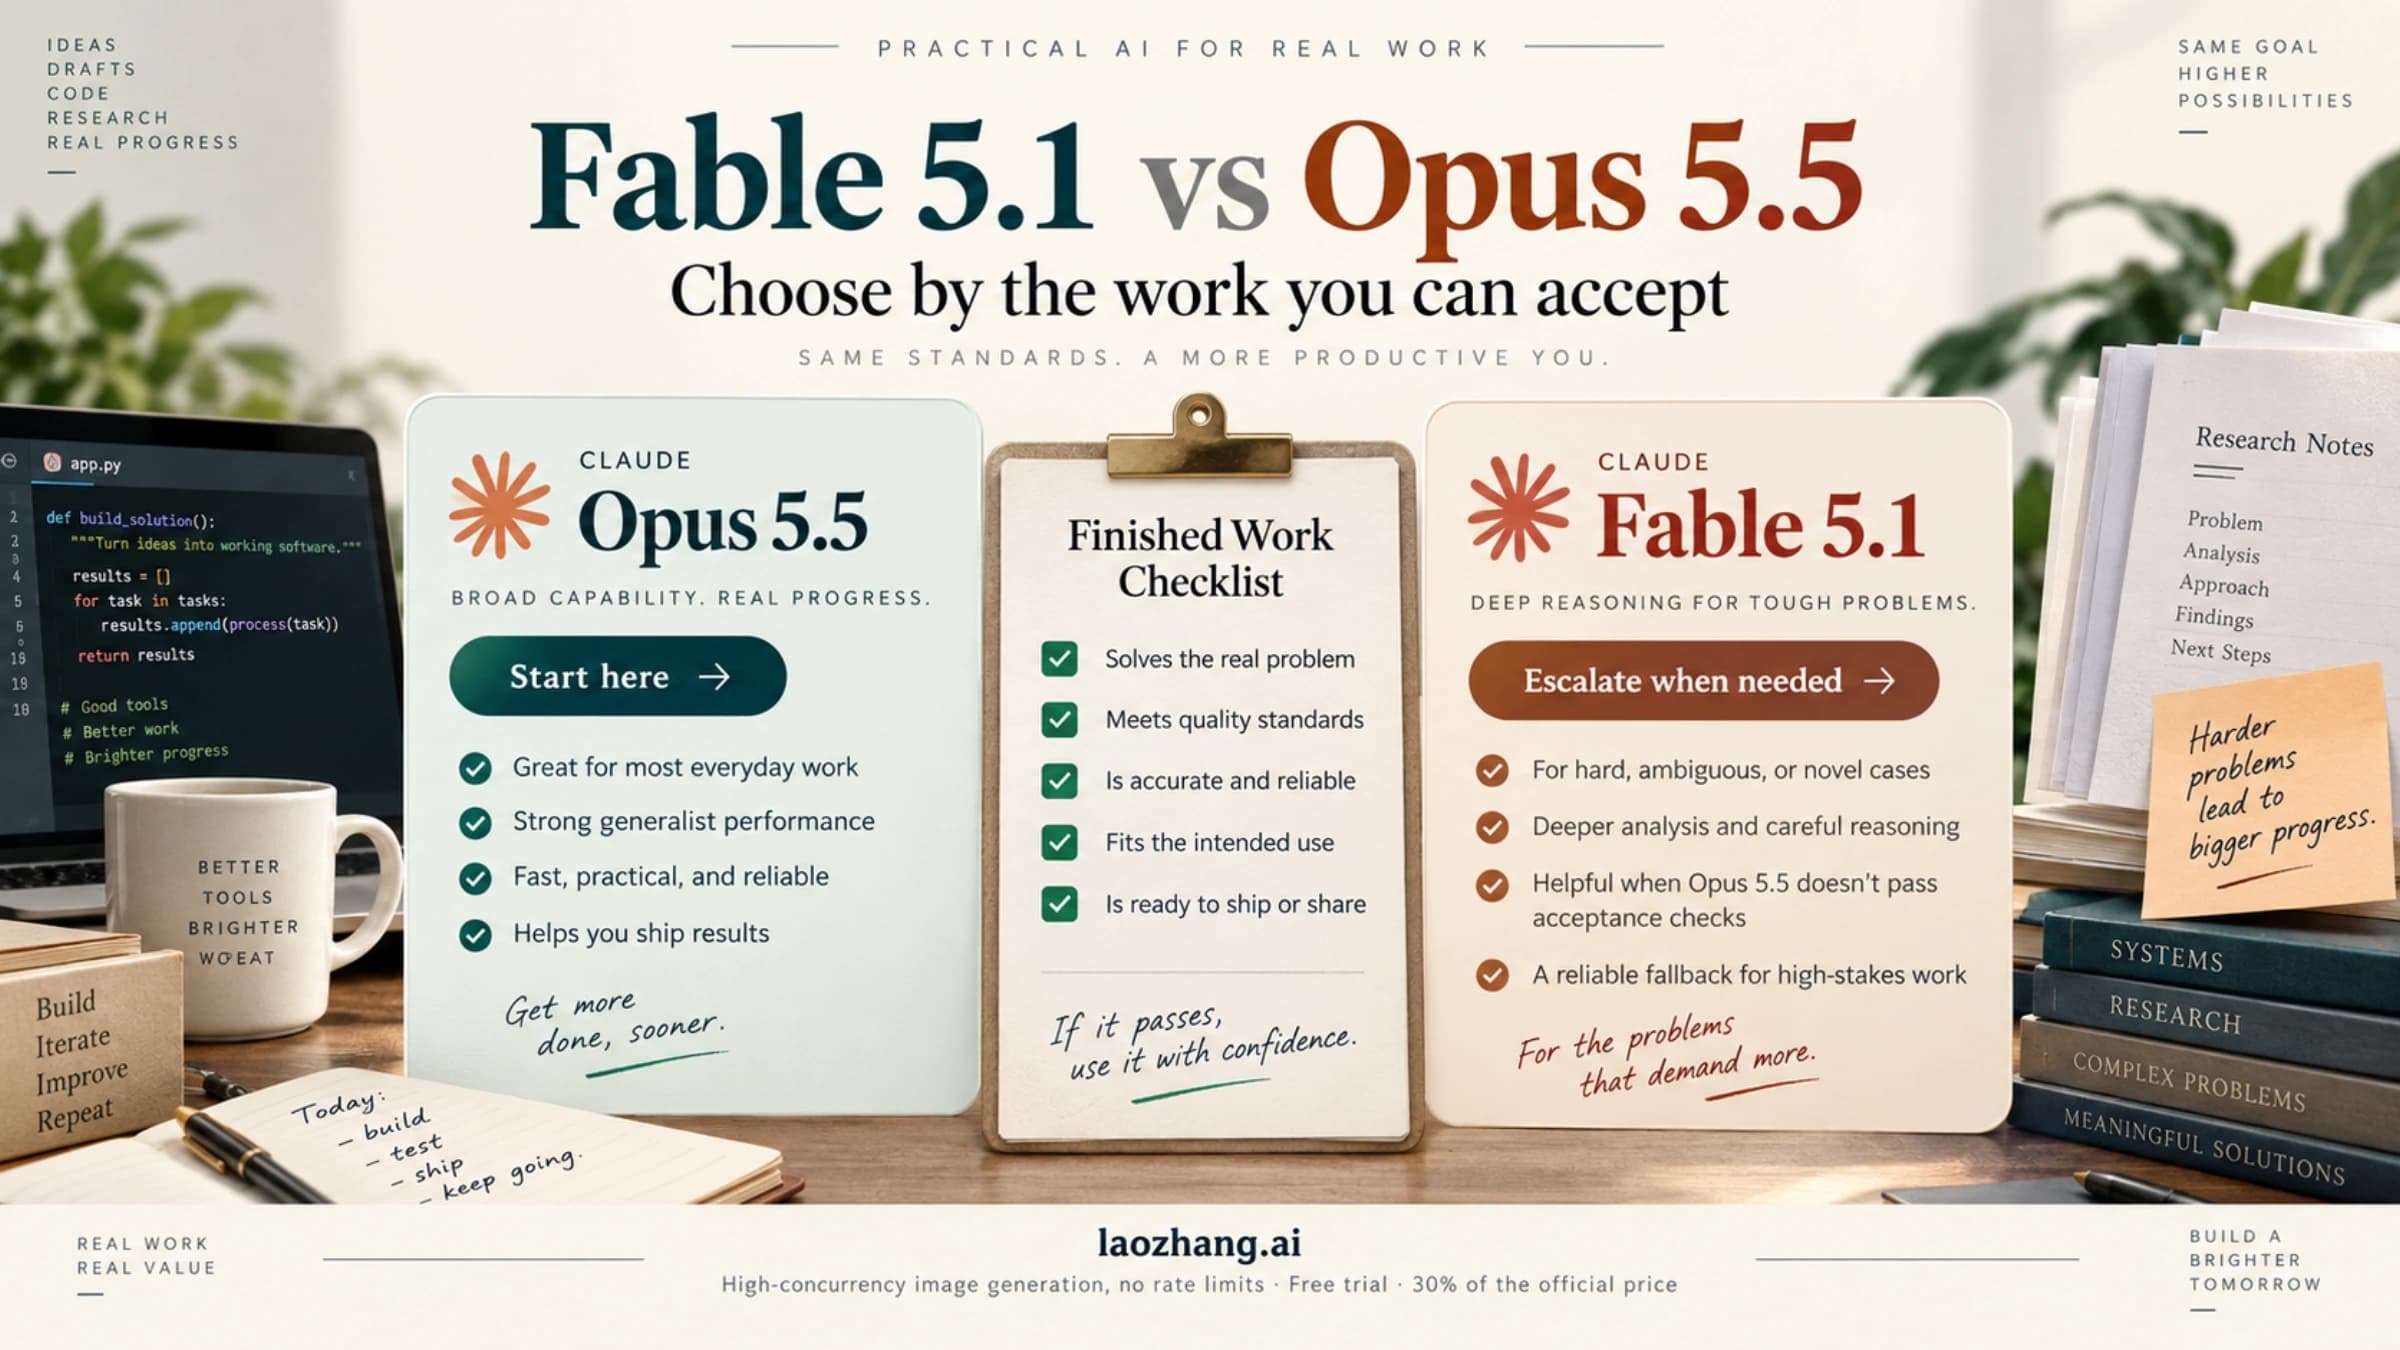
Opus 5.5 is the sensible starting point for most work. Fable 5.1 earns its premium when it solves problems that Opus still misses at higher effort—not simply because the job is long.
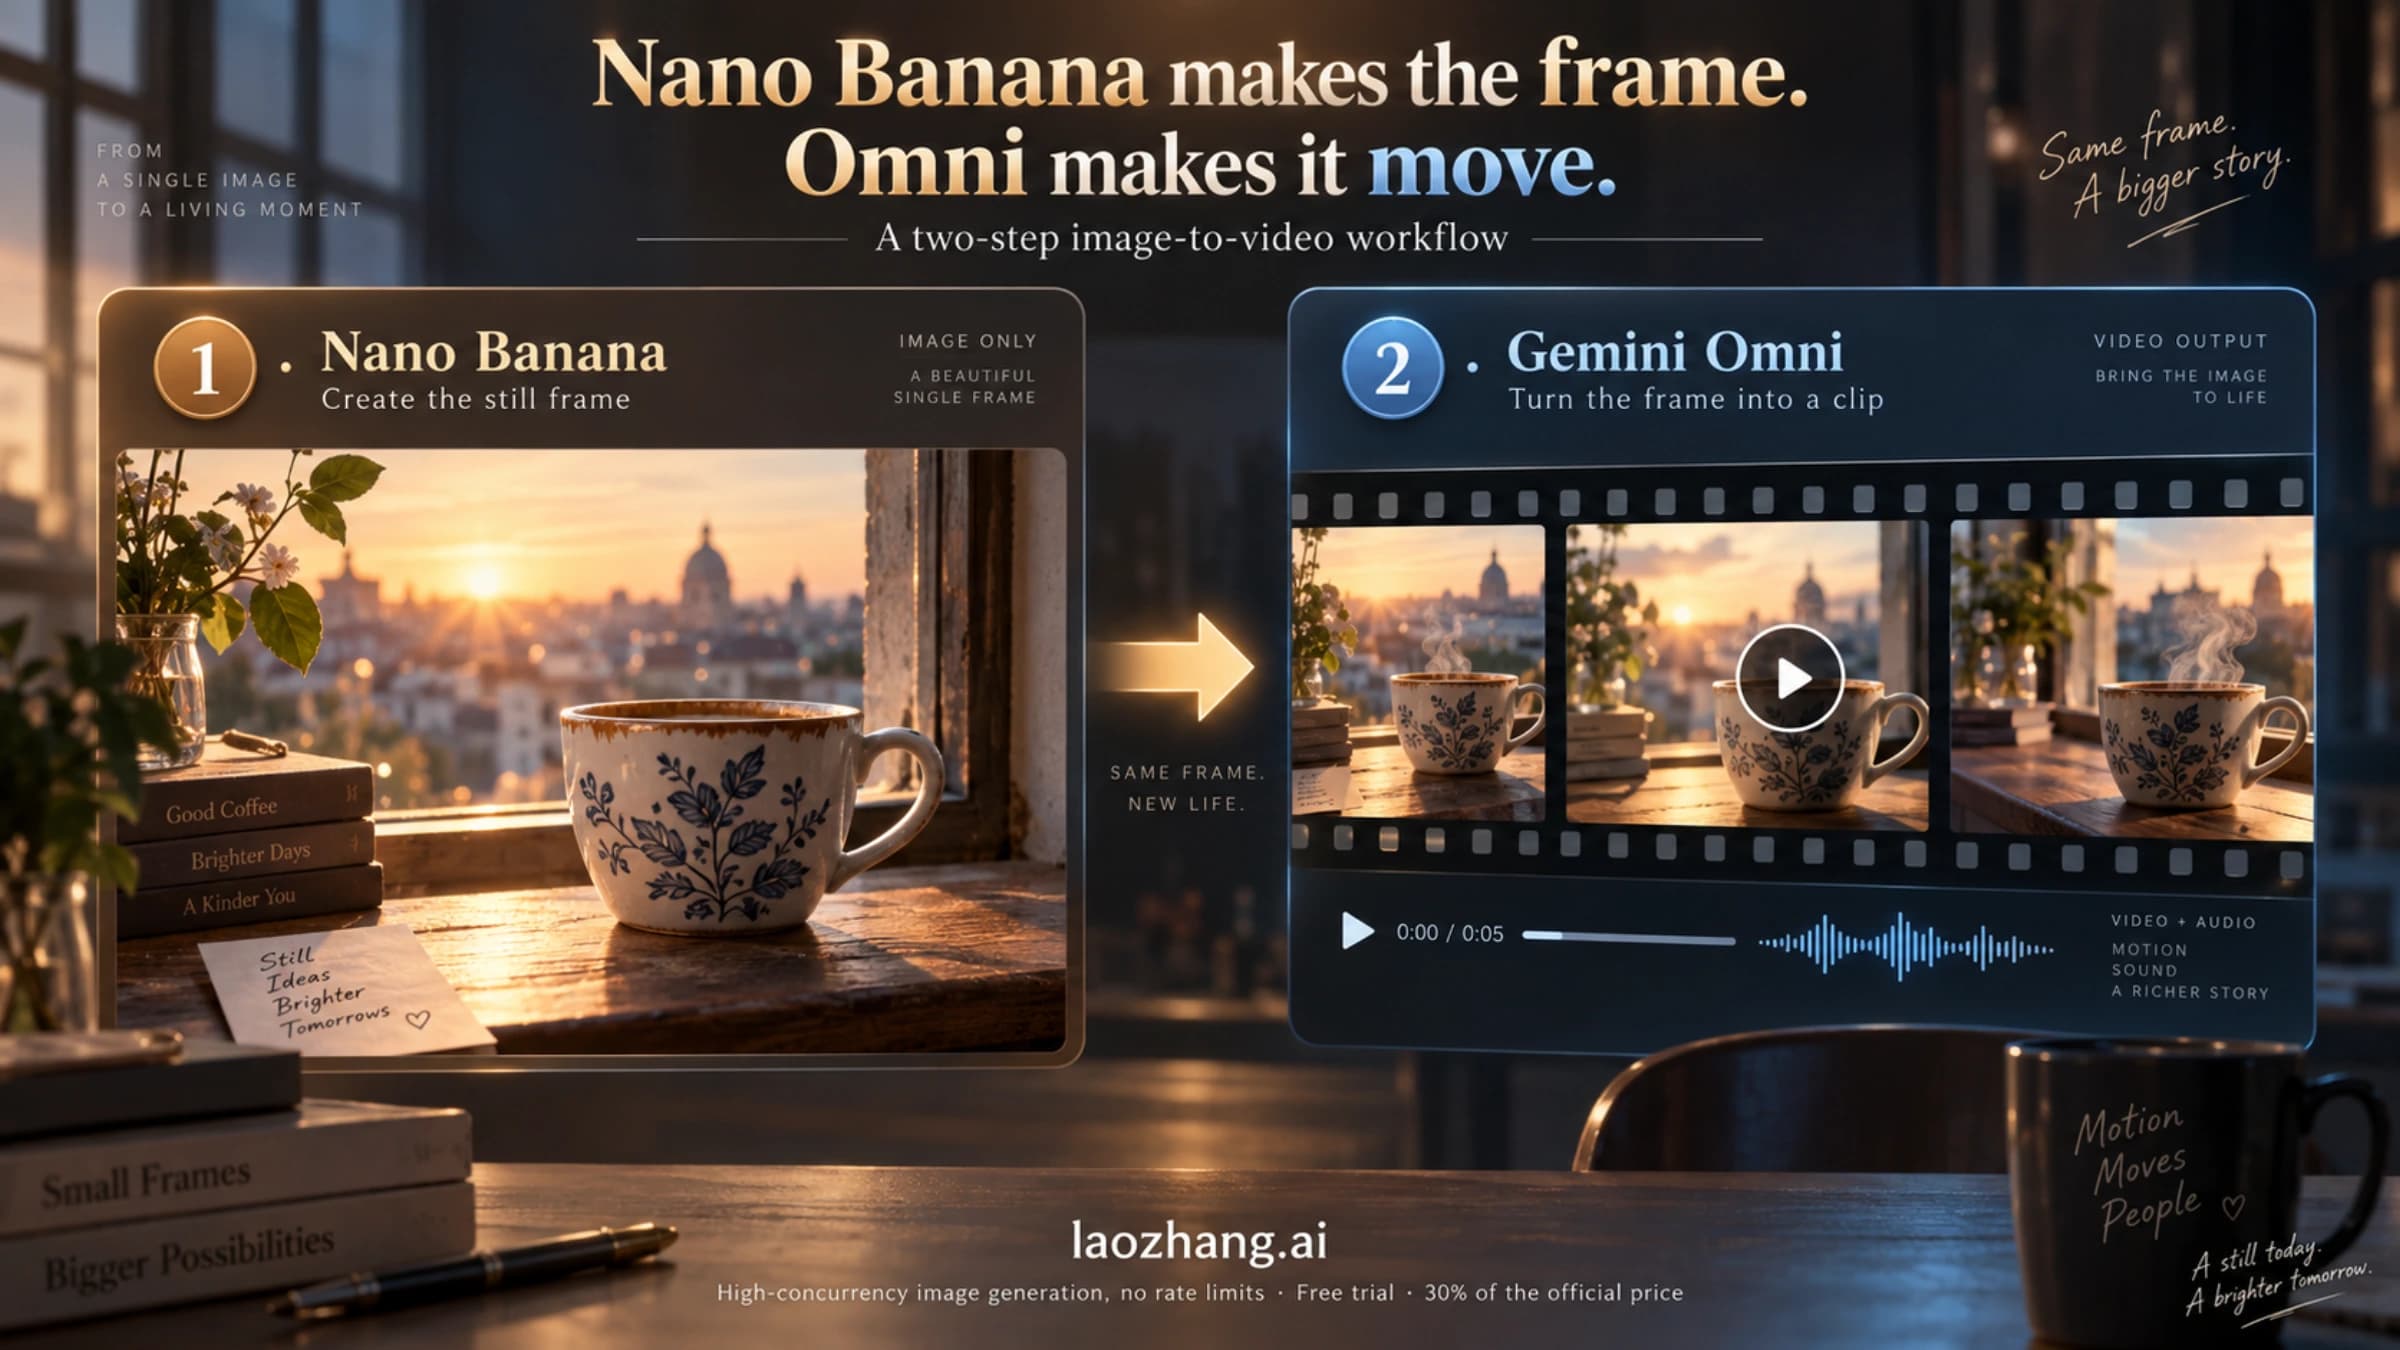
Nano Banana 2, Pro and Lite only make images. To animate a frame, use Gemini Omni (Menu → Videos, or gemini-omni-1.1-flash) or Veo 3.1 for frame control.
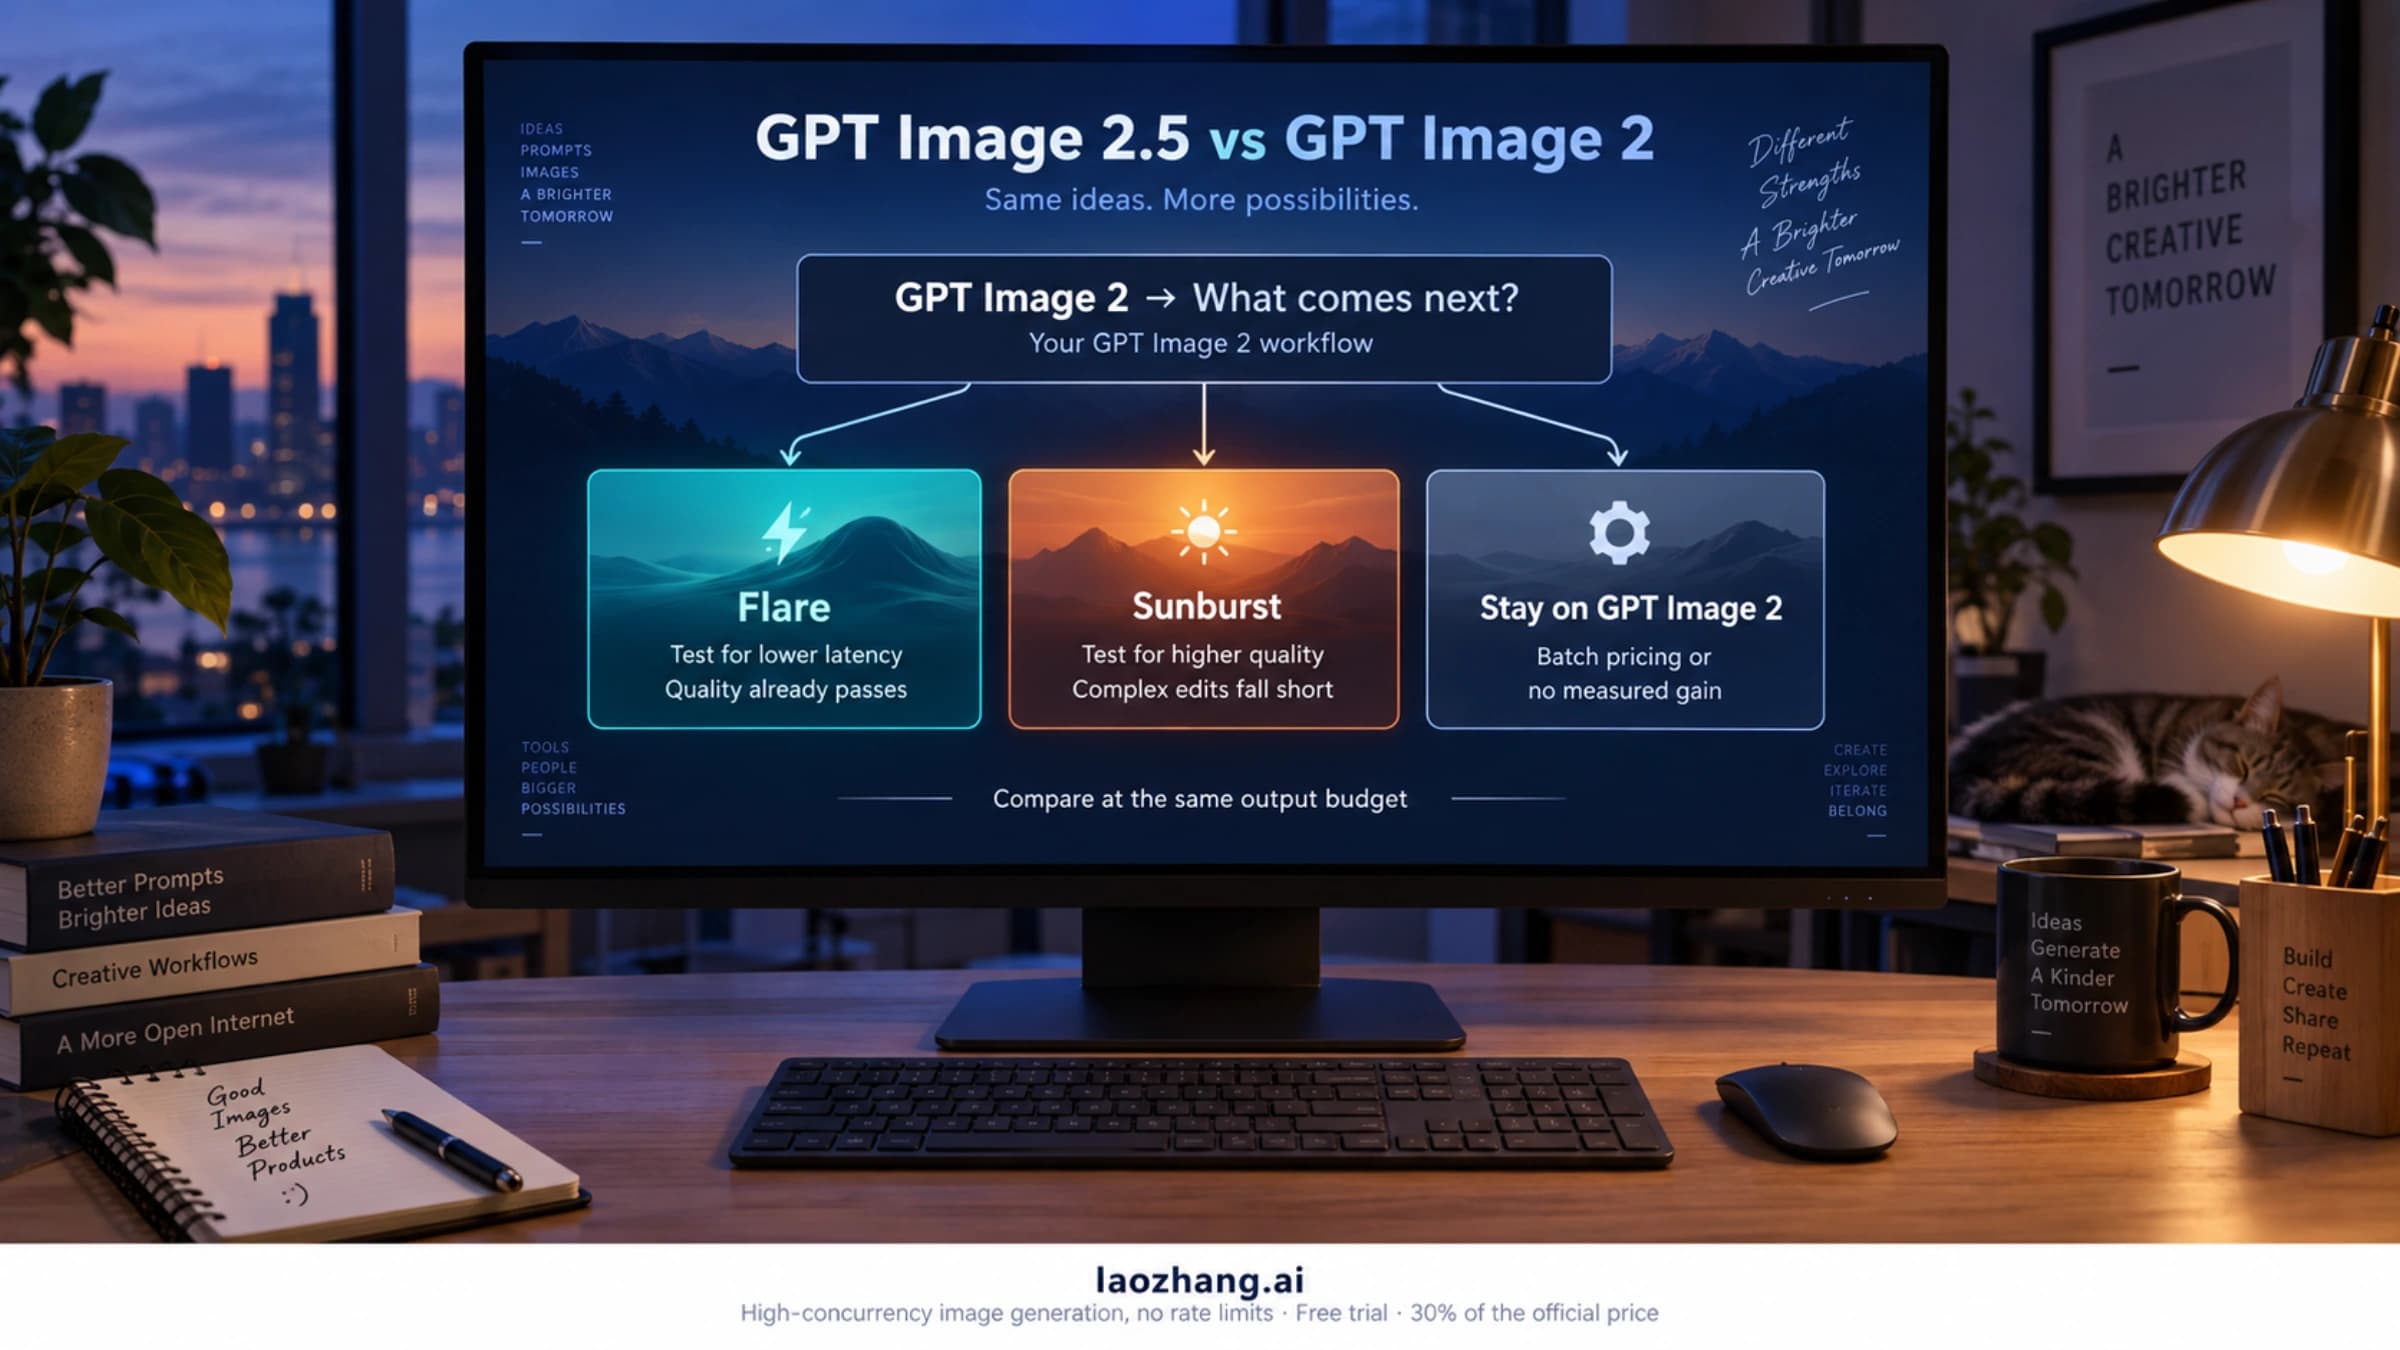
Test Flare first if GPT Image 2 already passes, Sunburst if not, and keep GPT Image 2 for Batch. Token rates match; the same quality label buys less on 2.5.
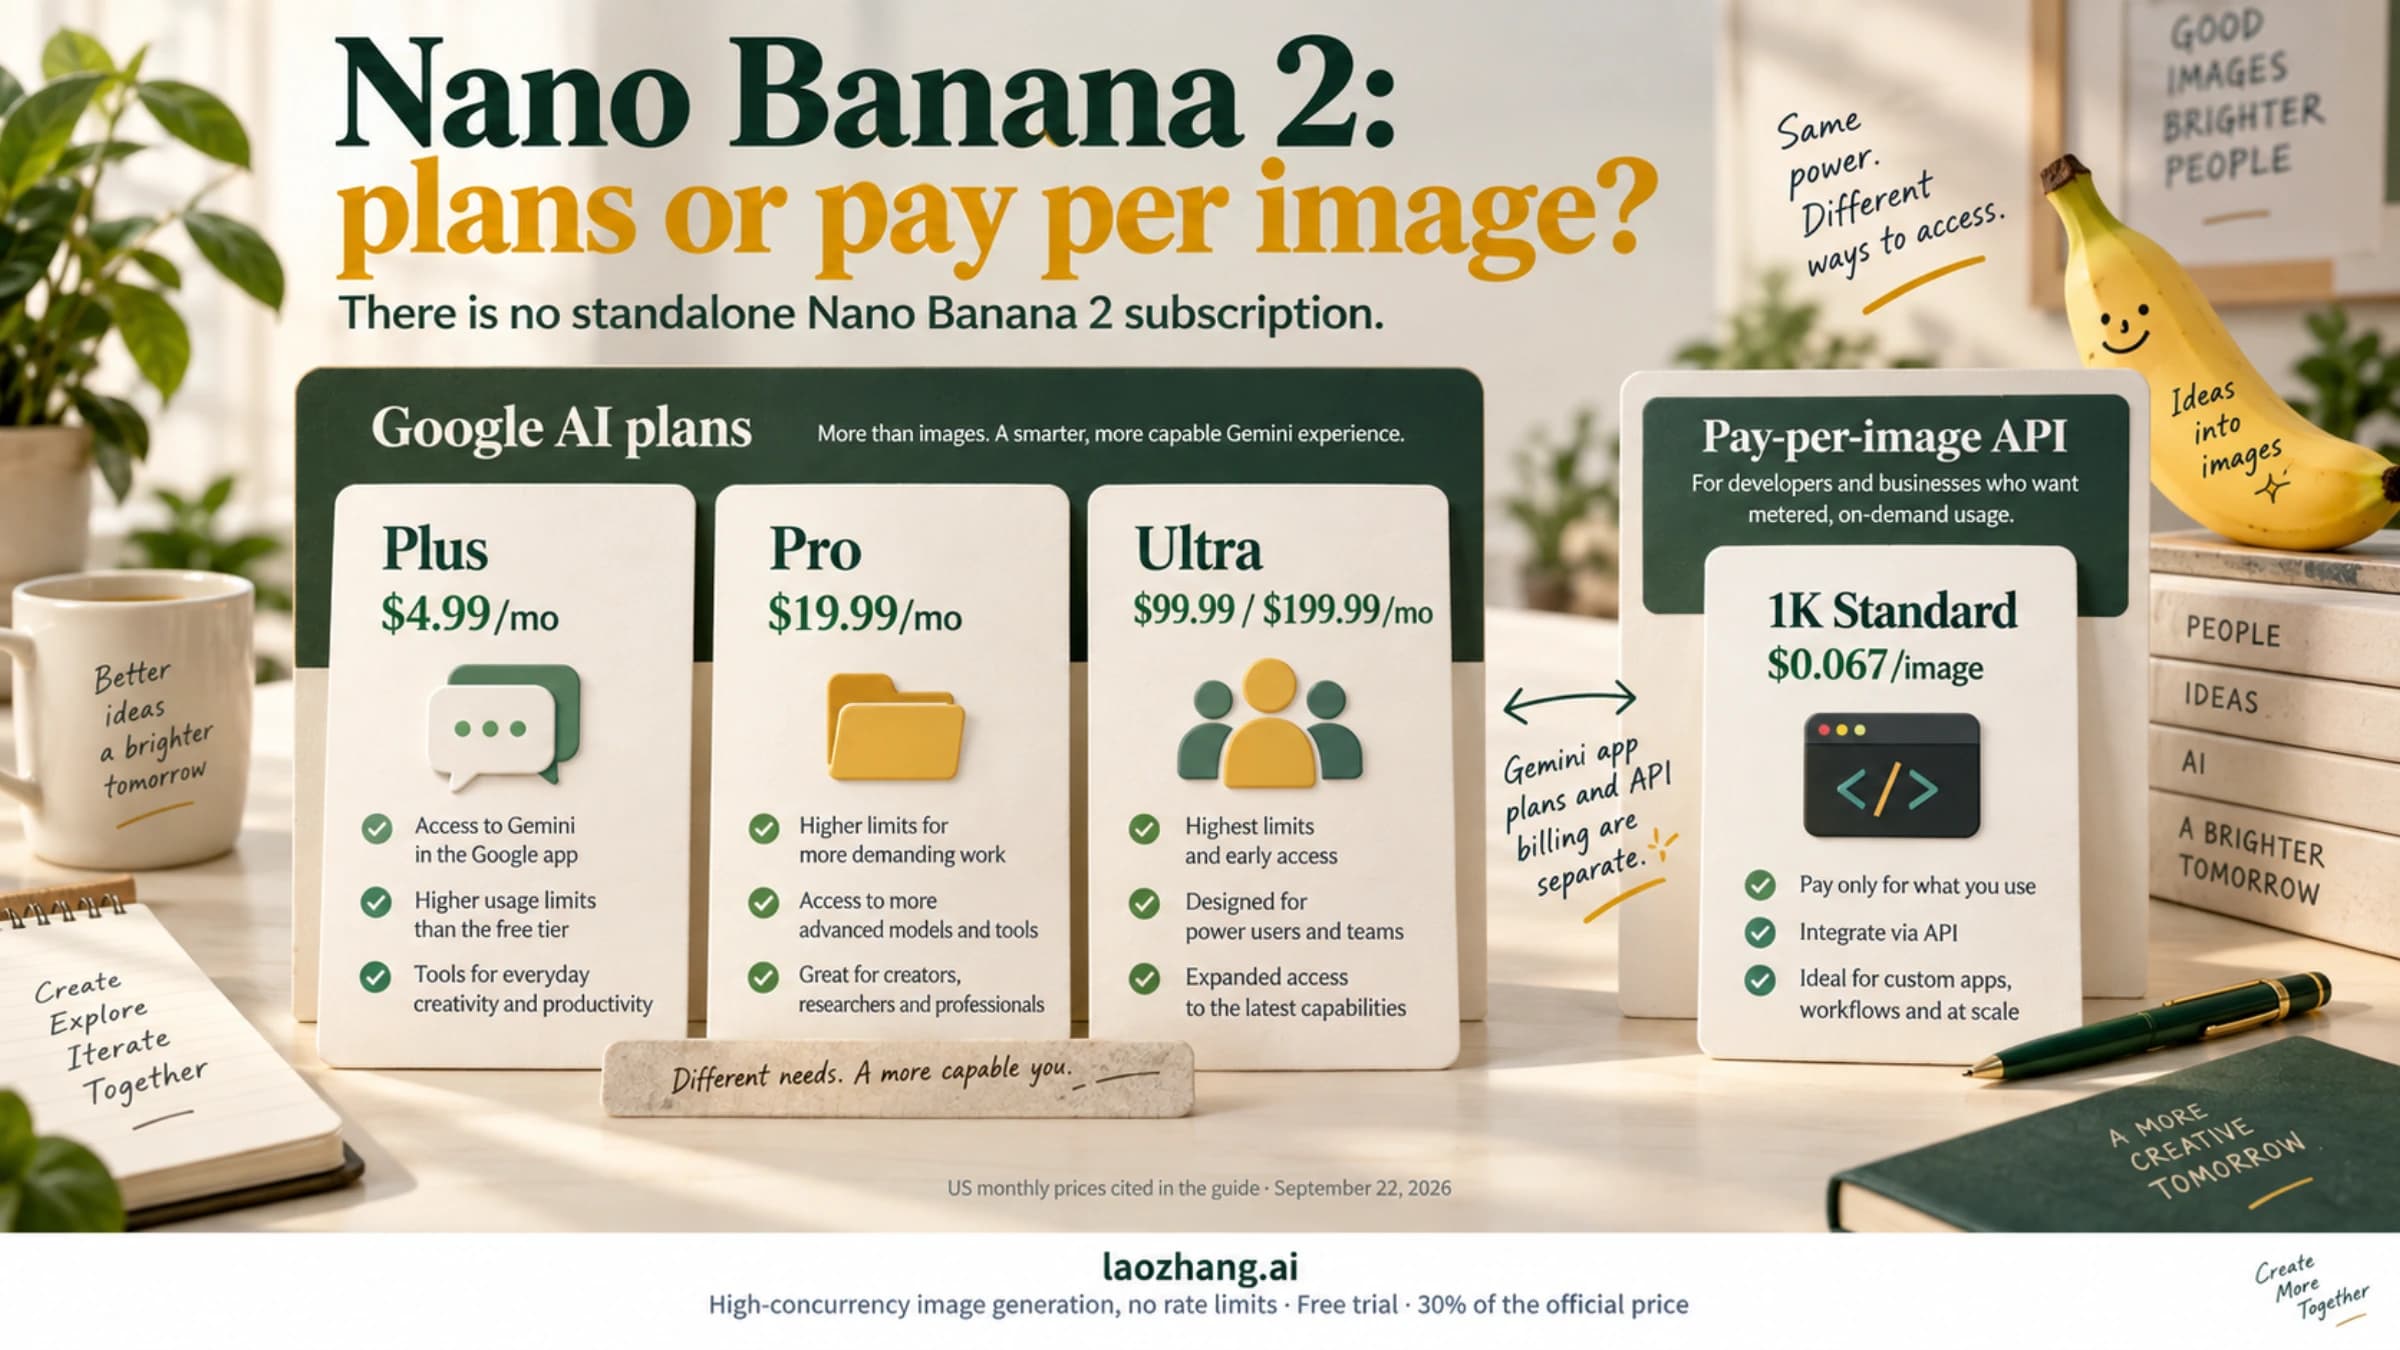
No Nano Banana 2 subscription exists. As of September 2026, US users pay through Google AI Plus, Pro or Ultra; past about 300 images a month the API costs less.
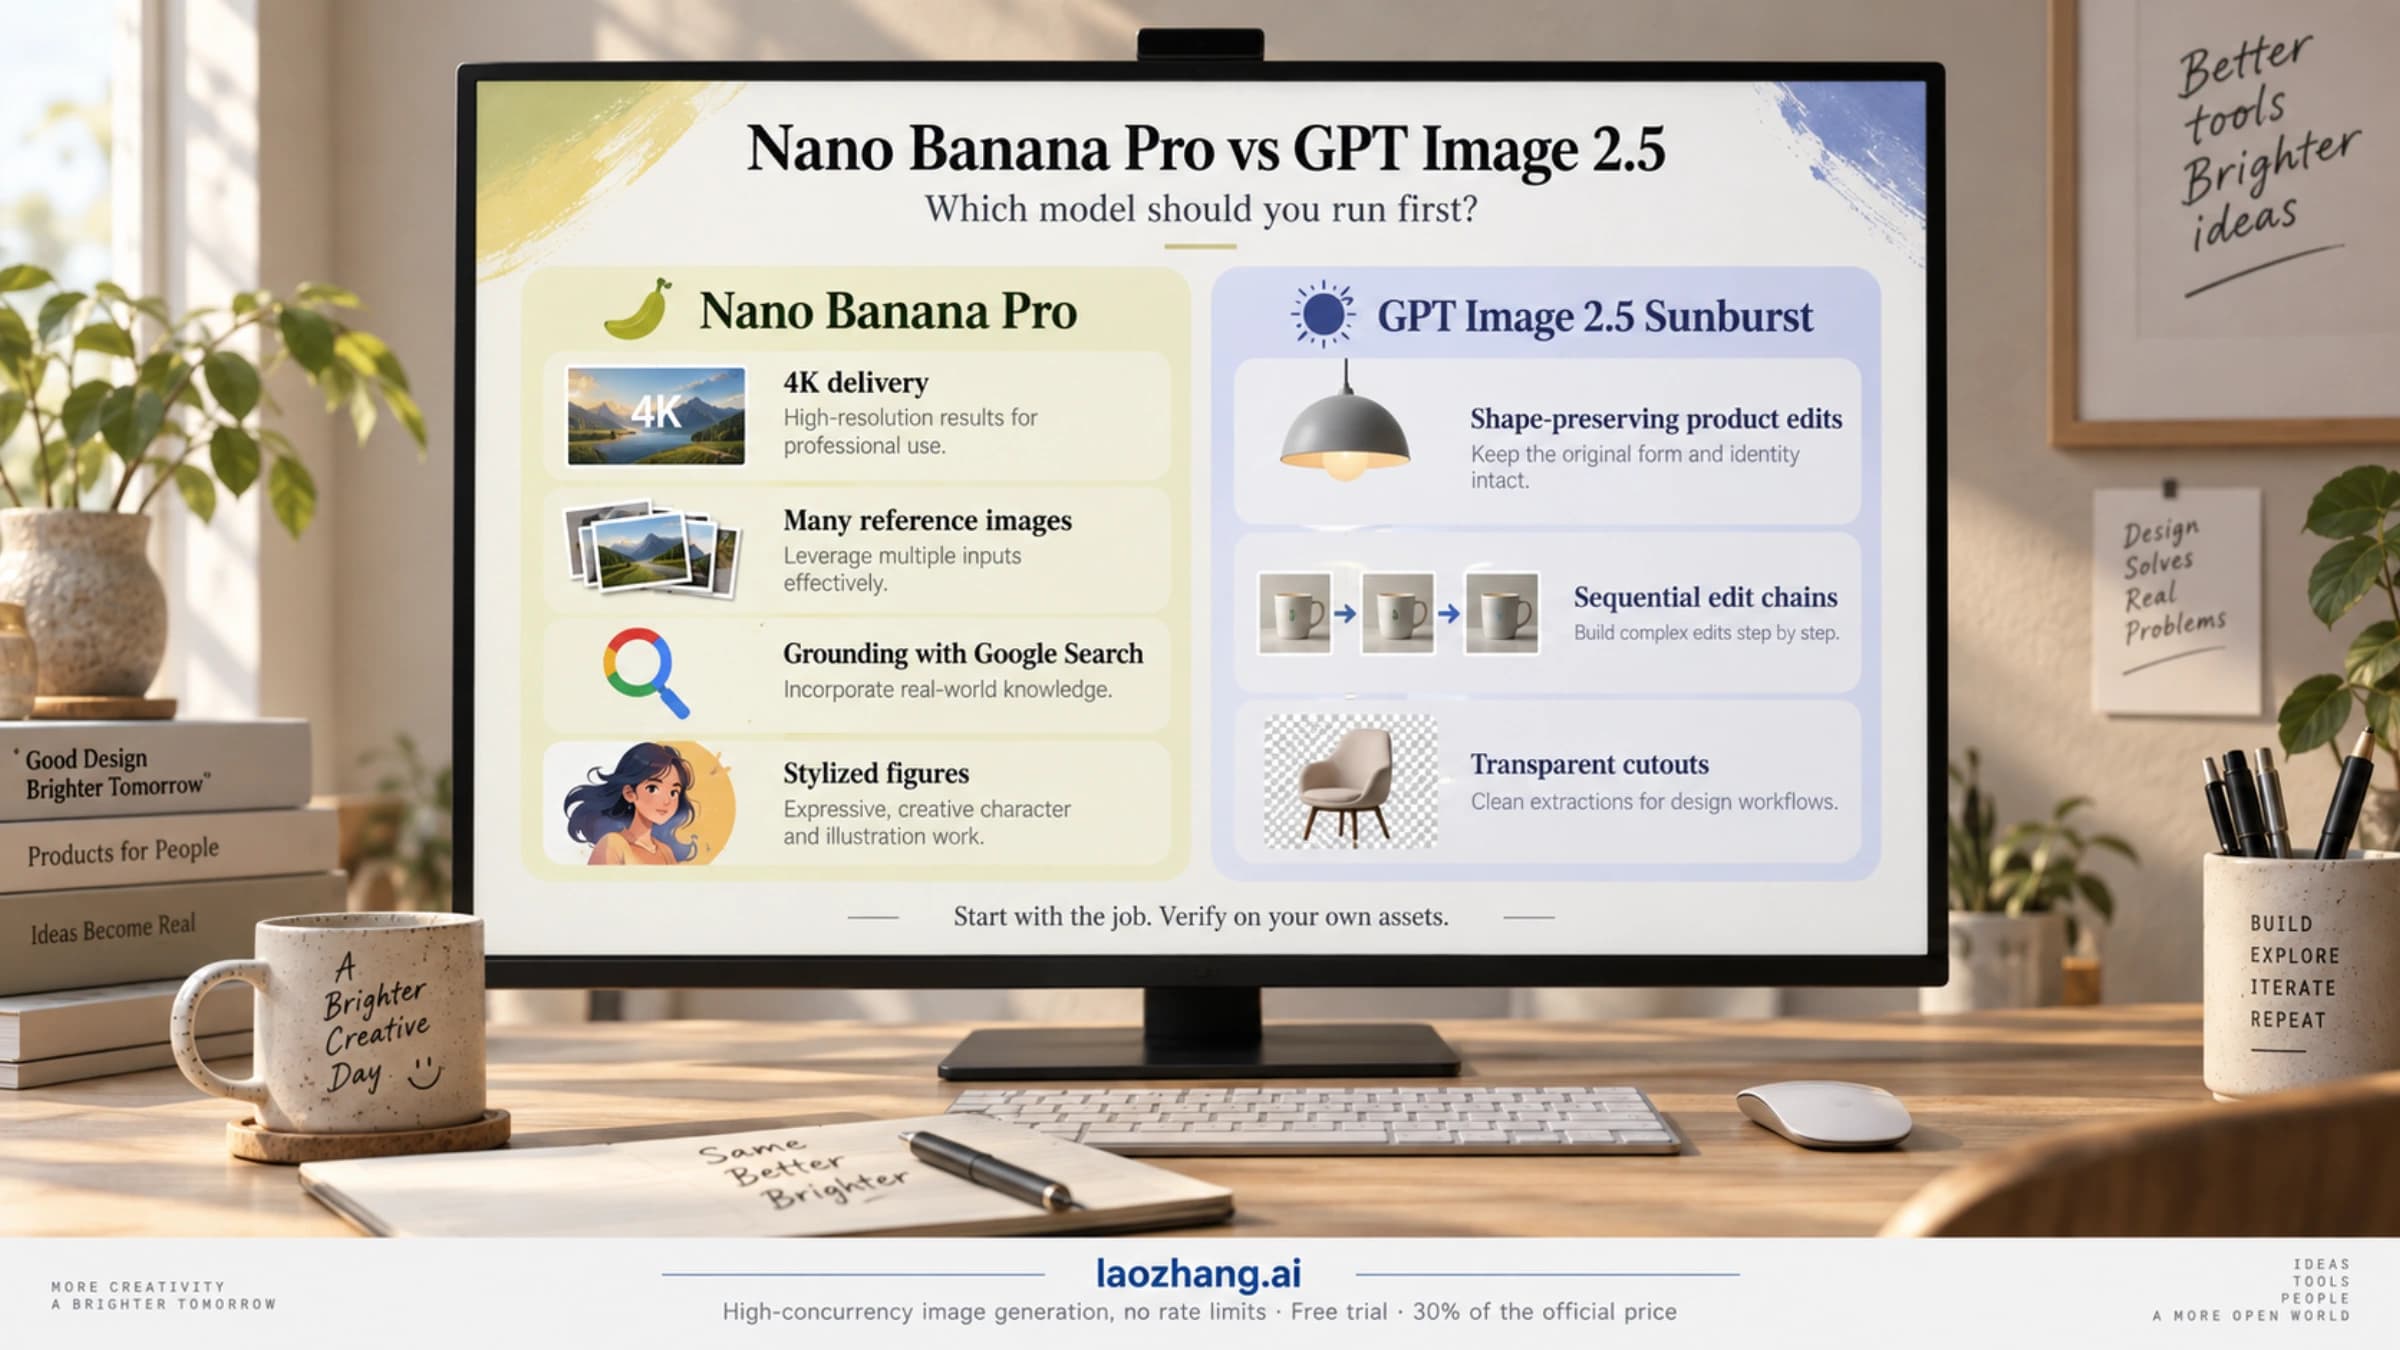
No universal winner as of September 2026: run GPT Image 2.5 Sunburst first for shape-preserving edits, Nano Banana Pro for 4K, many references or stylization.
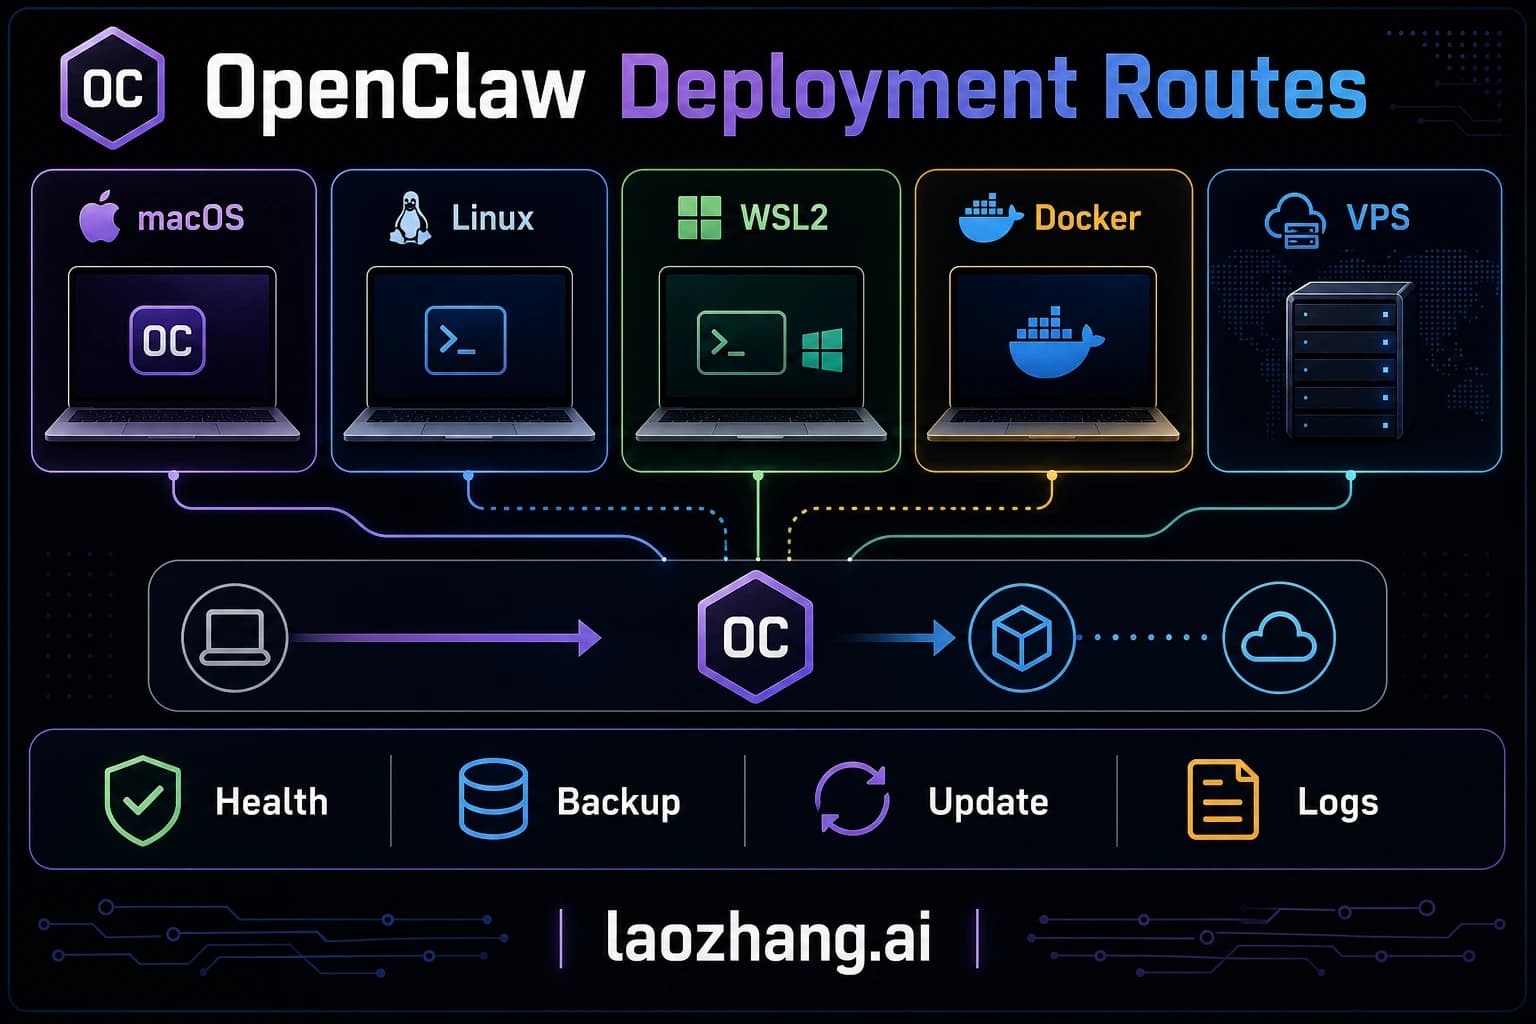
Install OpenClaw with the official installer, complete provider and Gateway setup, and verify a first reply. Follow separate macOS/Linux, native Windows, WSL2, and Docker steps, with current Node requirements and fixes for common installation errors.
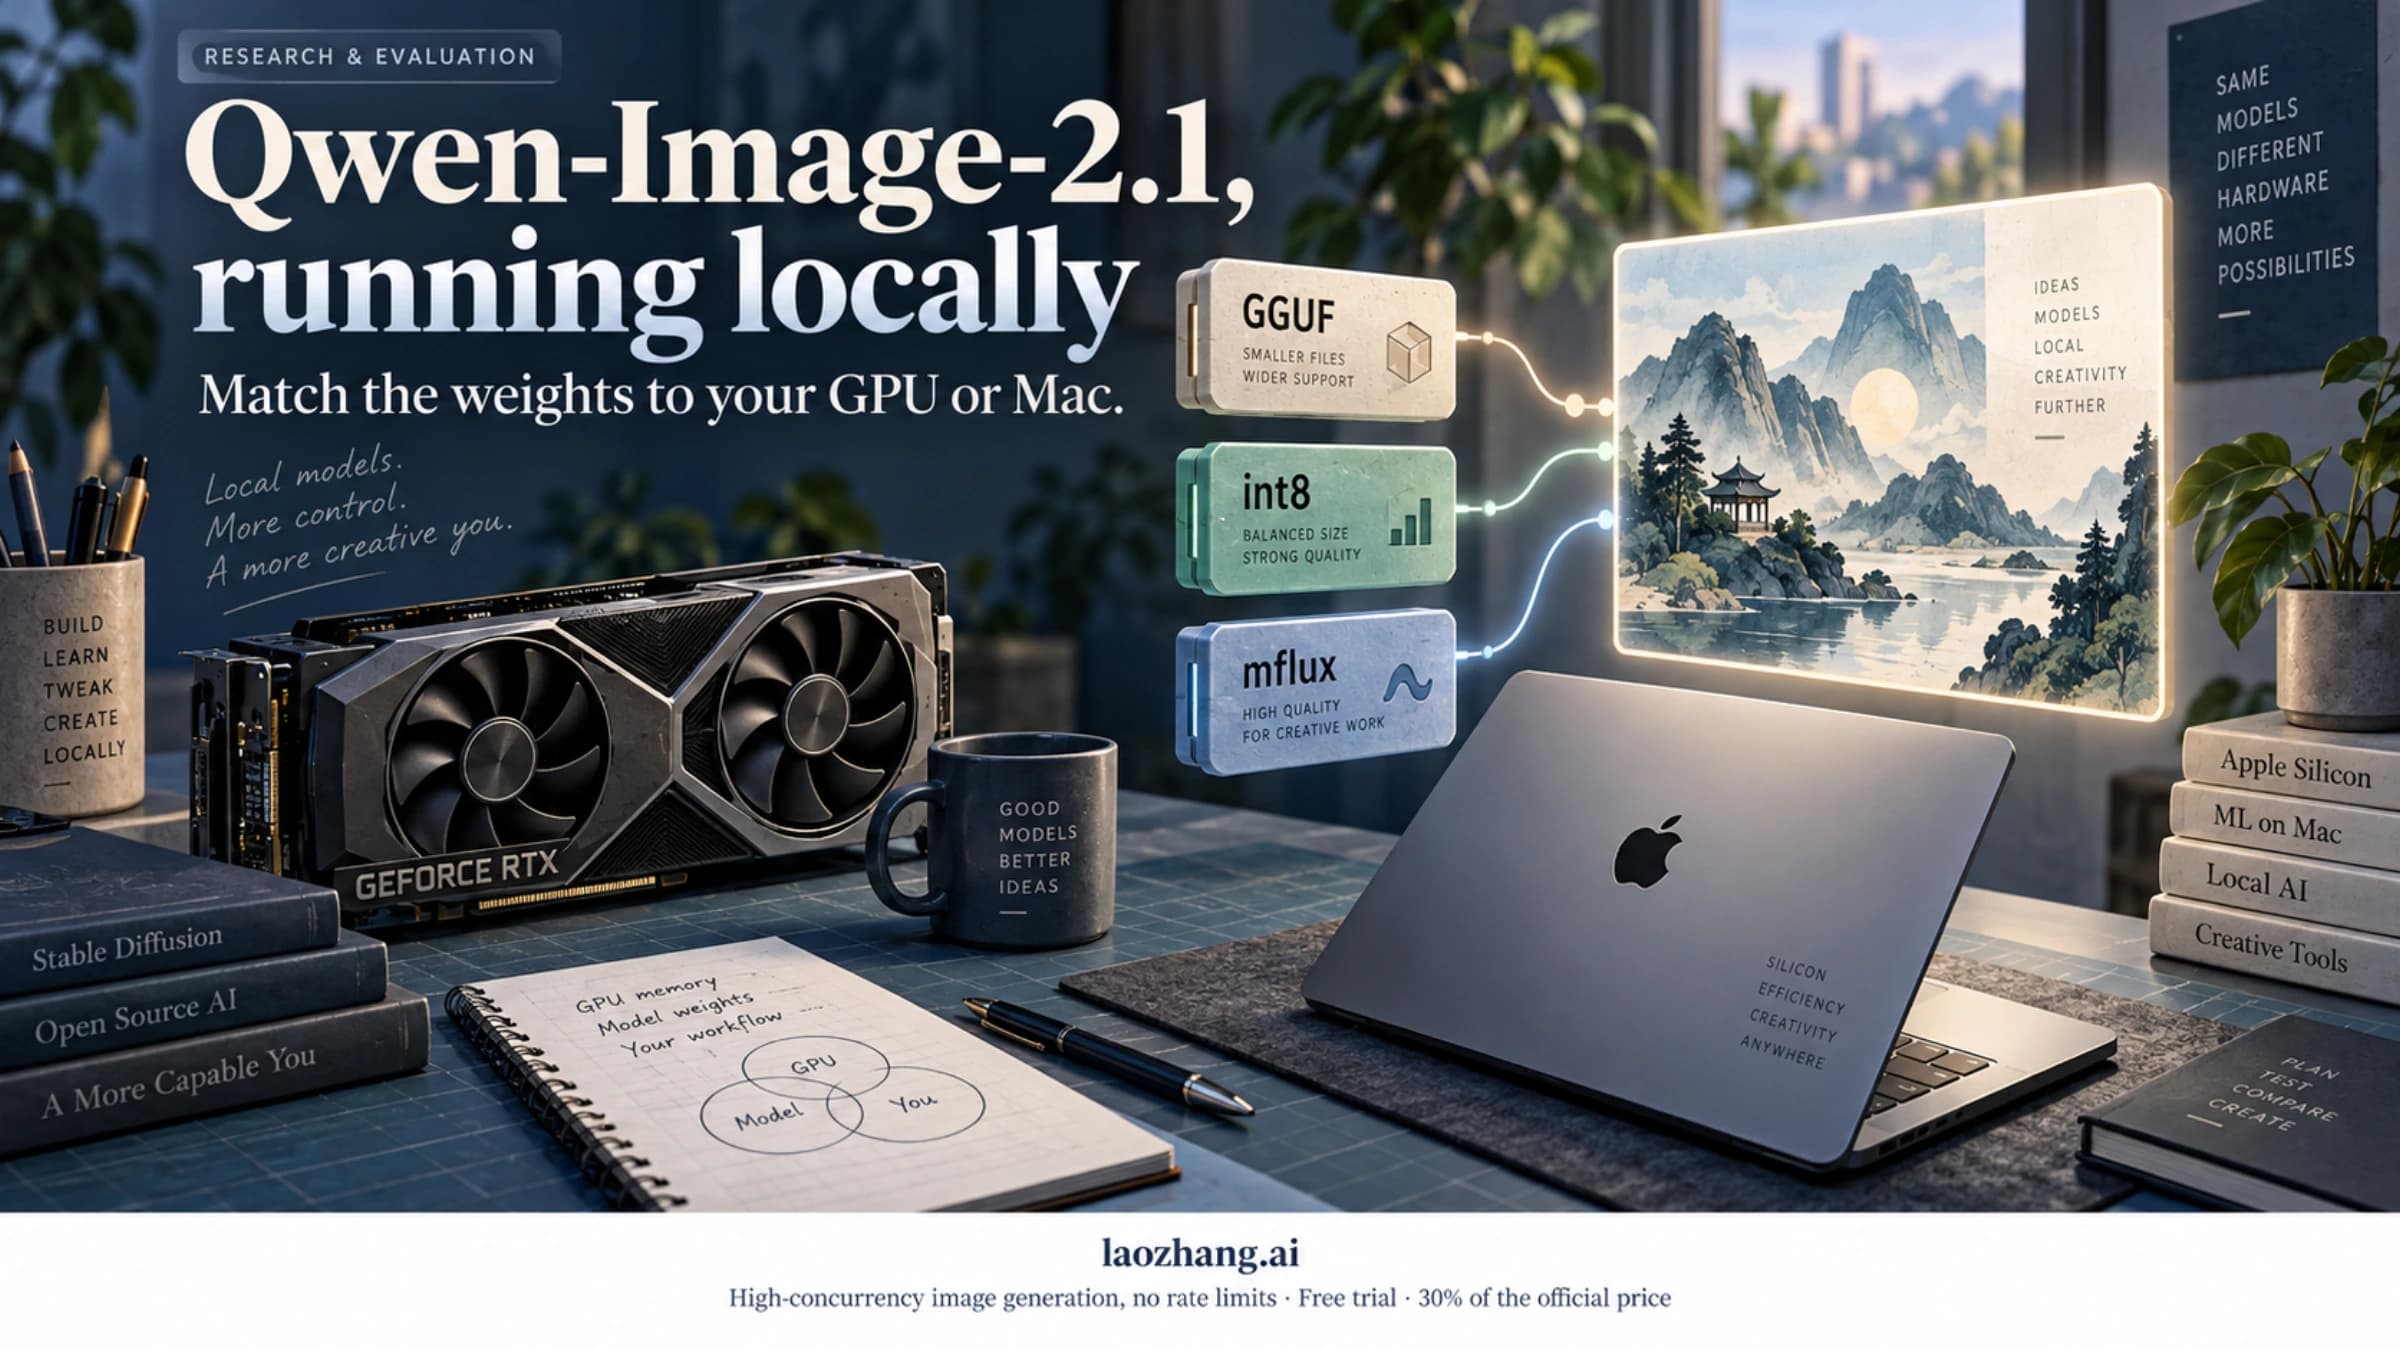
Qwen-Image-2.1 runs on 16–24 GB NVIDIA cards with official int8 files, on 8–12 GB with GGUF and the W4A8 encoder, and on Macs via mflux, for research use only.
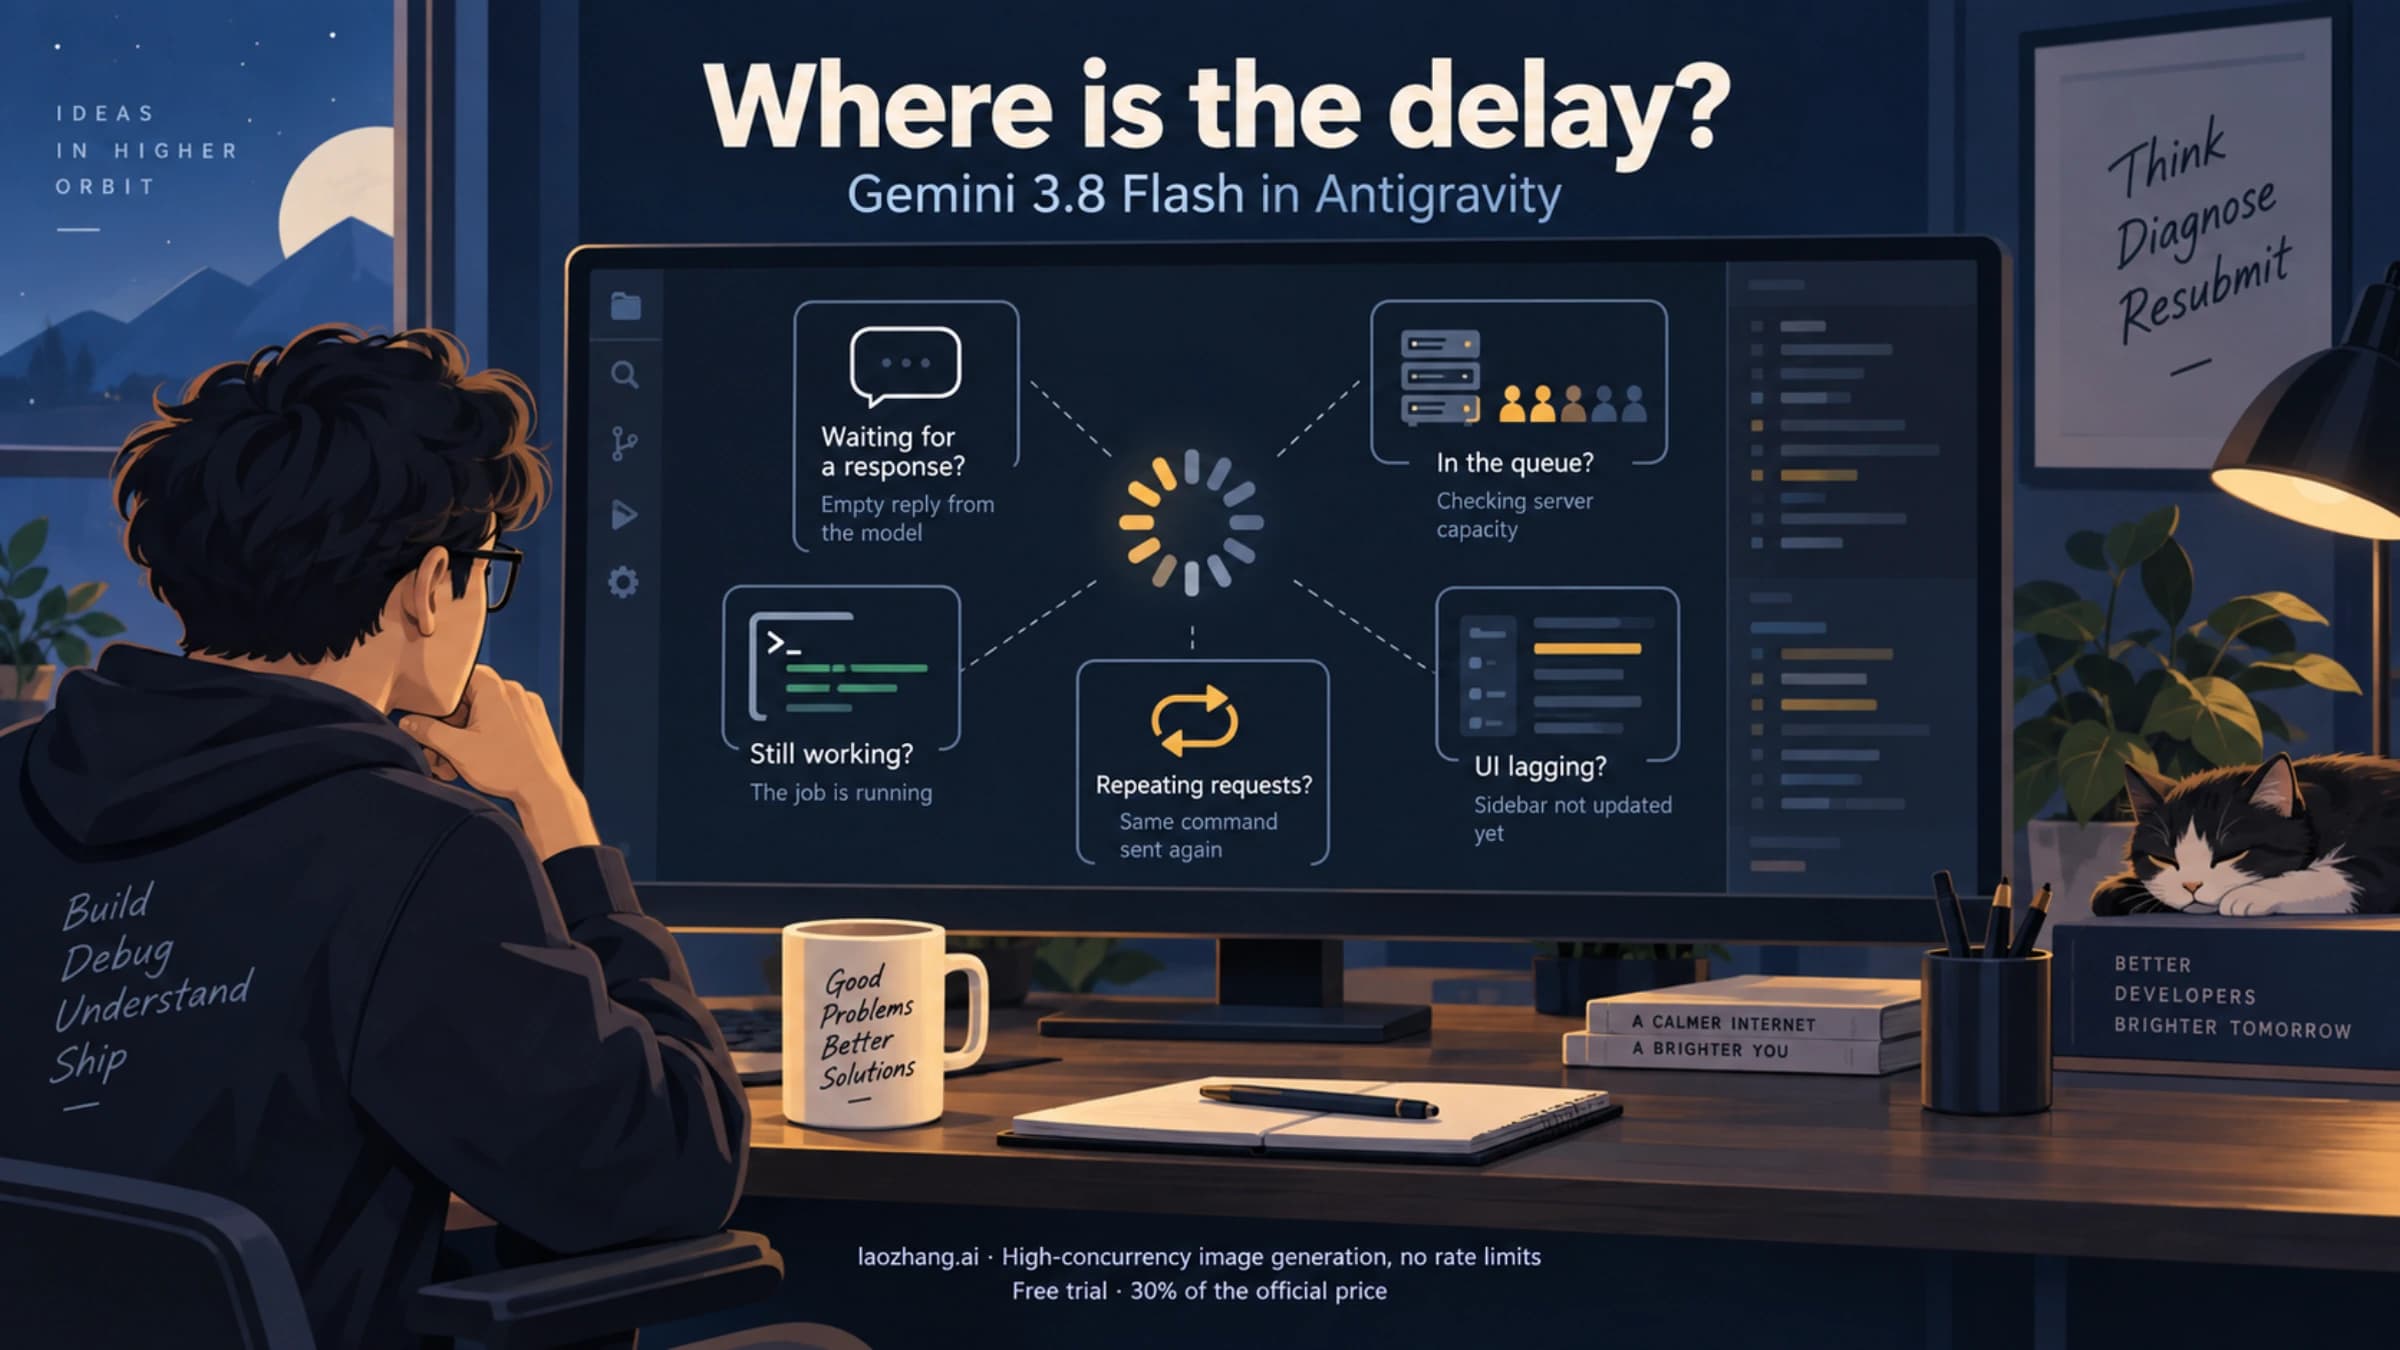
If Gemini 3.8 Flash feels slow in Antigravity, first identify what is waiting: the first answer, an active tool, server capacity, a repeated command, or the app itself. Each calls for a different response.
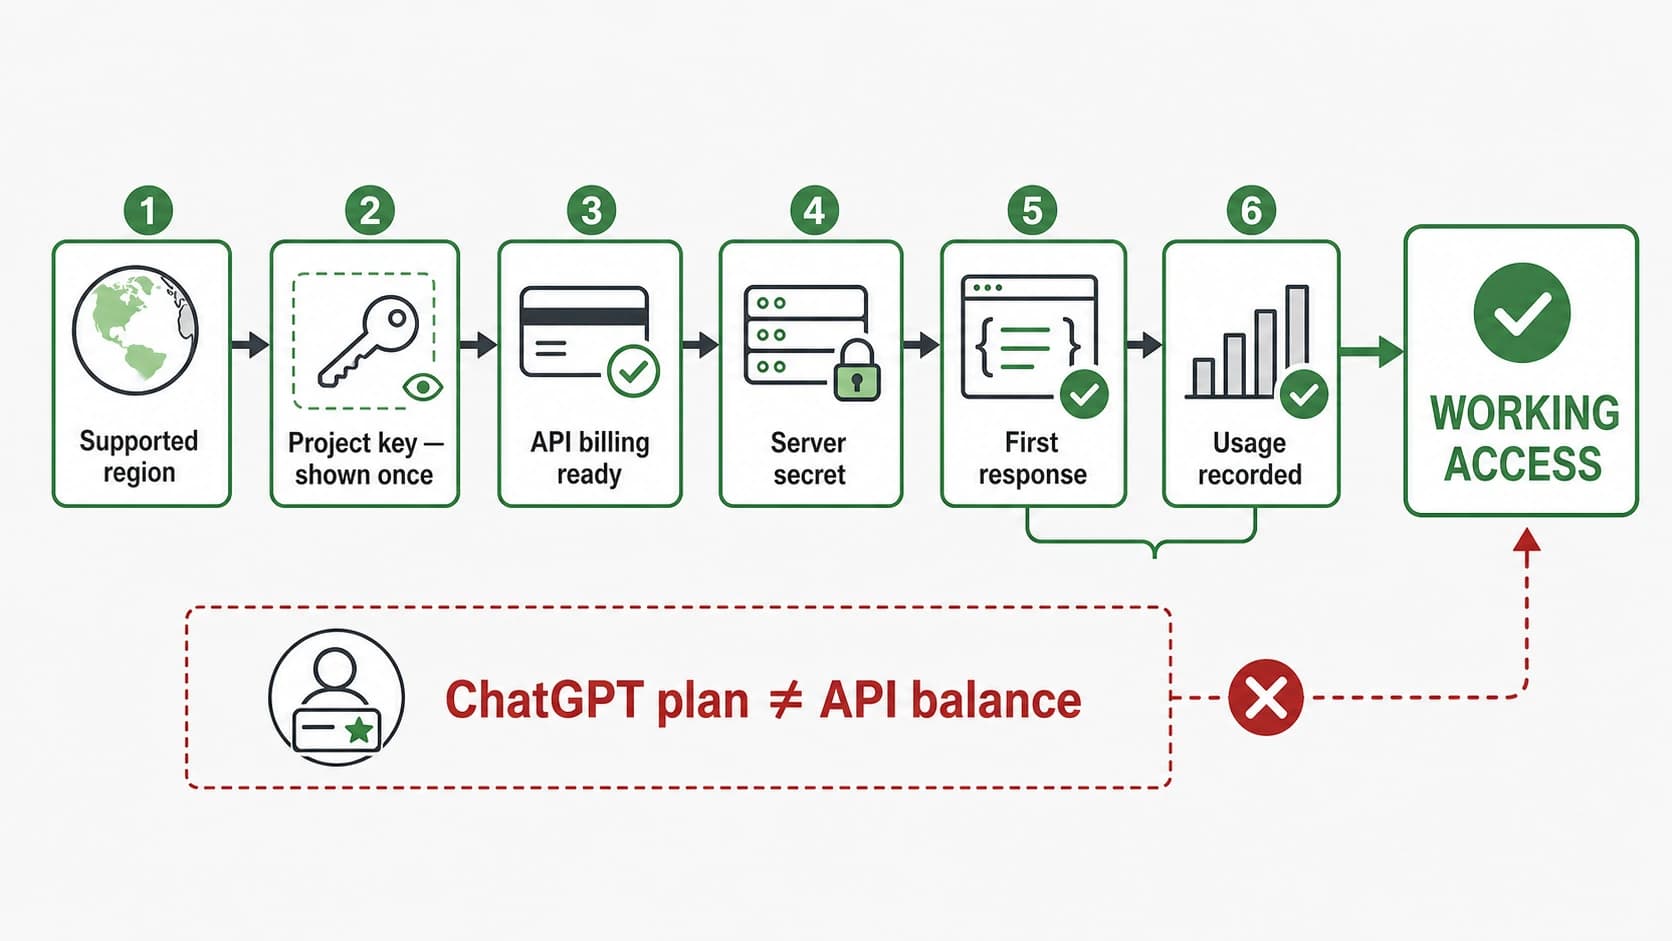
A ChatGPT subscription does not issue or fund an API key. The working route is OpenAI Platform: verify your region, create a project secret, activate API billing, load it on a server, and confirm both a Responses output and a Usage record.
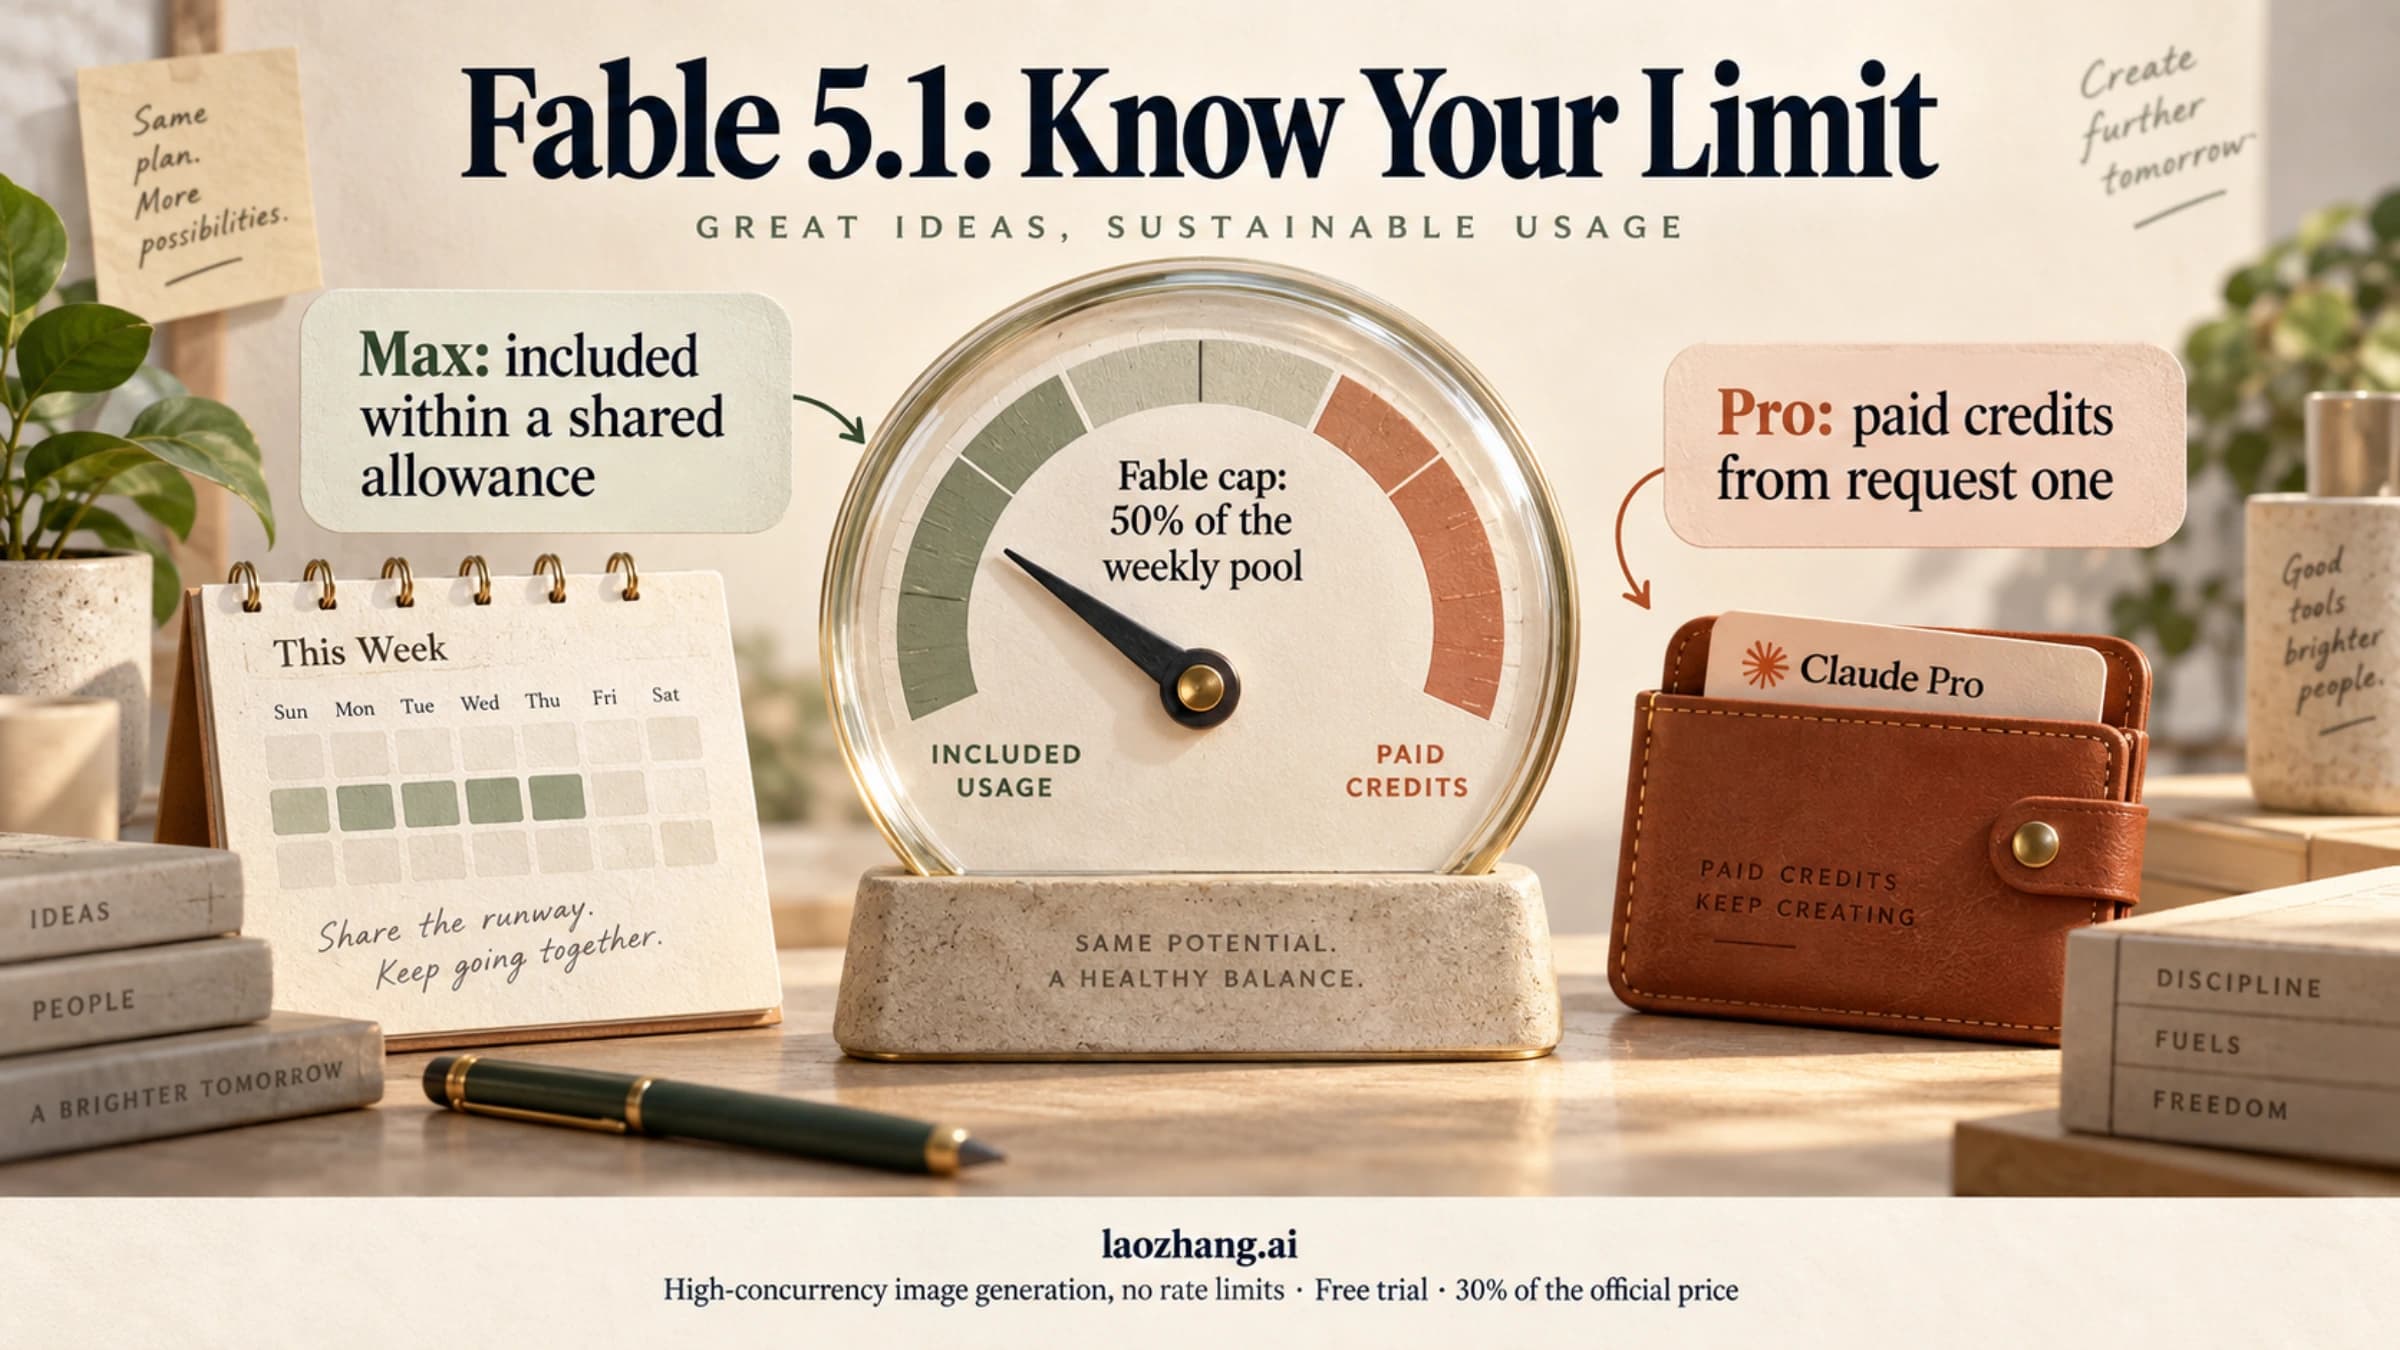
Claude Max includes Fable 5.1 within its existing weekly allowance, with a shared 50% cap for Fable models. Pro pays with usage credits from the first request. Here's how to check your limit, reset time, and spending controls before continuing.
Compare Flare and Nano Banana API costs at 1K and 2K, including official output estimates, LaoZhang per-call prices, and a 10,000-image budget.
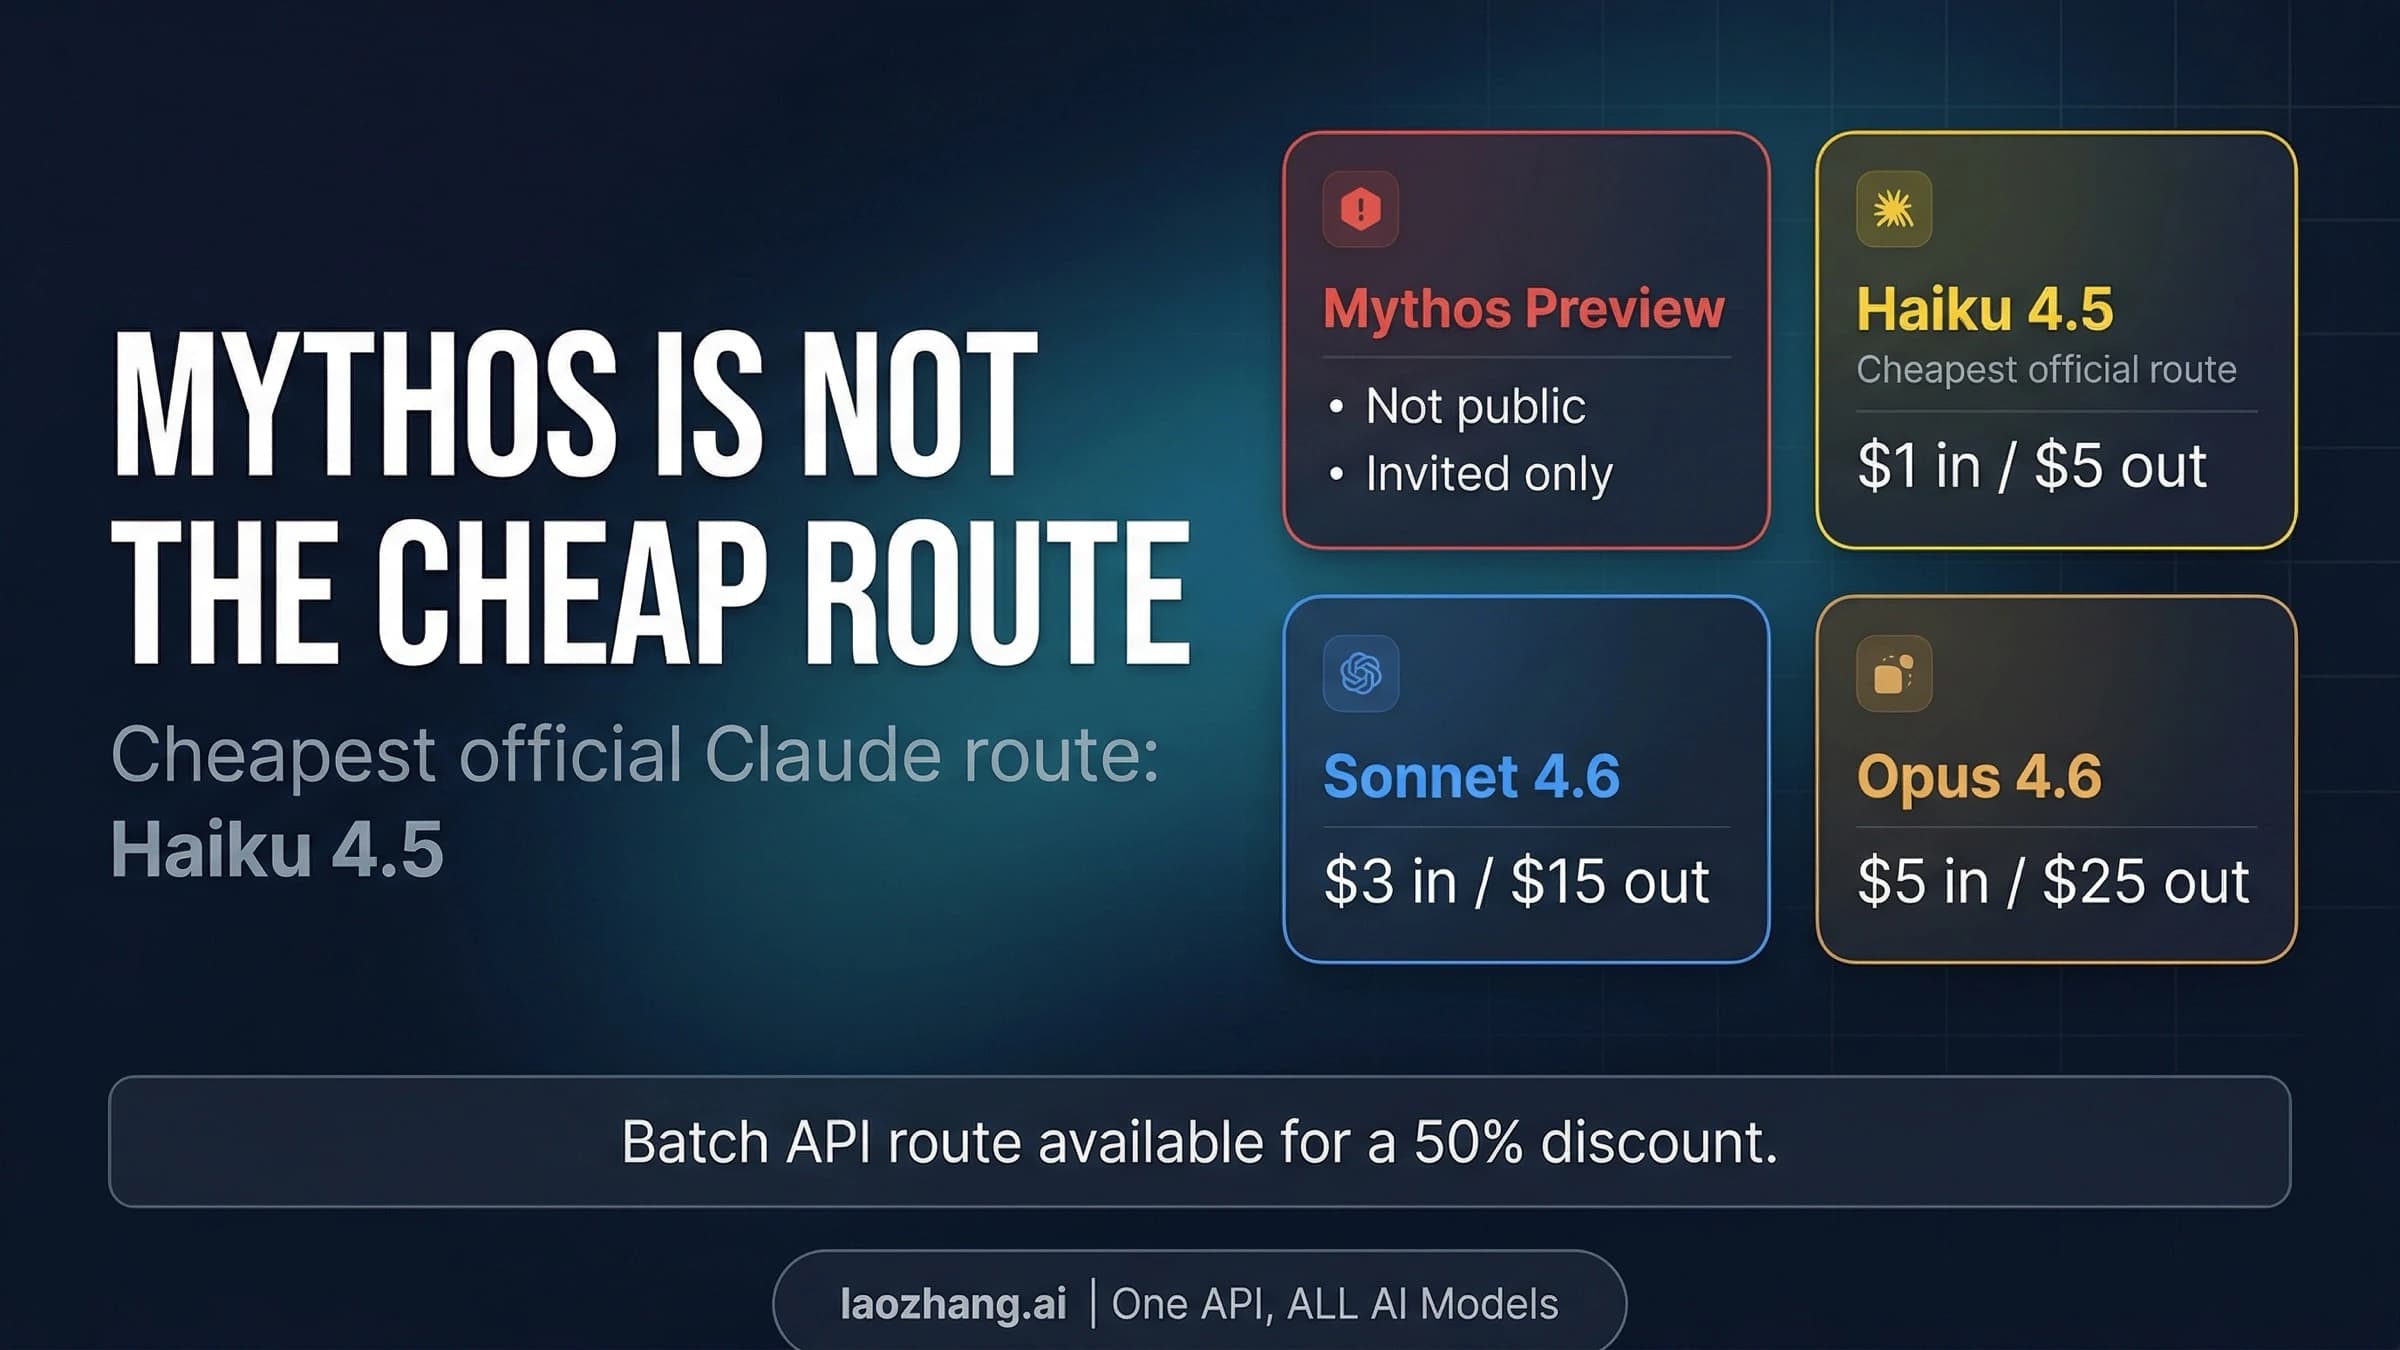
Mythos 5.1 is invitation-only. Its listed rates are $10 per million input tokens, $50 per million output tokens and $0.25 for cache reads. Compare versions and calculate costs.
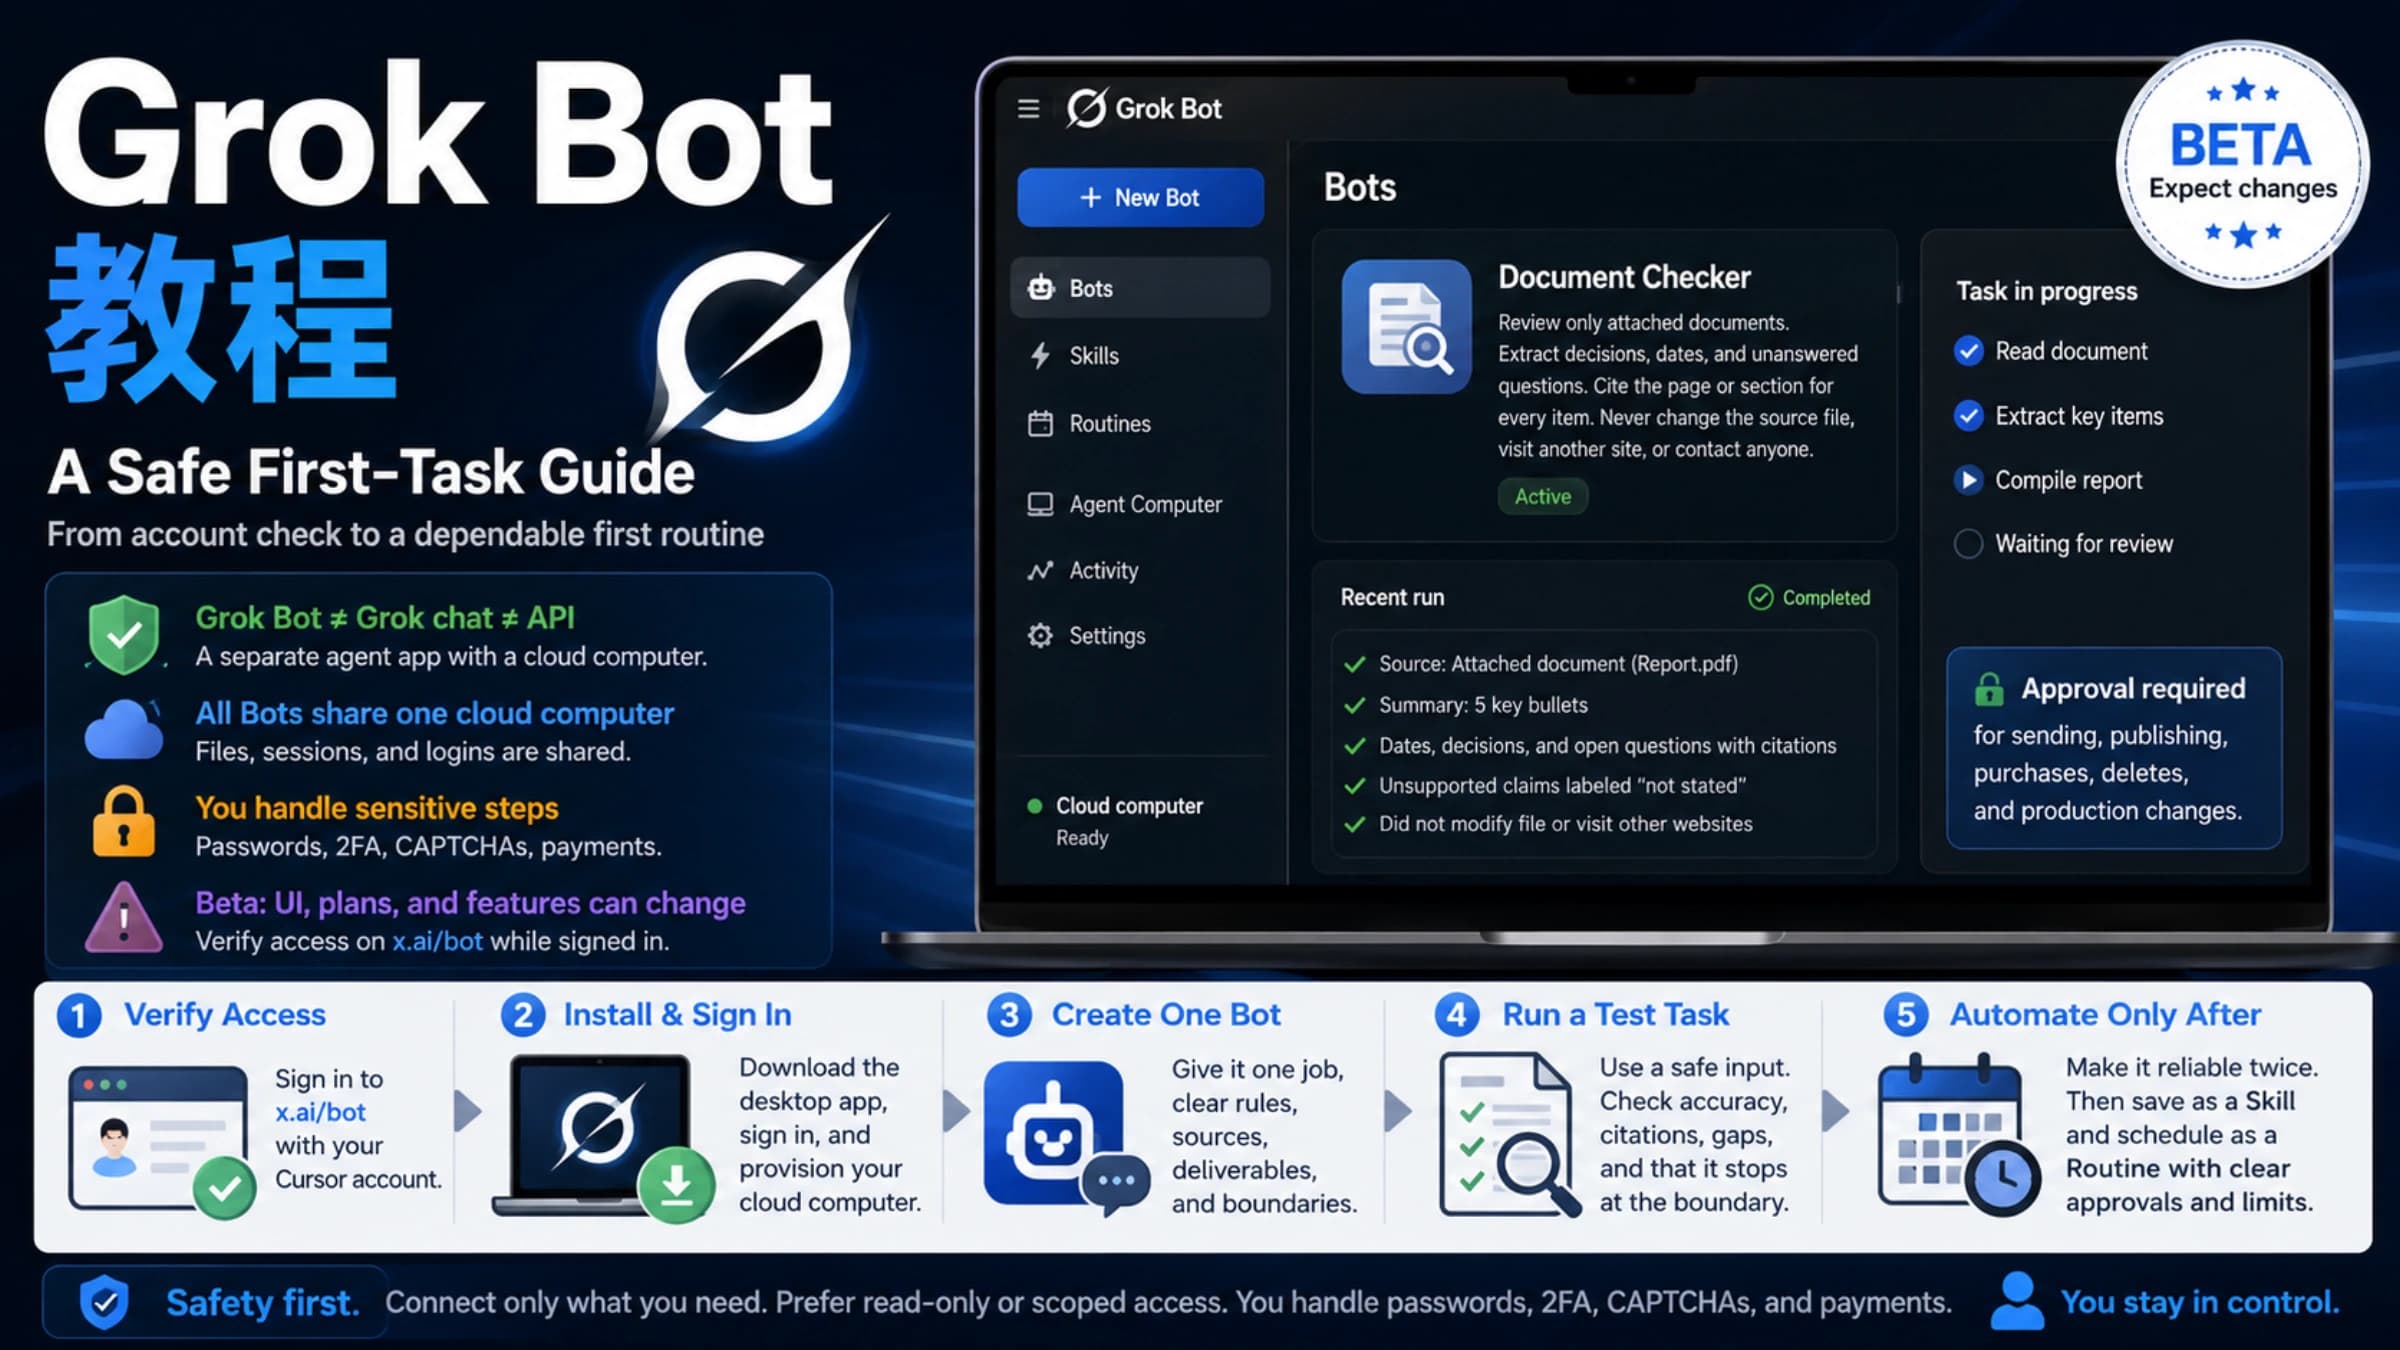
Install Grok Bot on macOS, Windows, or Linux, sign in with the right Cursor account, create your first Bot, and turn an attached document into a report you can check and save.