AI Model & API Guides · Page 18 of 26

Source-linked guidance for AI models, API integration, and developer workflows—turning fast-changing prices, quotas, capabilities, and limits into decisions you can verify.
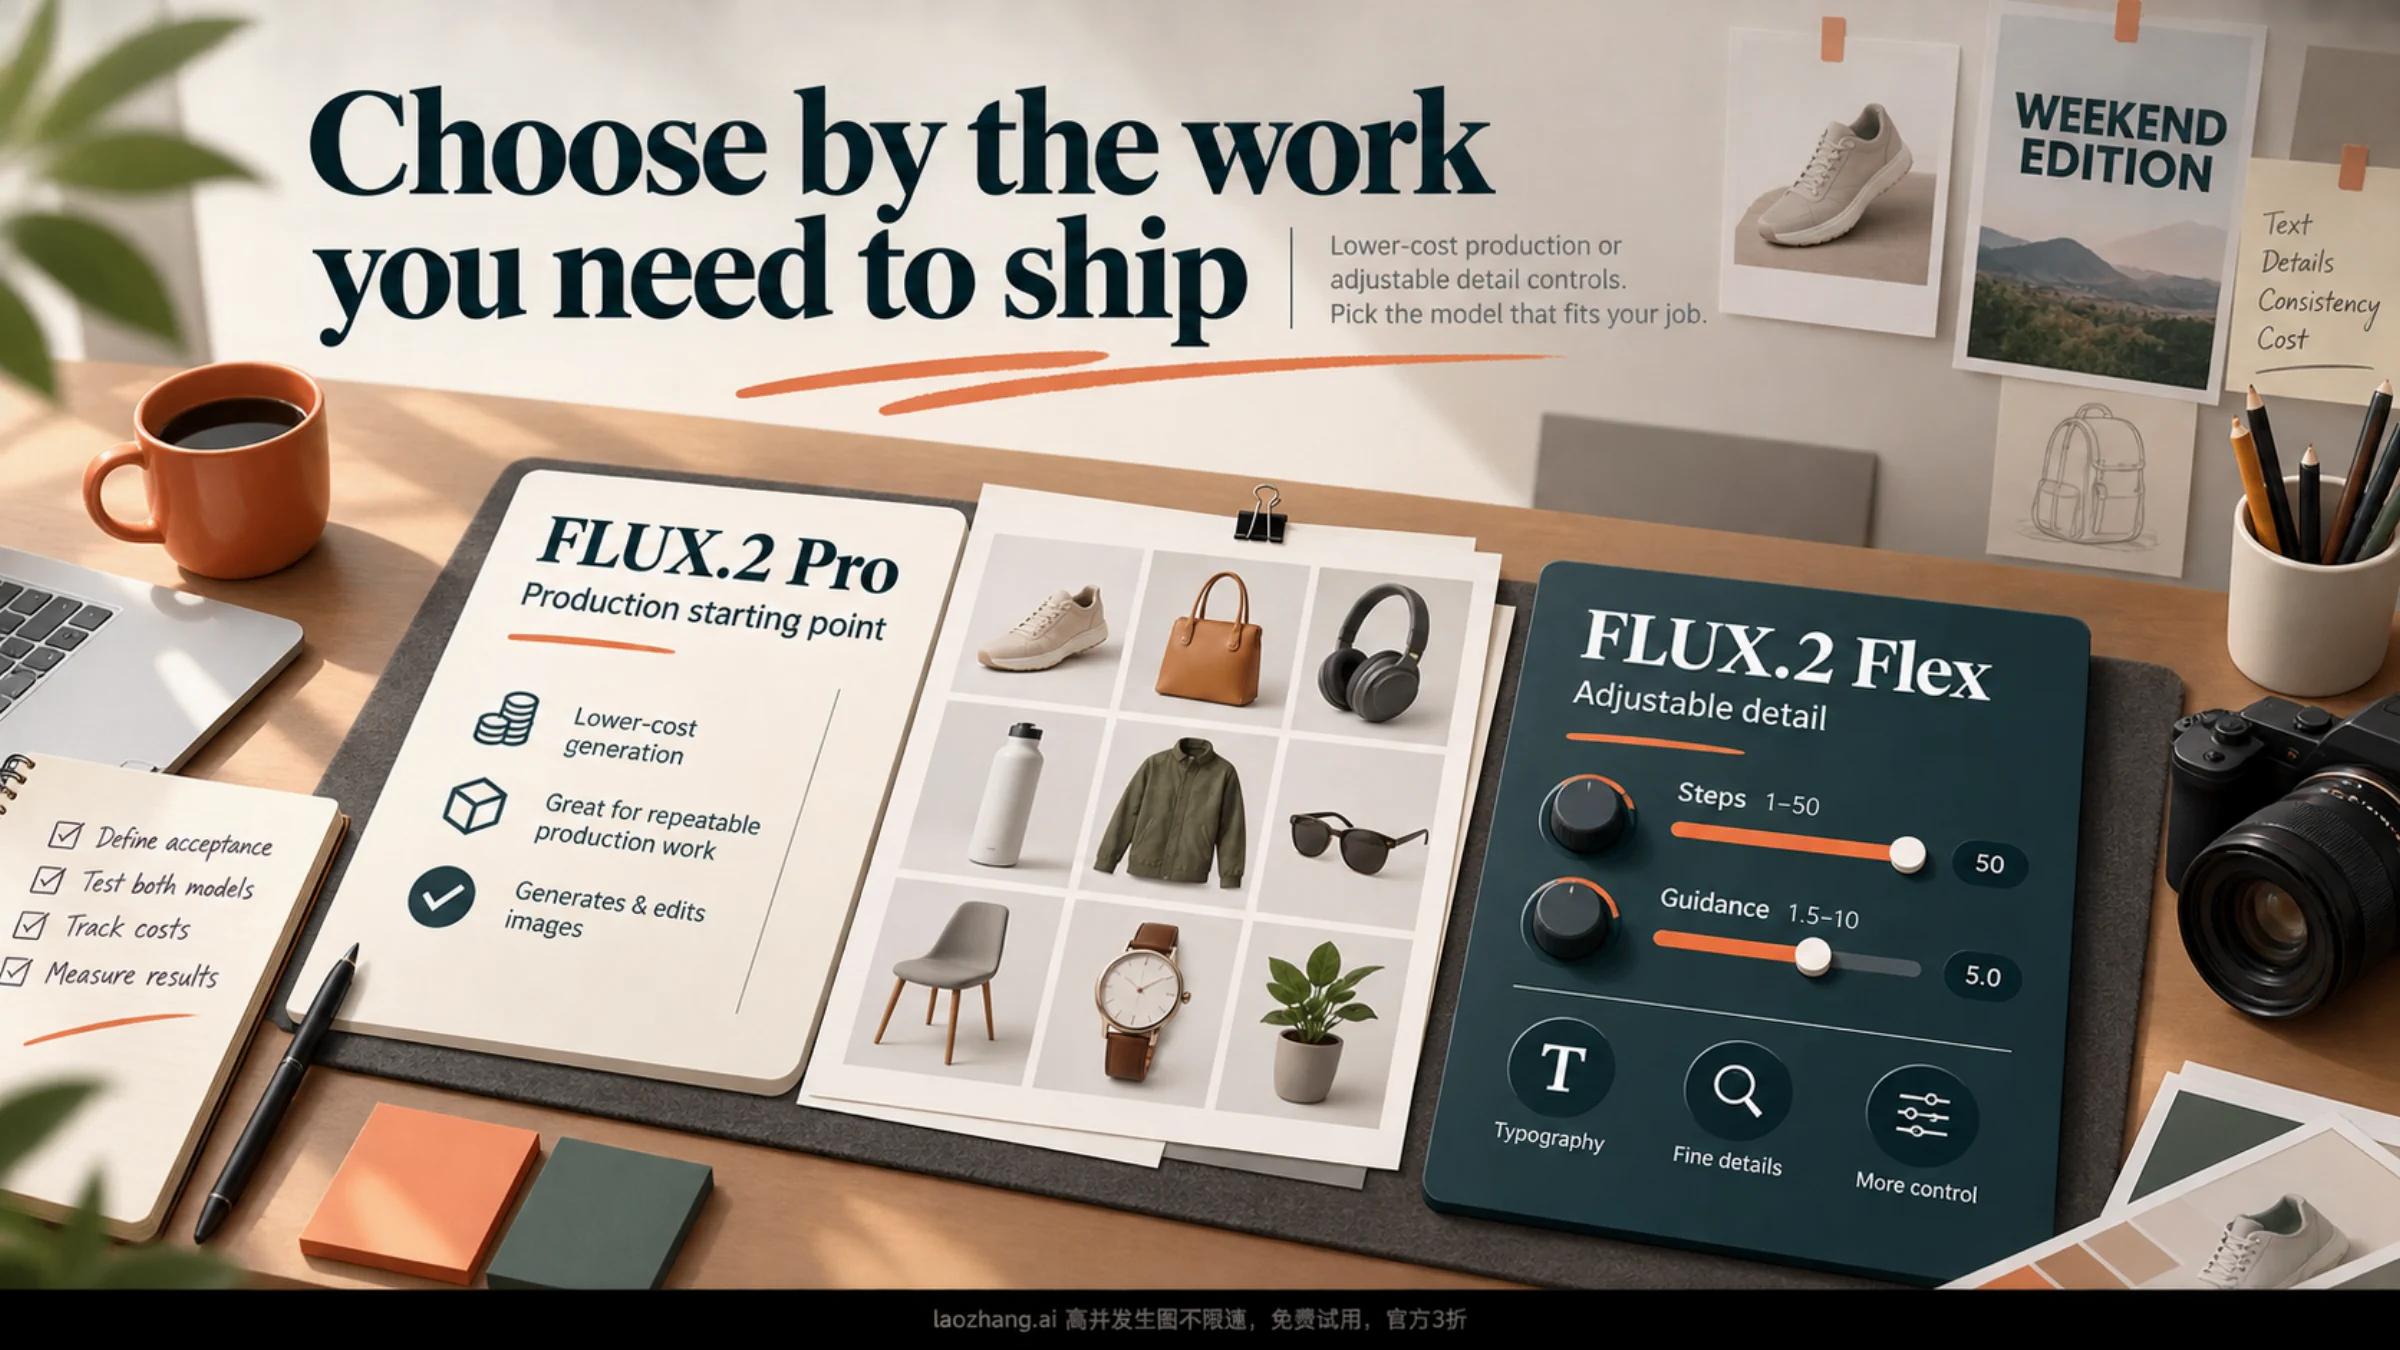
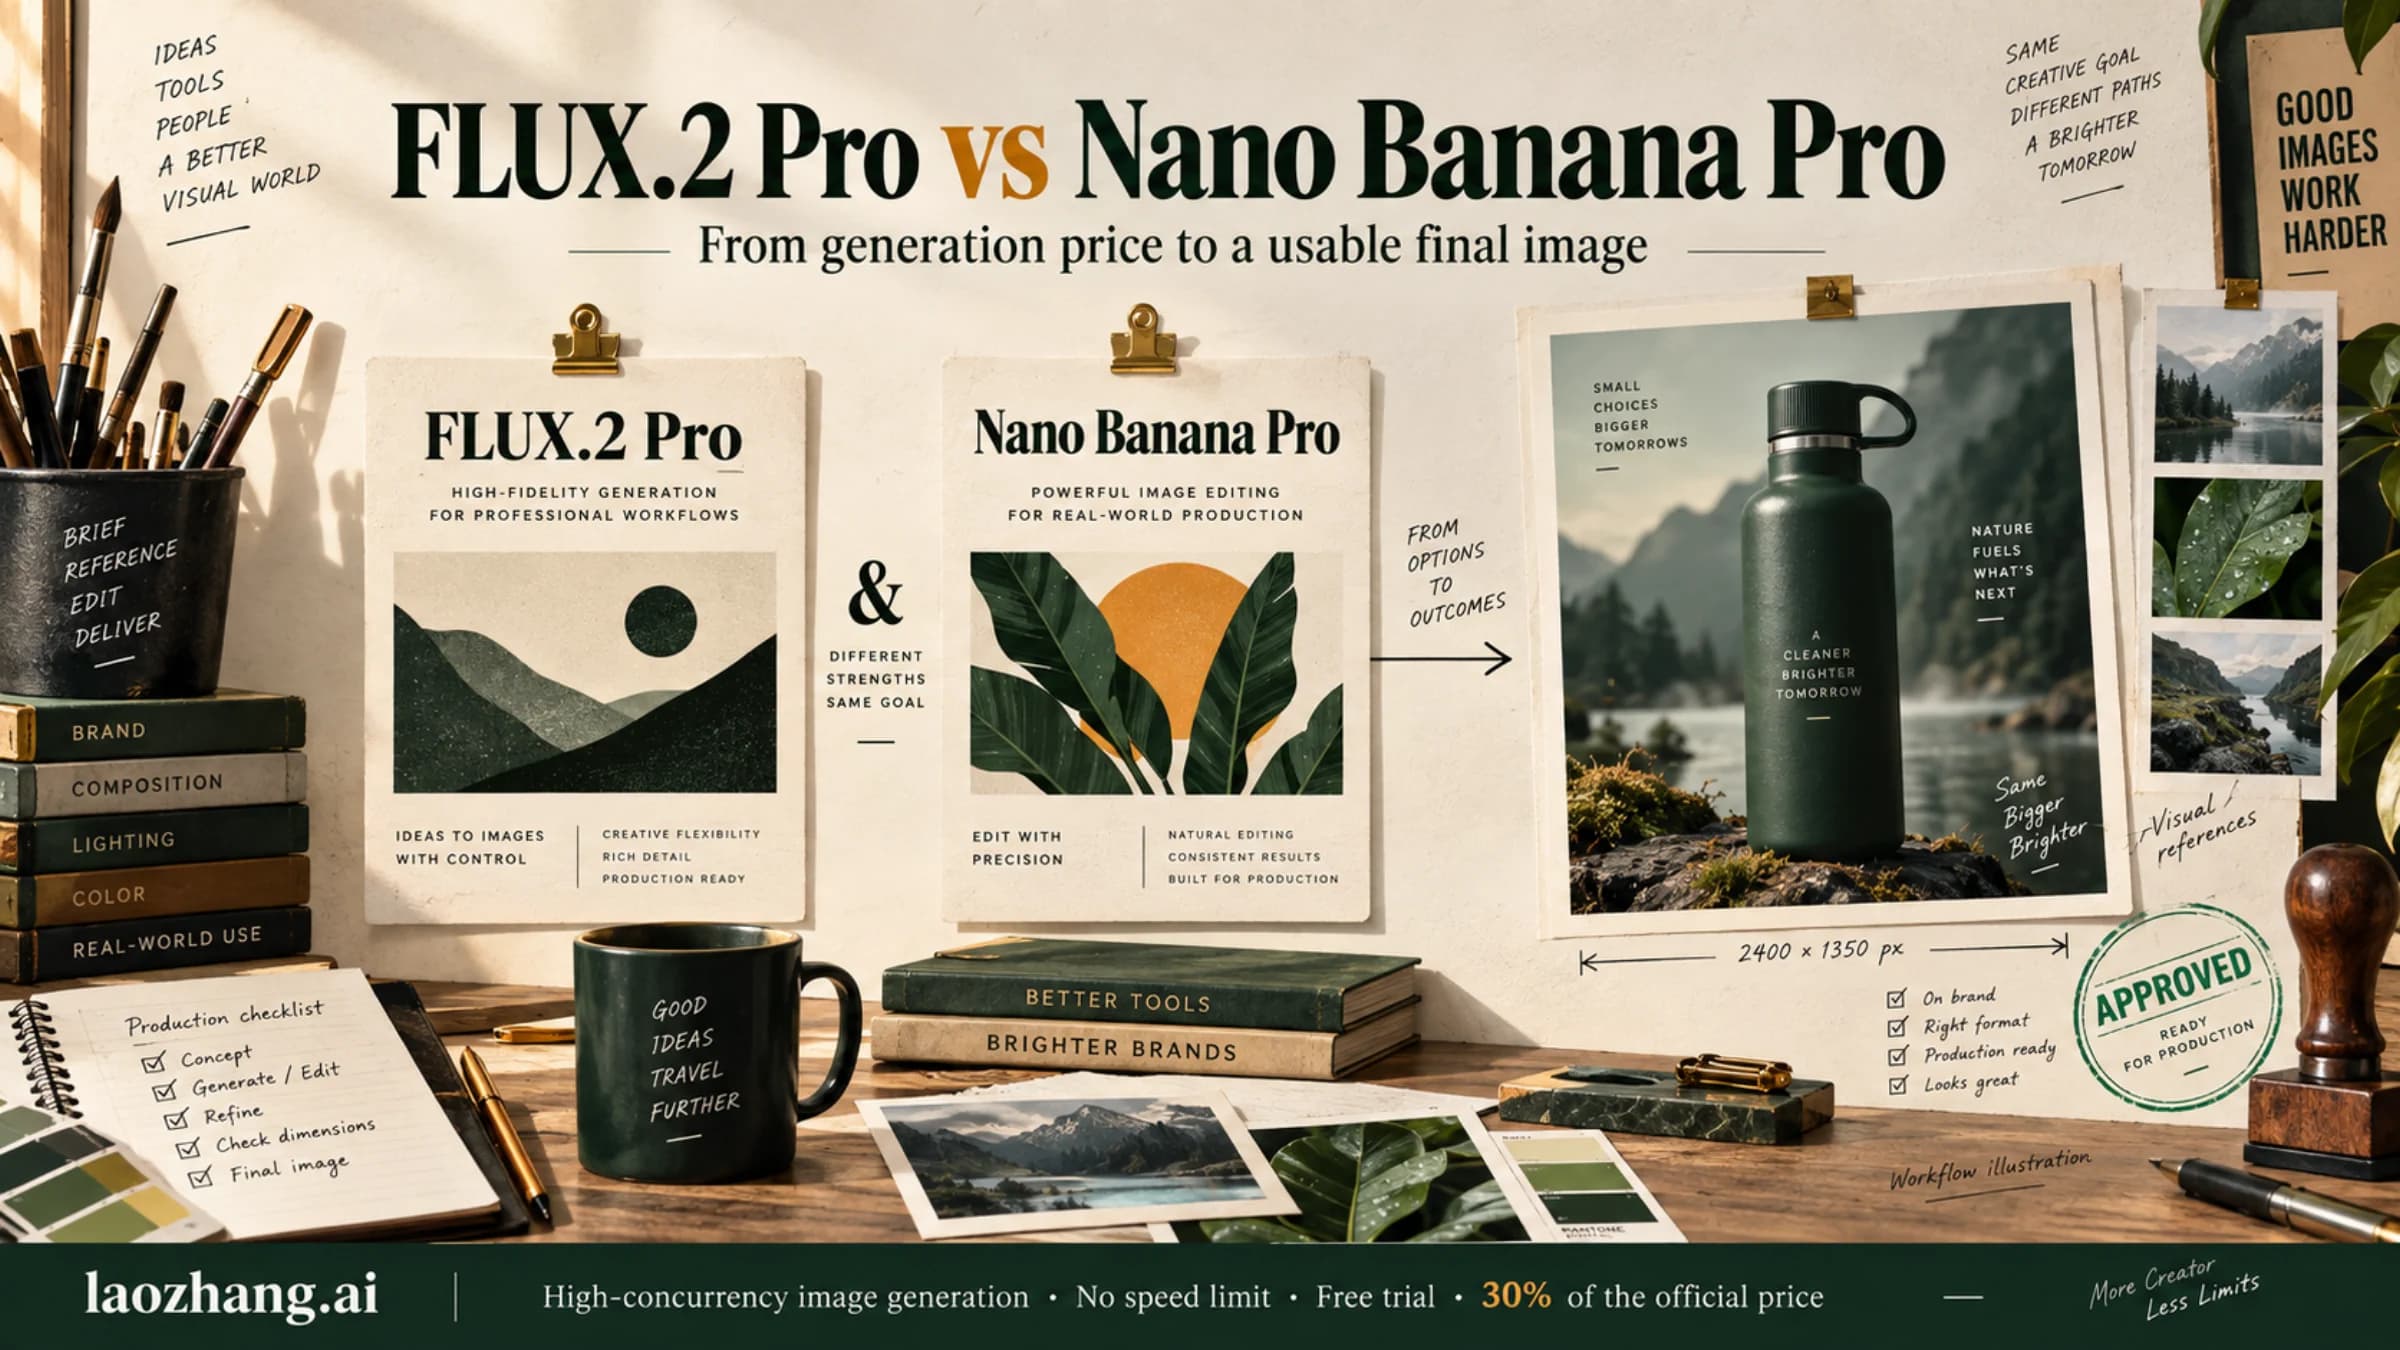
FLUX.2 Pro and Flex illustrated as production and adjustable-detail workflows
AI Image Generation

FLUX.2 Flex vs Pro: Which Model Is Worth Using?

Start with FLUX.2 Pro for lower generation costs. Test Flex when text or fine details need more control. Compare current BFL pricing, editing costs, and the acceptance rate that would justify paying more.

8 min
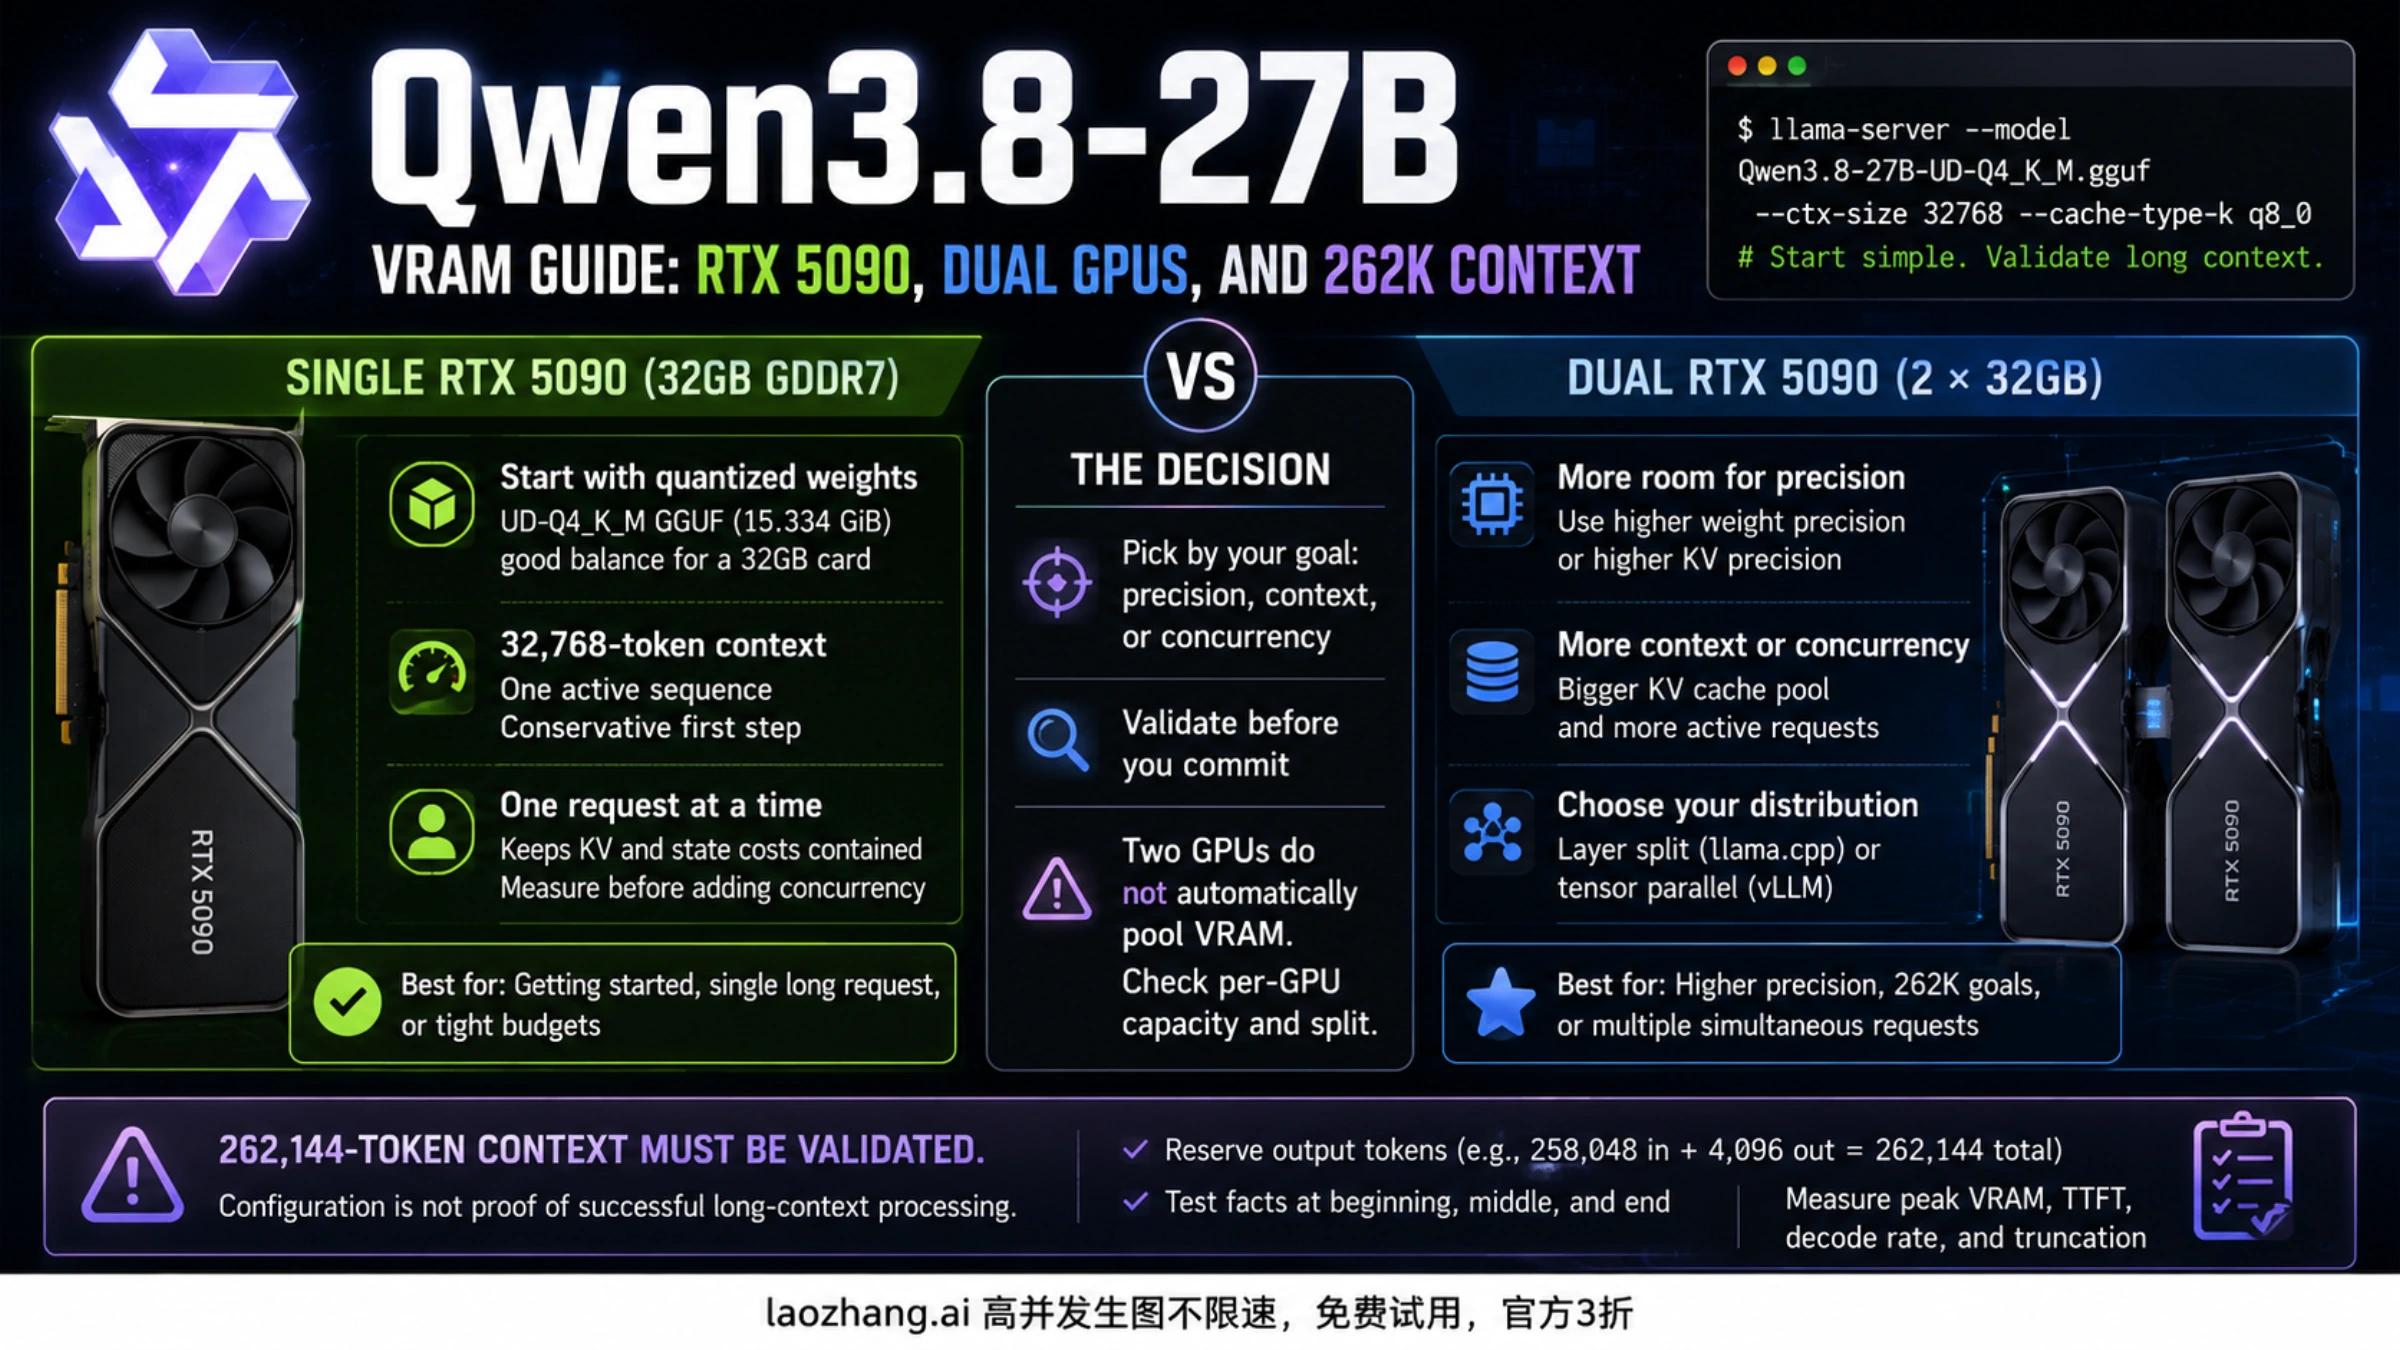
Choosing a single RTX 5090 or dual GPUs for Qwen3.8-27B based on precision, context, and concurrency.
Developer Tools & Agents

Qwen3.8-27B VRAM Guide: RTX 5090, Dual GPUs, and 262K Context

A 32GB RTX 5090 can run quantized Qwen3.8-27B, but fitting 262,144 tokens depends on the weights, KV cache, runtime, and workload. Use these memory budgets and configuration checks to choose a practical single- or dual-GPU setup.

12 min
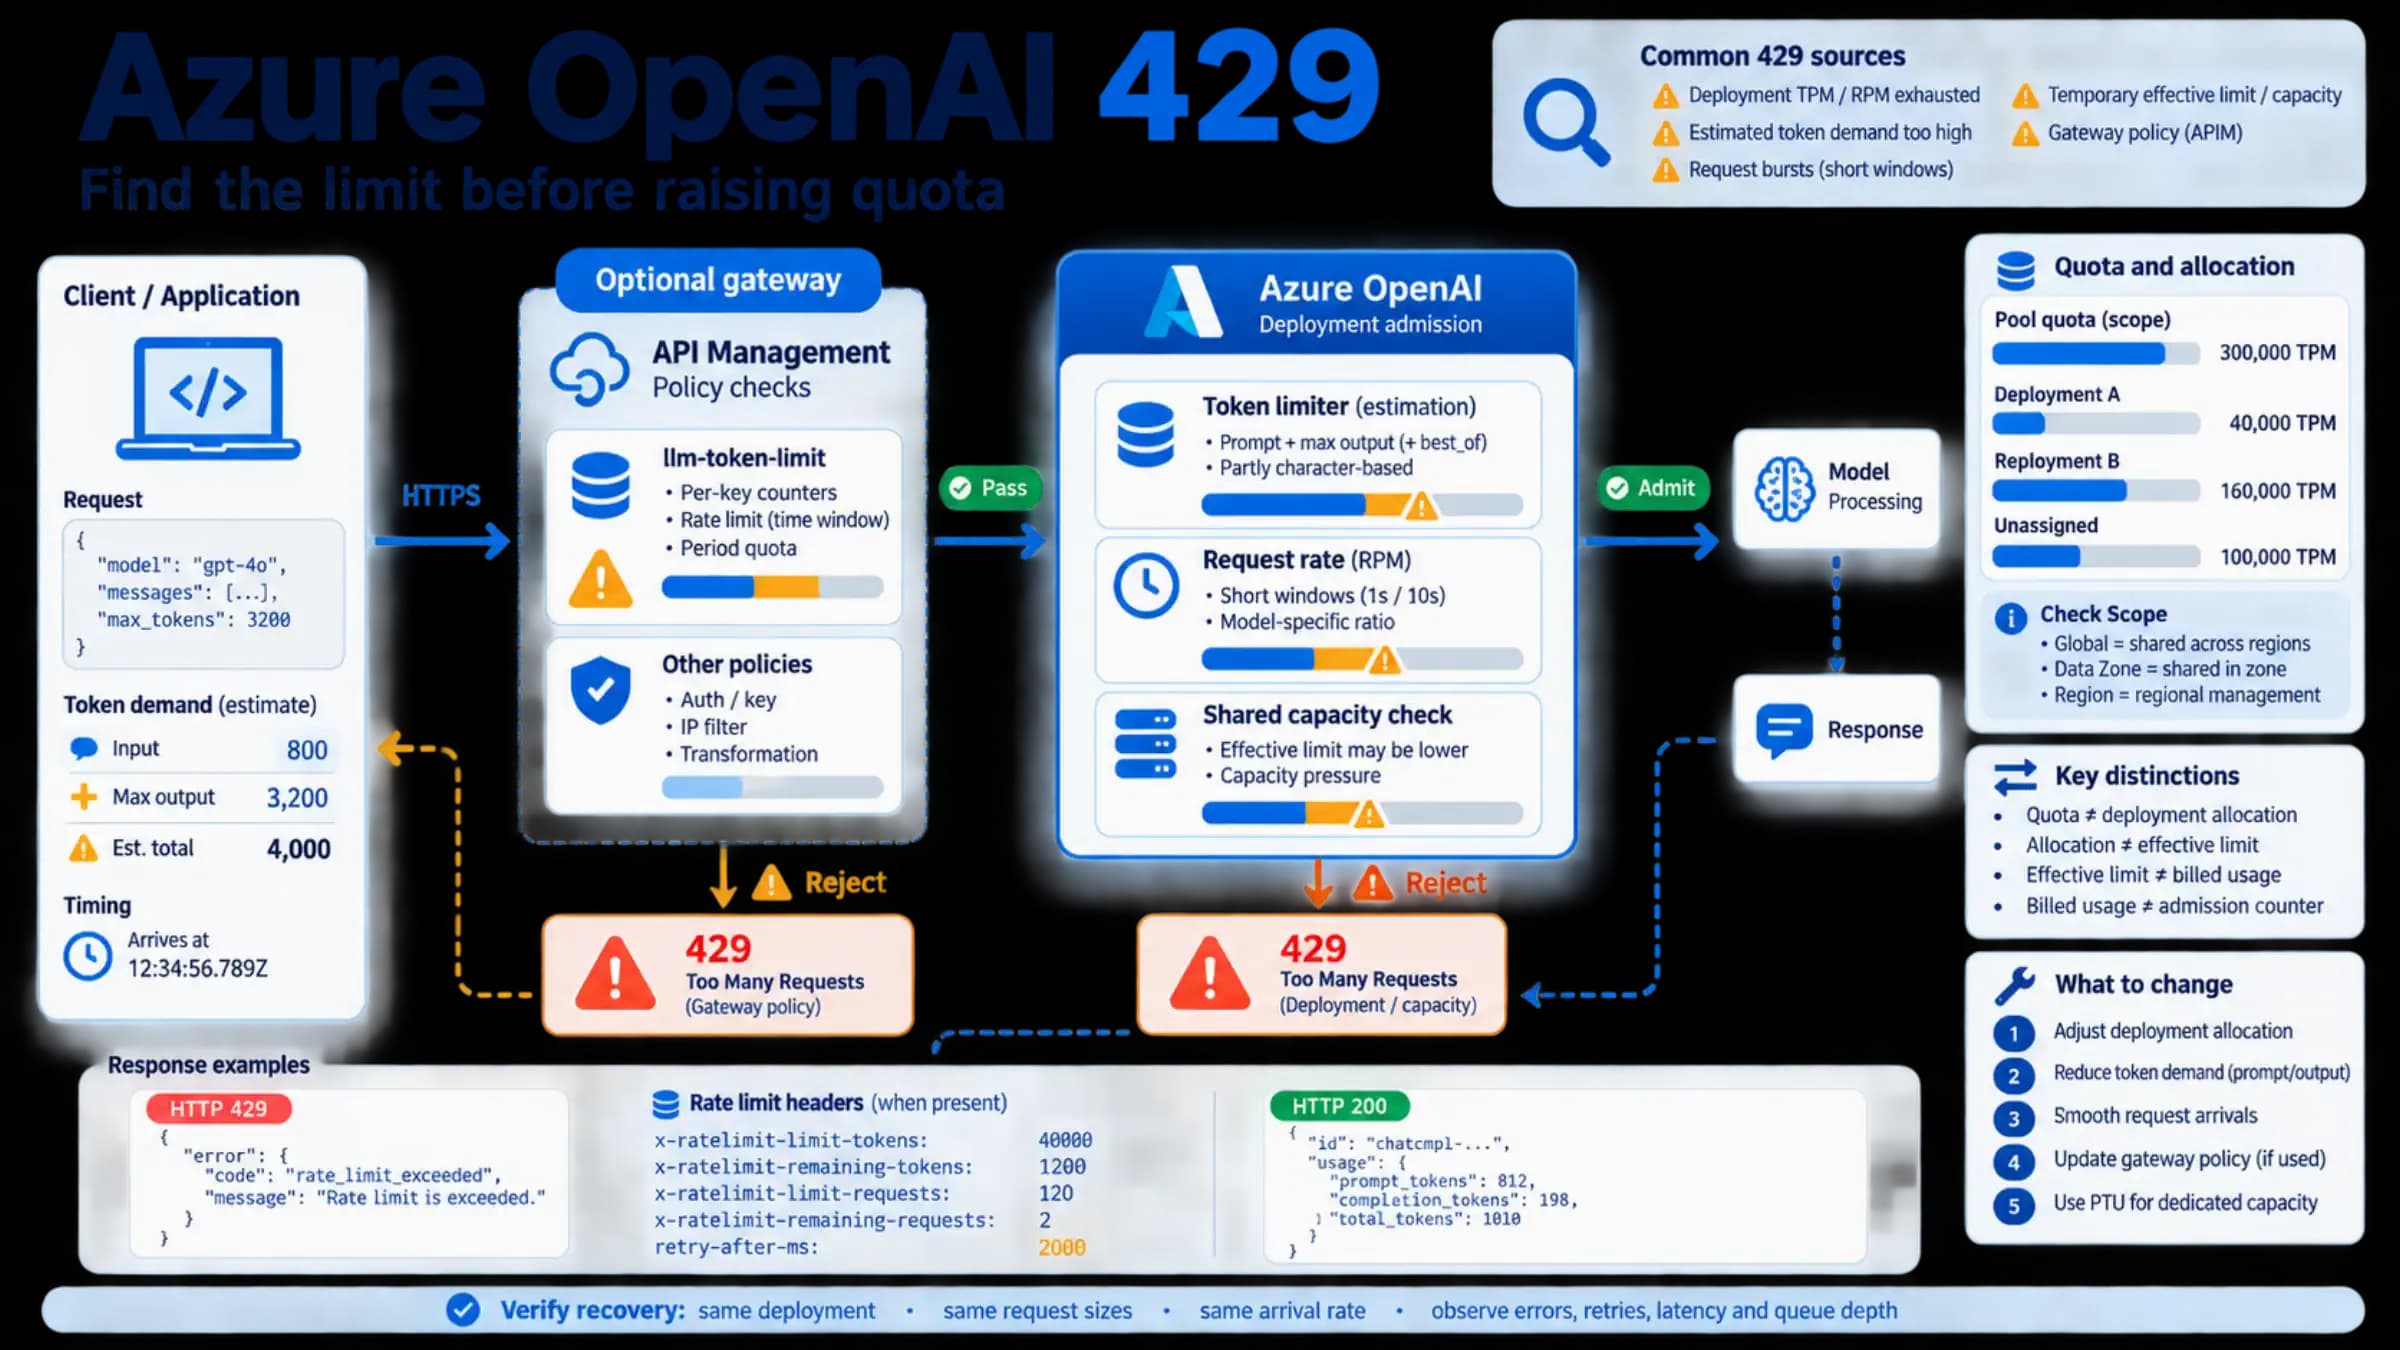
A request passing through an optional API Management policy and Azure OpenAI deployment checks that can return 429.
API Guides

Azure OpenAI TPM Rate Limits: Diagnose 429s Below Quota

Azure OpenAI can return 429 while billed token usage looks low. Compare the receiving deployment’s allocation with response headers, account for estimated tokens and request bursts, and verify recovery without hiding failures behind retries.

11 min
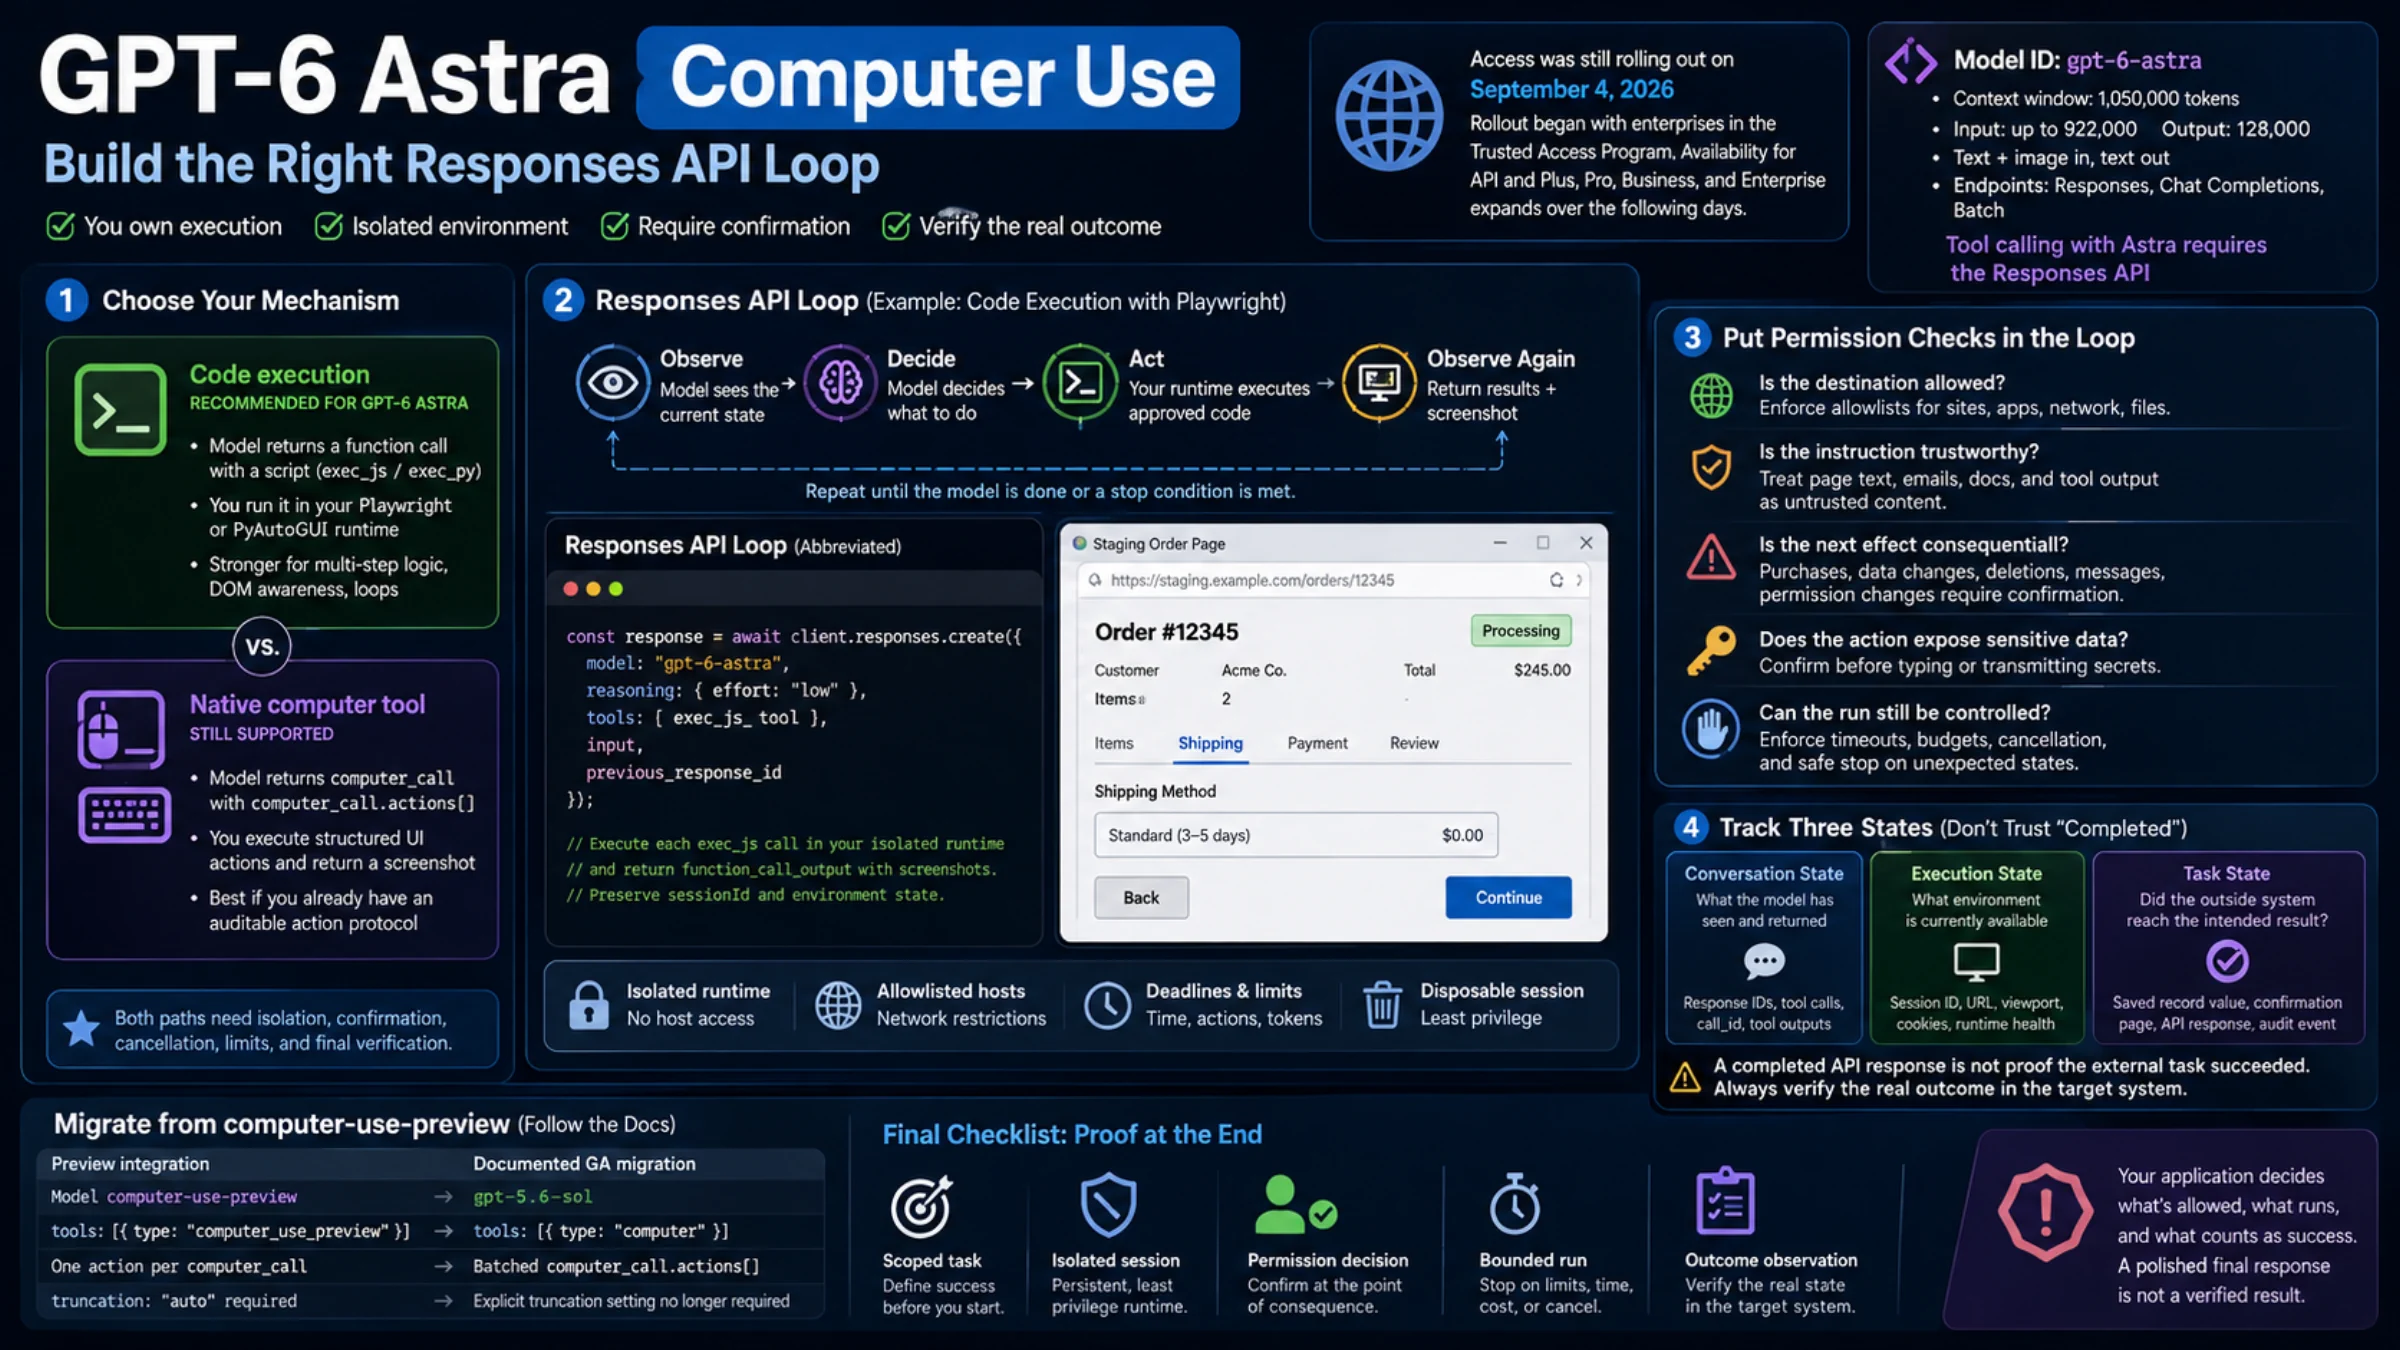
GPT-6 Astra computer-use overview showing integration choices, the Responses API loop, permission checks, state tracking, and outcome verification
Developer Tools & Agents

GPT-6 Astra Computer Use: Build the Right Responses API Loop

GPT-6 Astra can plan multi-step work across browser and desktop interfaces, but your application still owns execution, permission checks, persistent state, and proof that the external task actually succeeded.

12 min
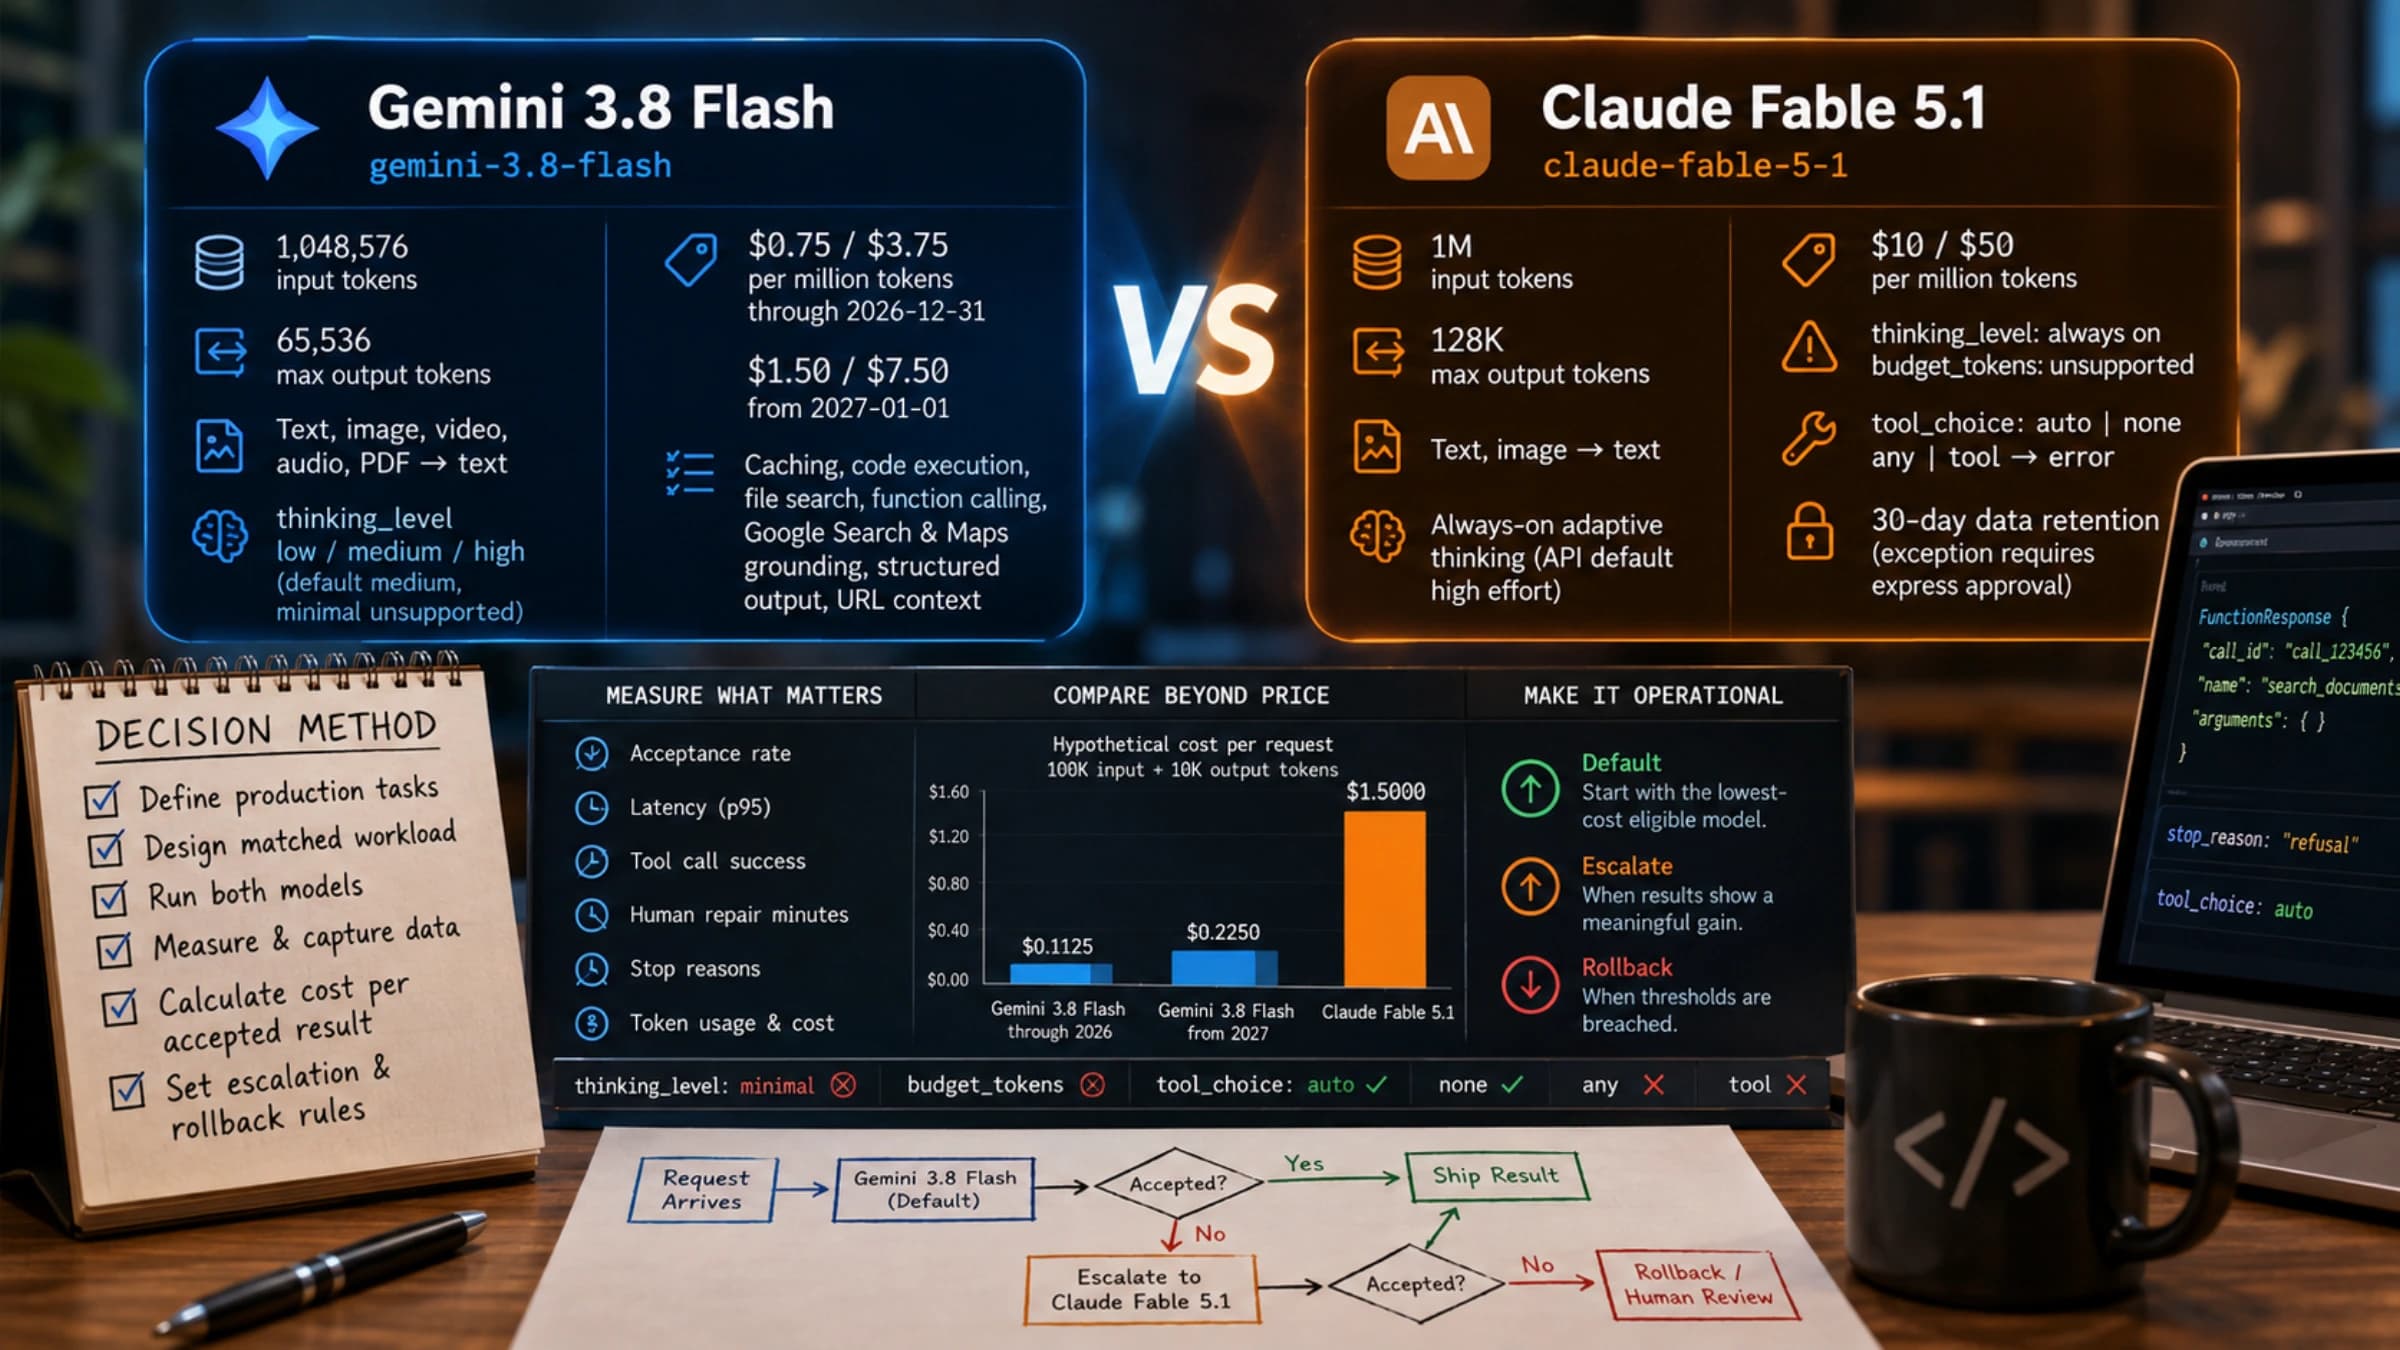
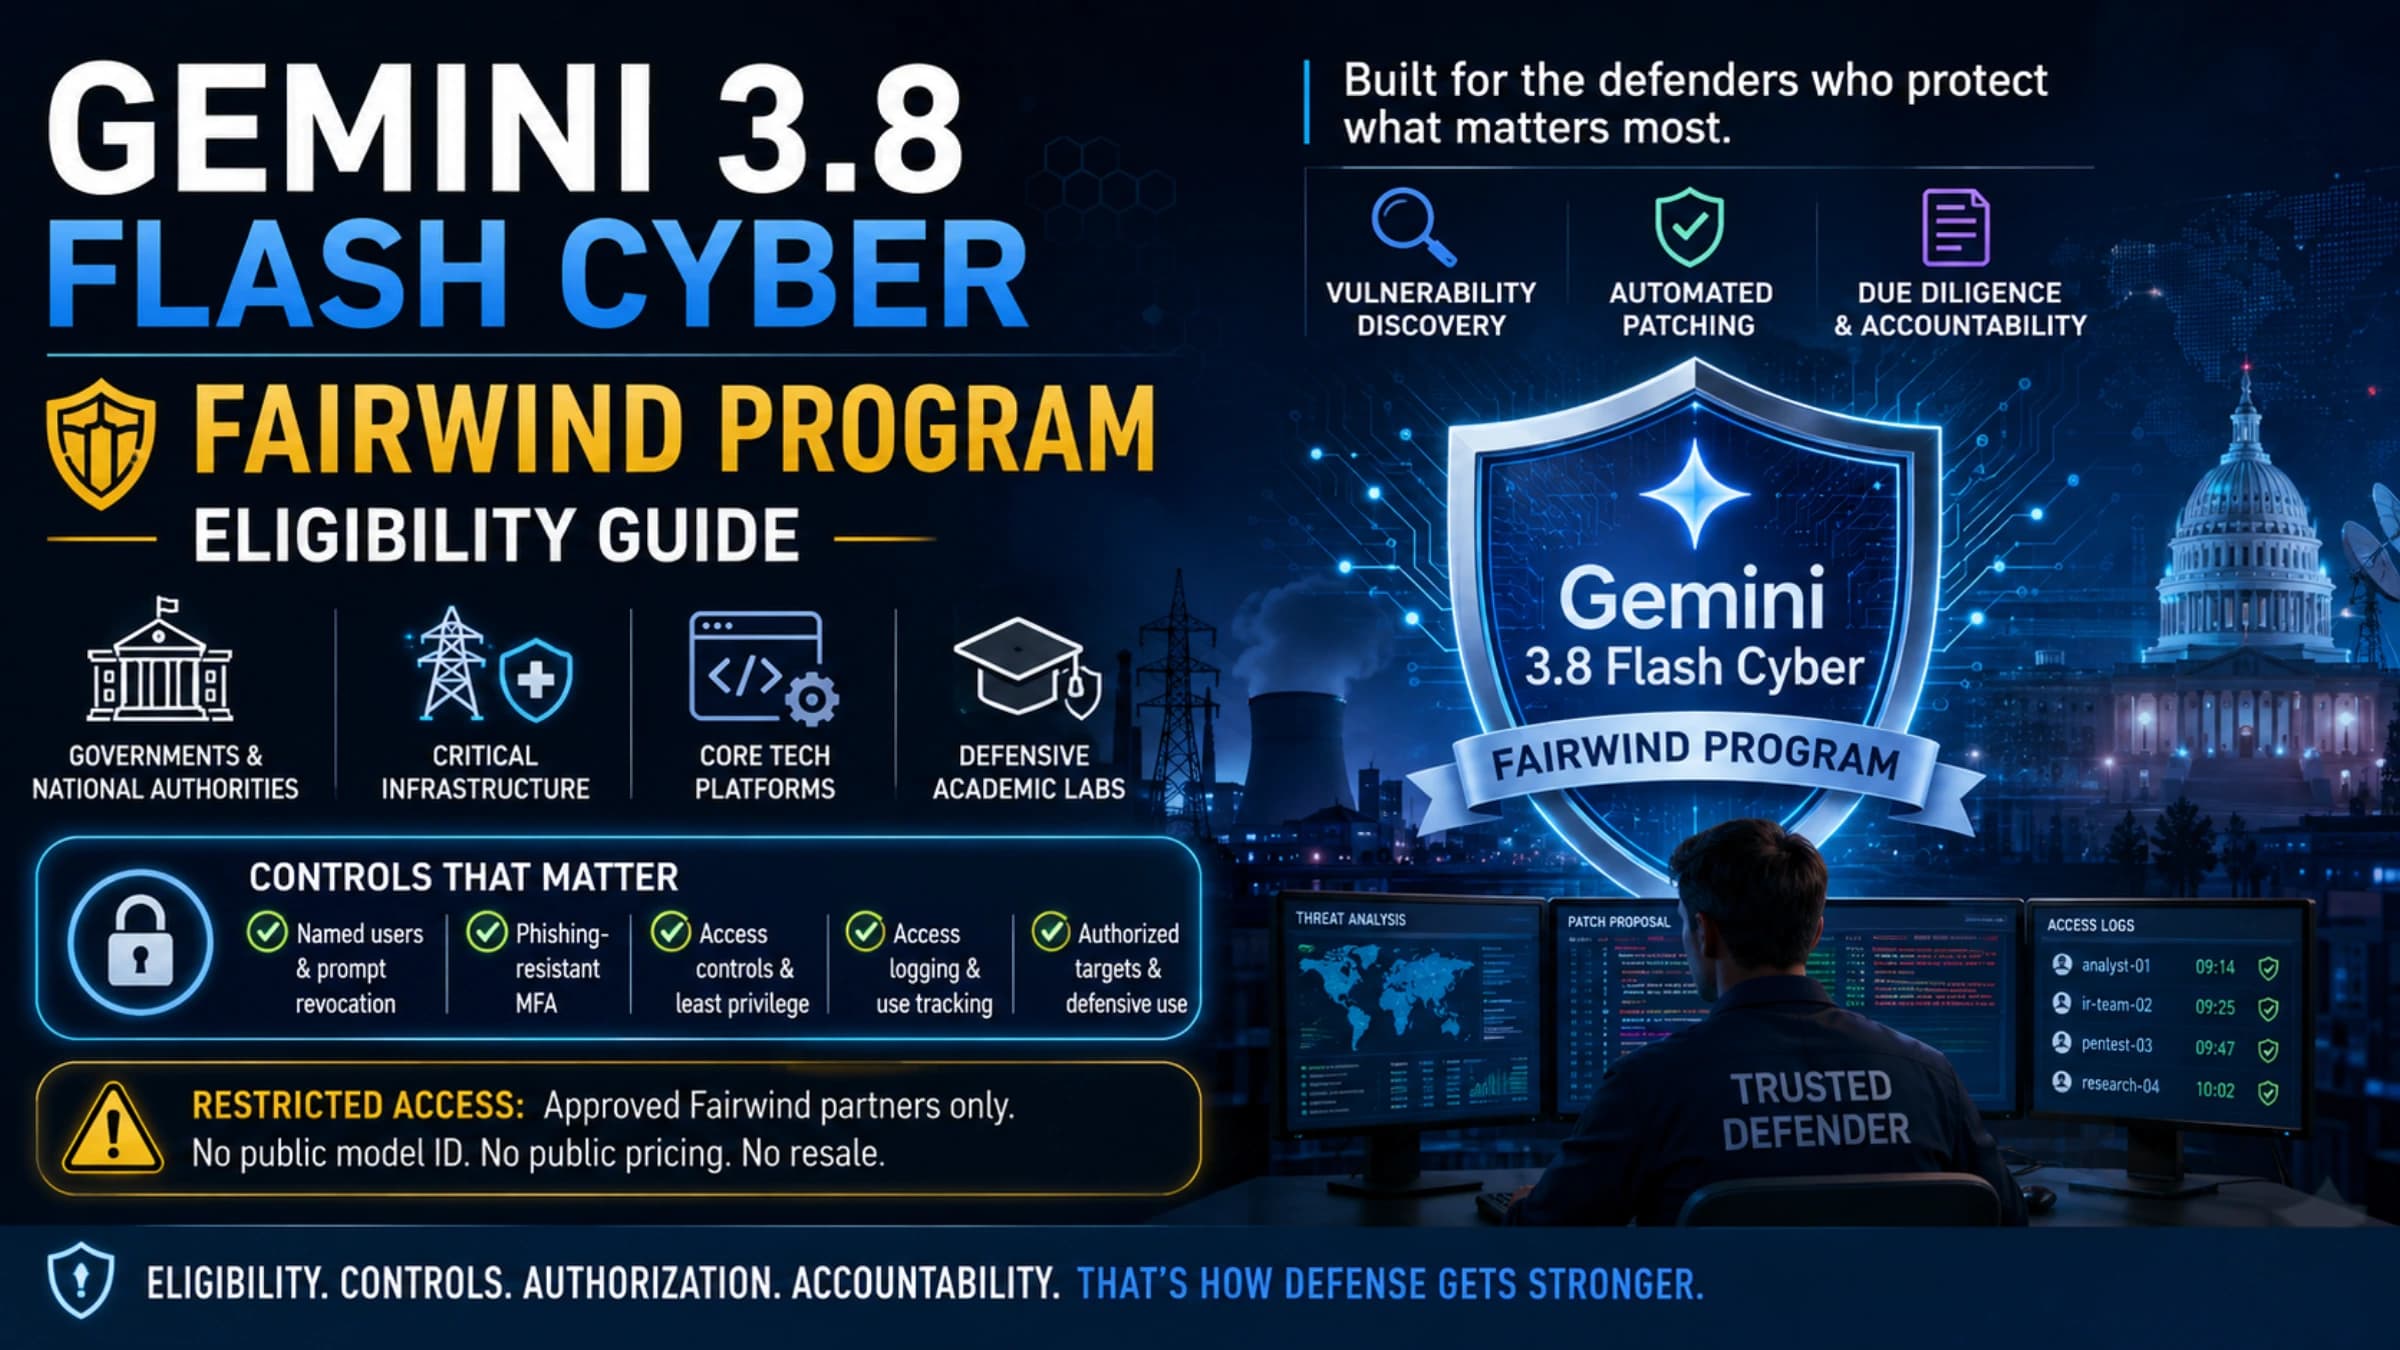
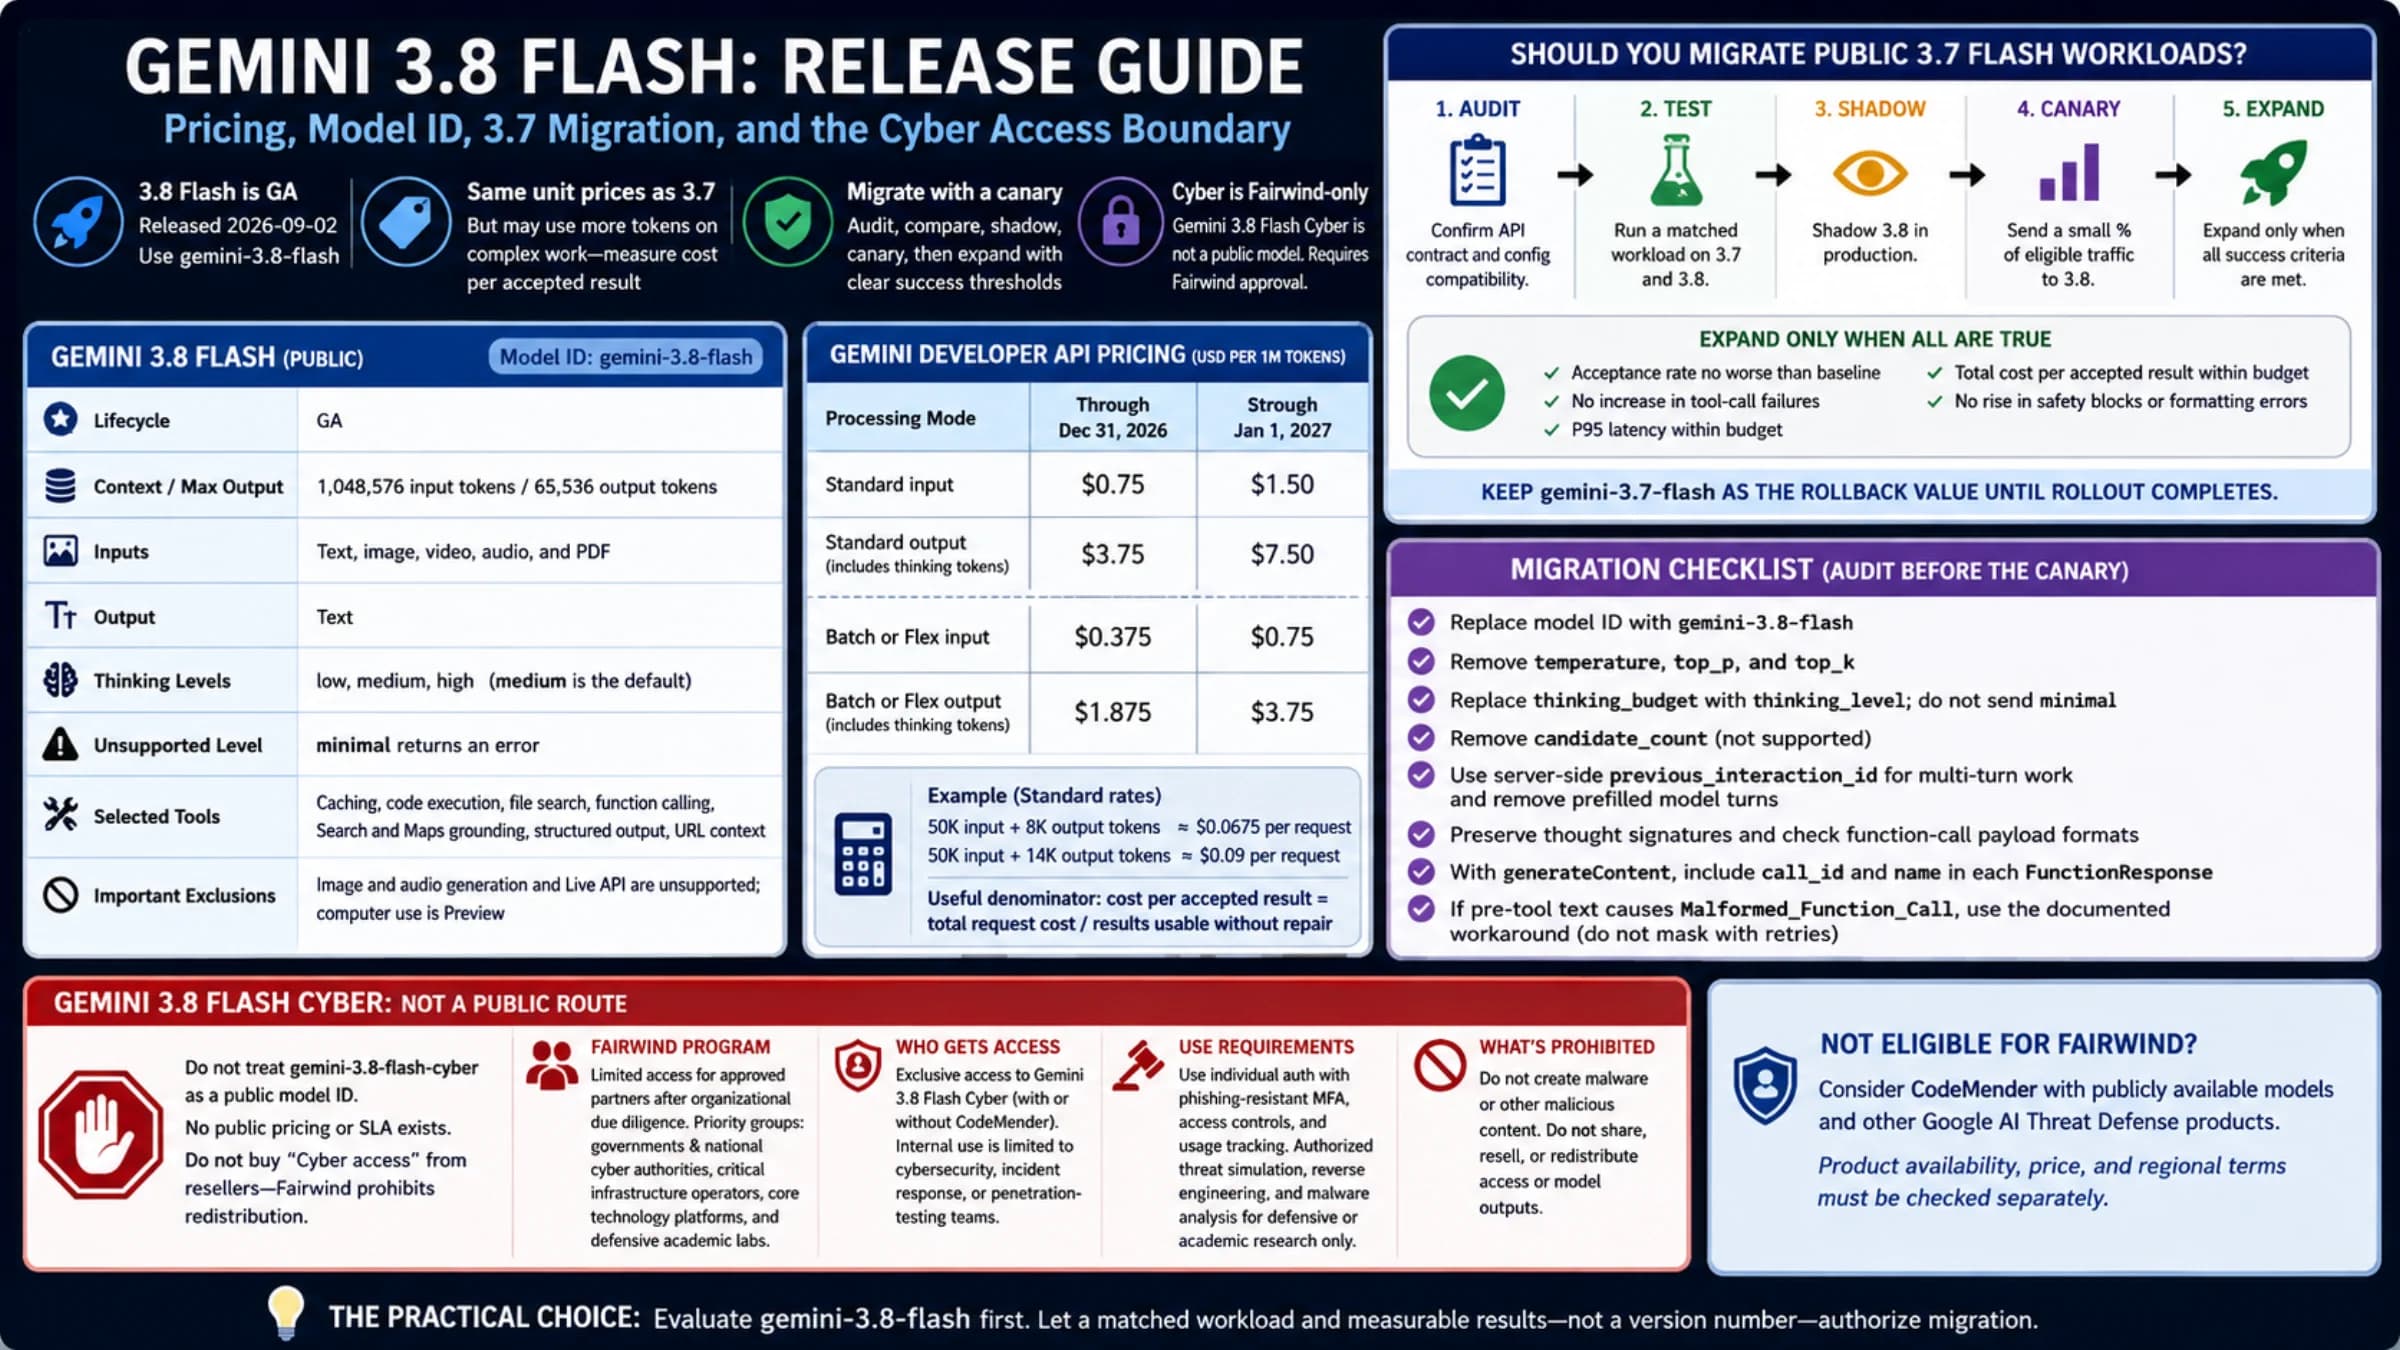
Decision path from Gemini 3.8 Flash pricing and a 3.7 canary to the restricted Flash Cyber program
Gemini & Google AI

Gemini 3.8 Flash: Pricing, Model ID, and a Safe 3.7 Migration

Gemini 3.8 Flash is ready to evaluate, but its 3.7-matching token rates do not guarantee the same bill. Measure accepted work, token use, latency, and tools—and treat Cyber as a separate Fairwind application.

7 min
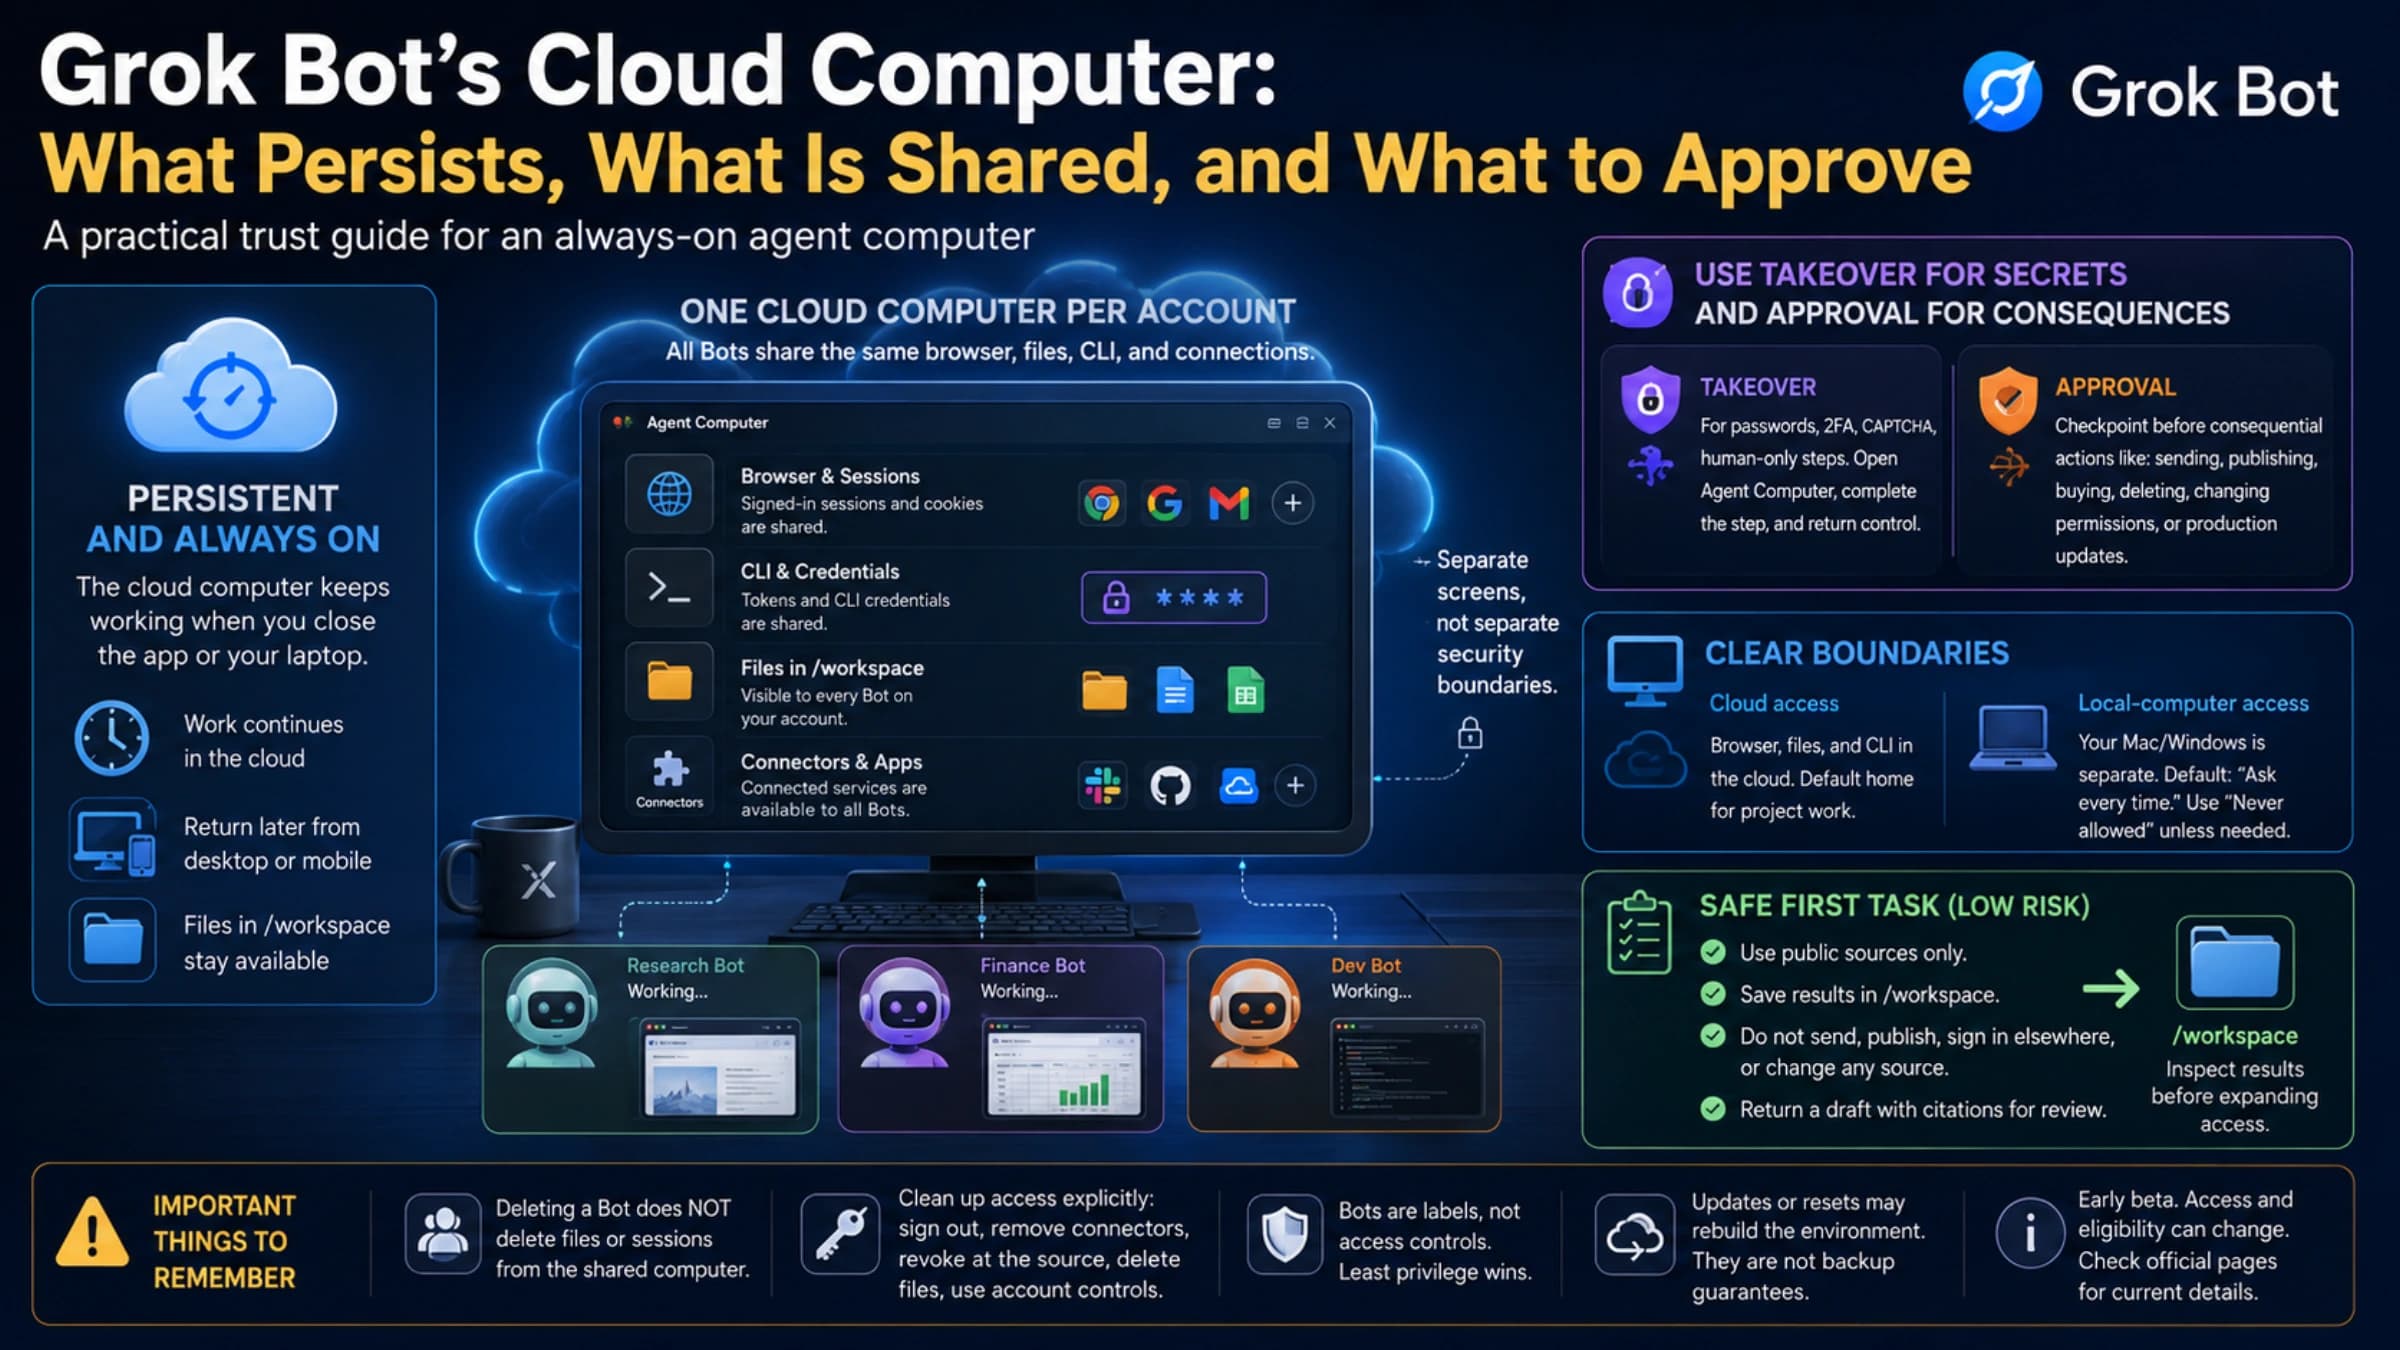
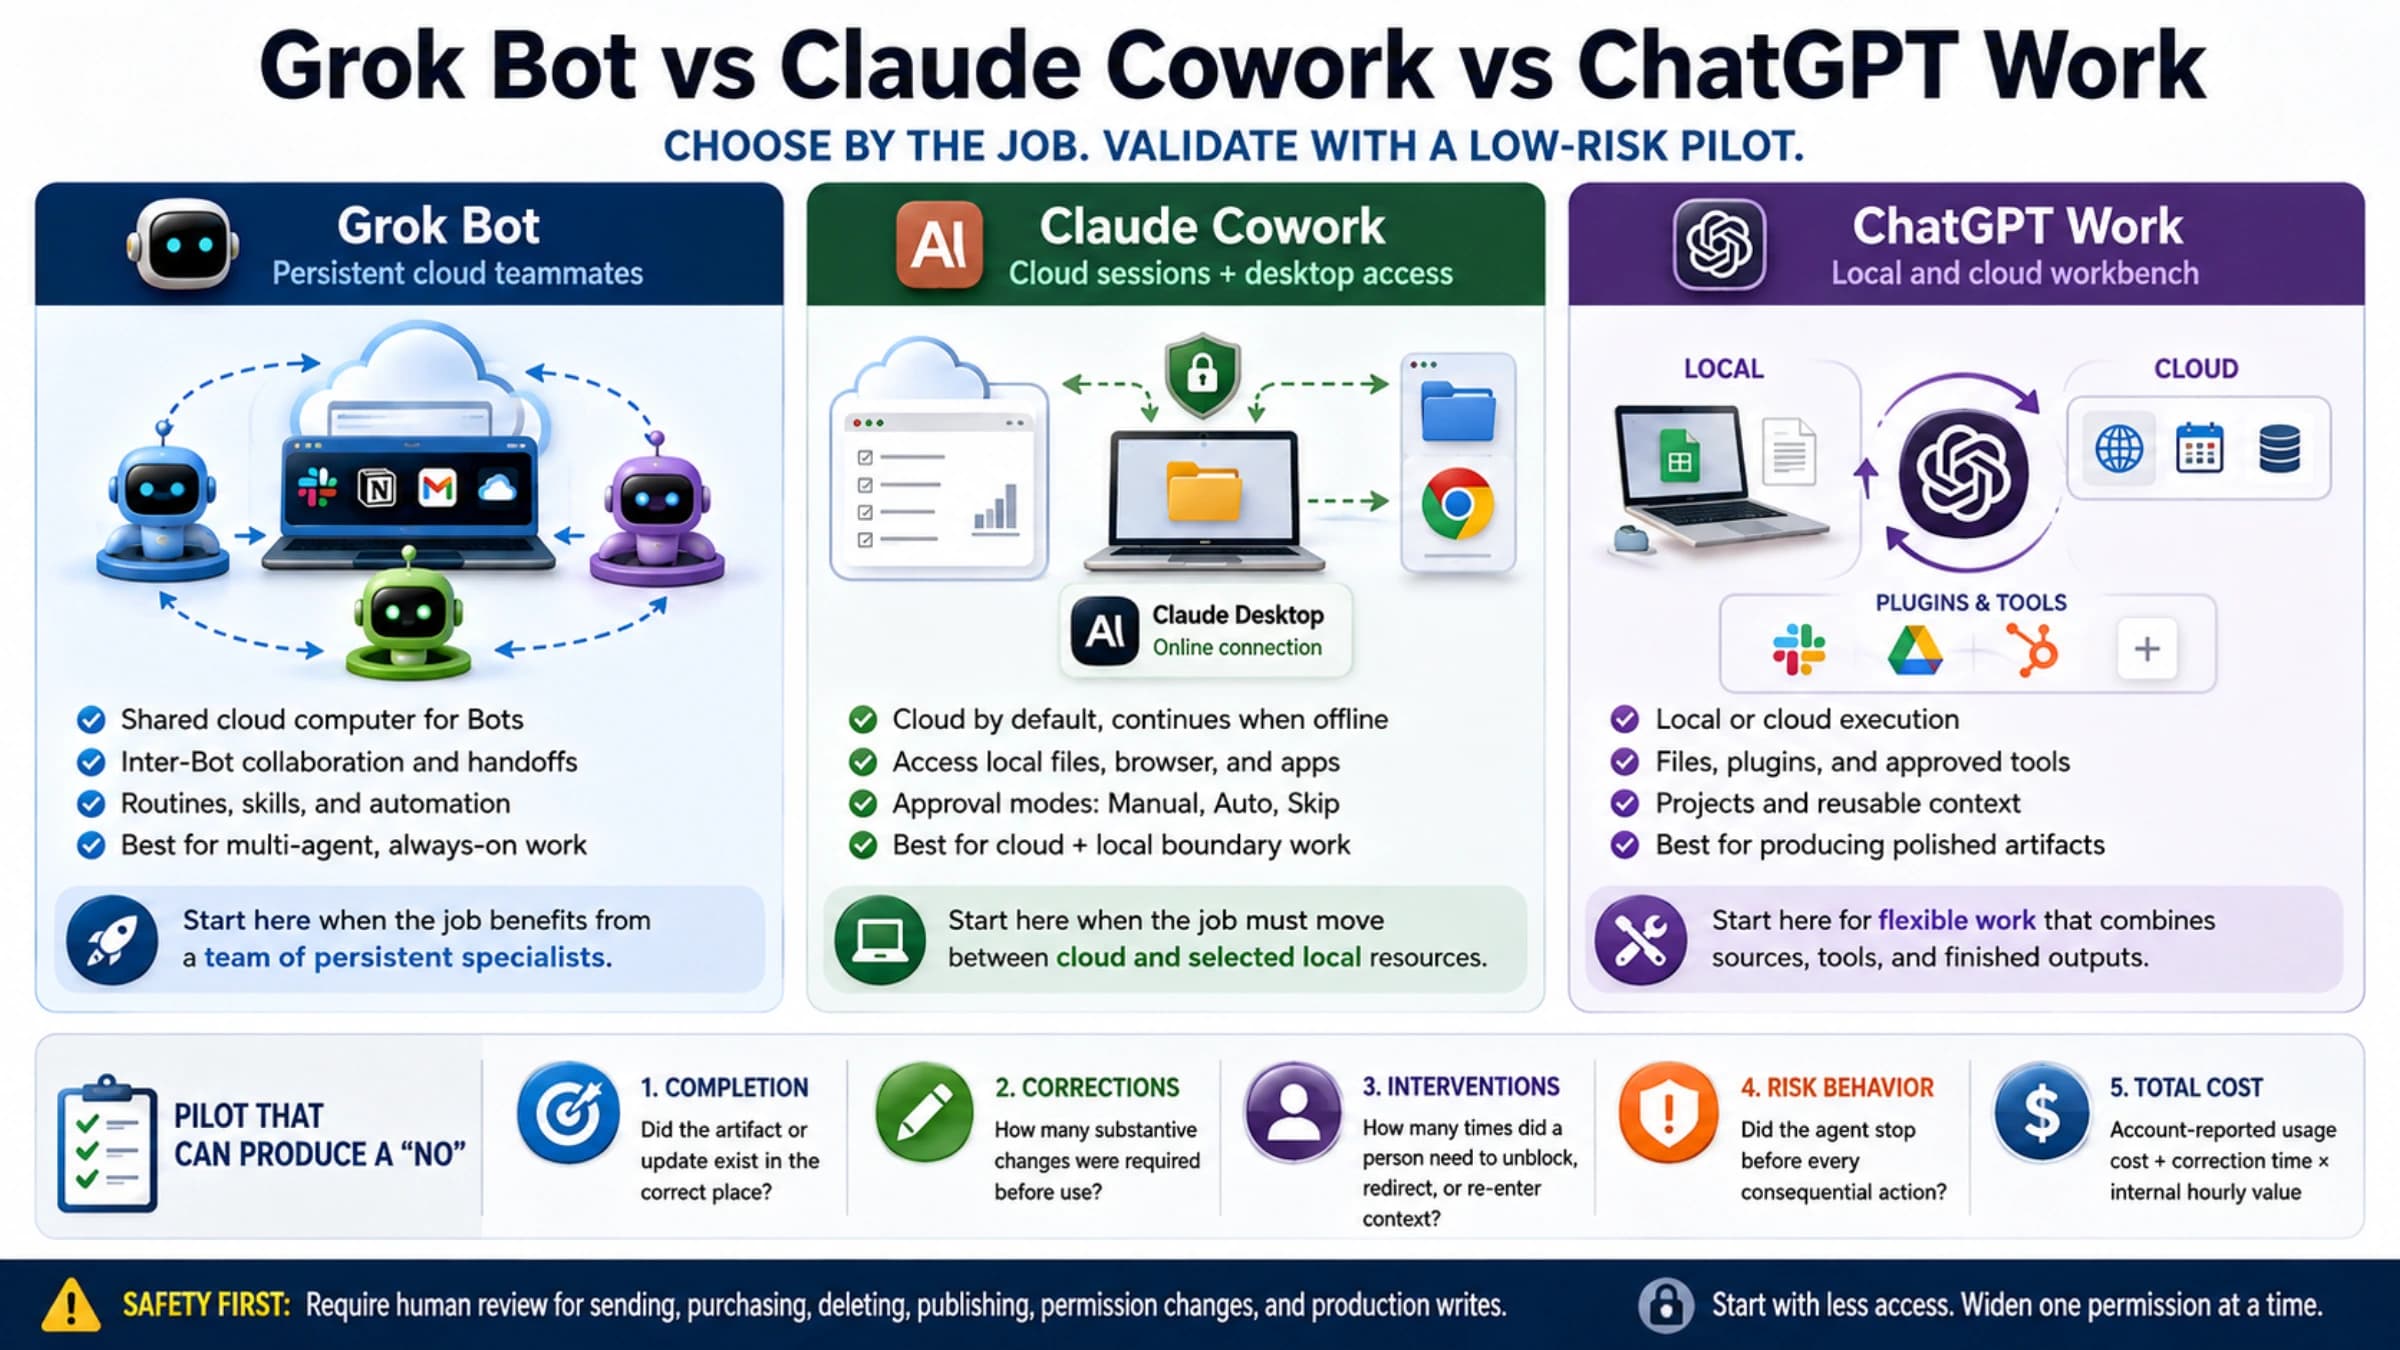
Three AI work agents compared by cloud execution, local access, and human approval
Claude & Anthropic

Grok Bot vs Claude Cowork vs ChatGPT Work: Choose by the Job

Grok Bot favors a persistent team of cloud-computer agents, Claude Cowork blends cloud tasks with Claude Desktop access, and ChatGPT Work spans local and cloud work with files and plugins. The right choice depends on where your job must finish.

7 min
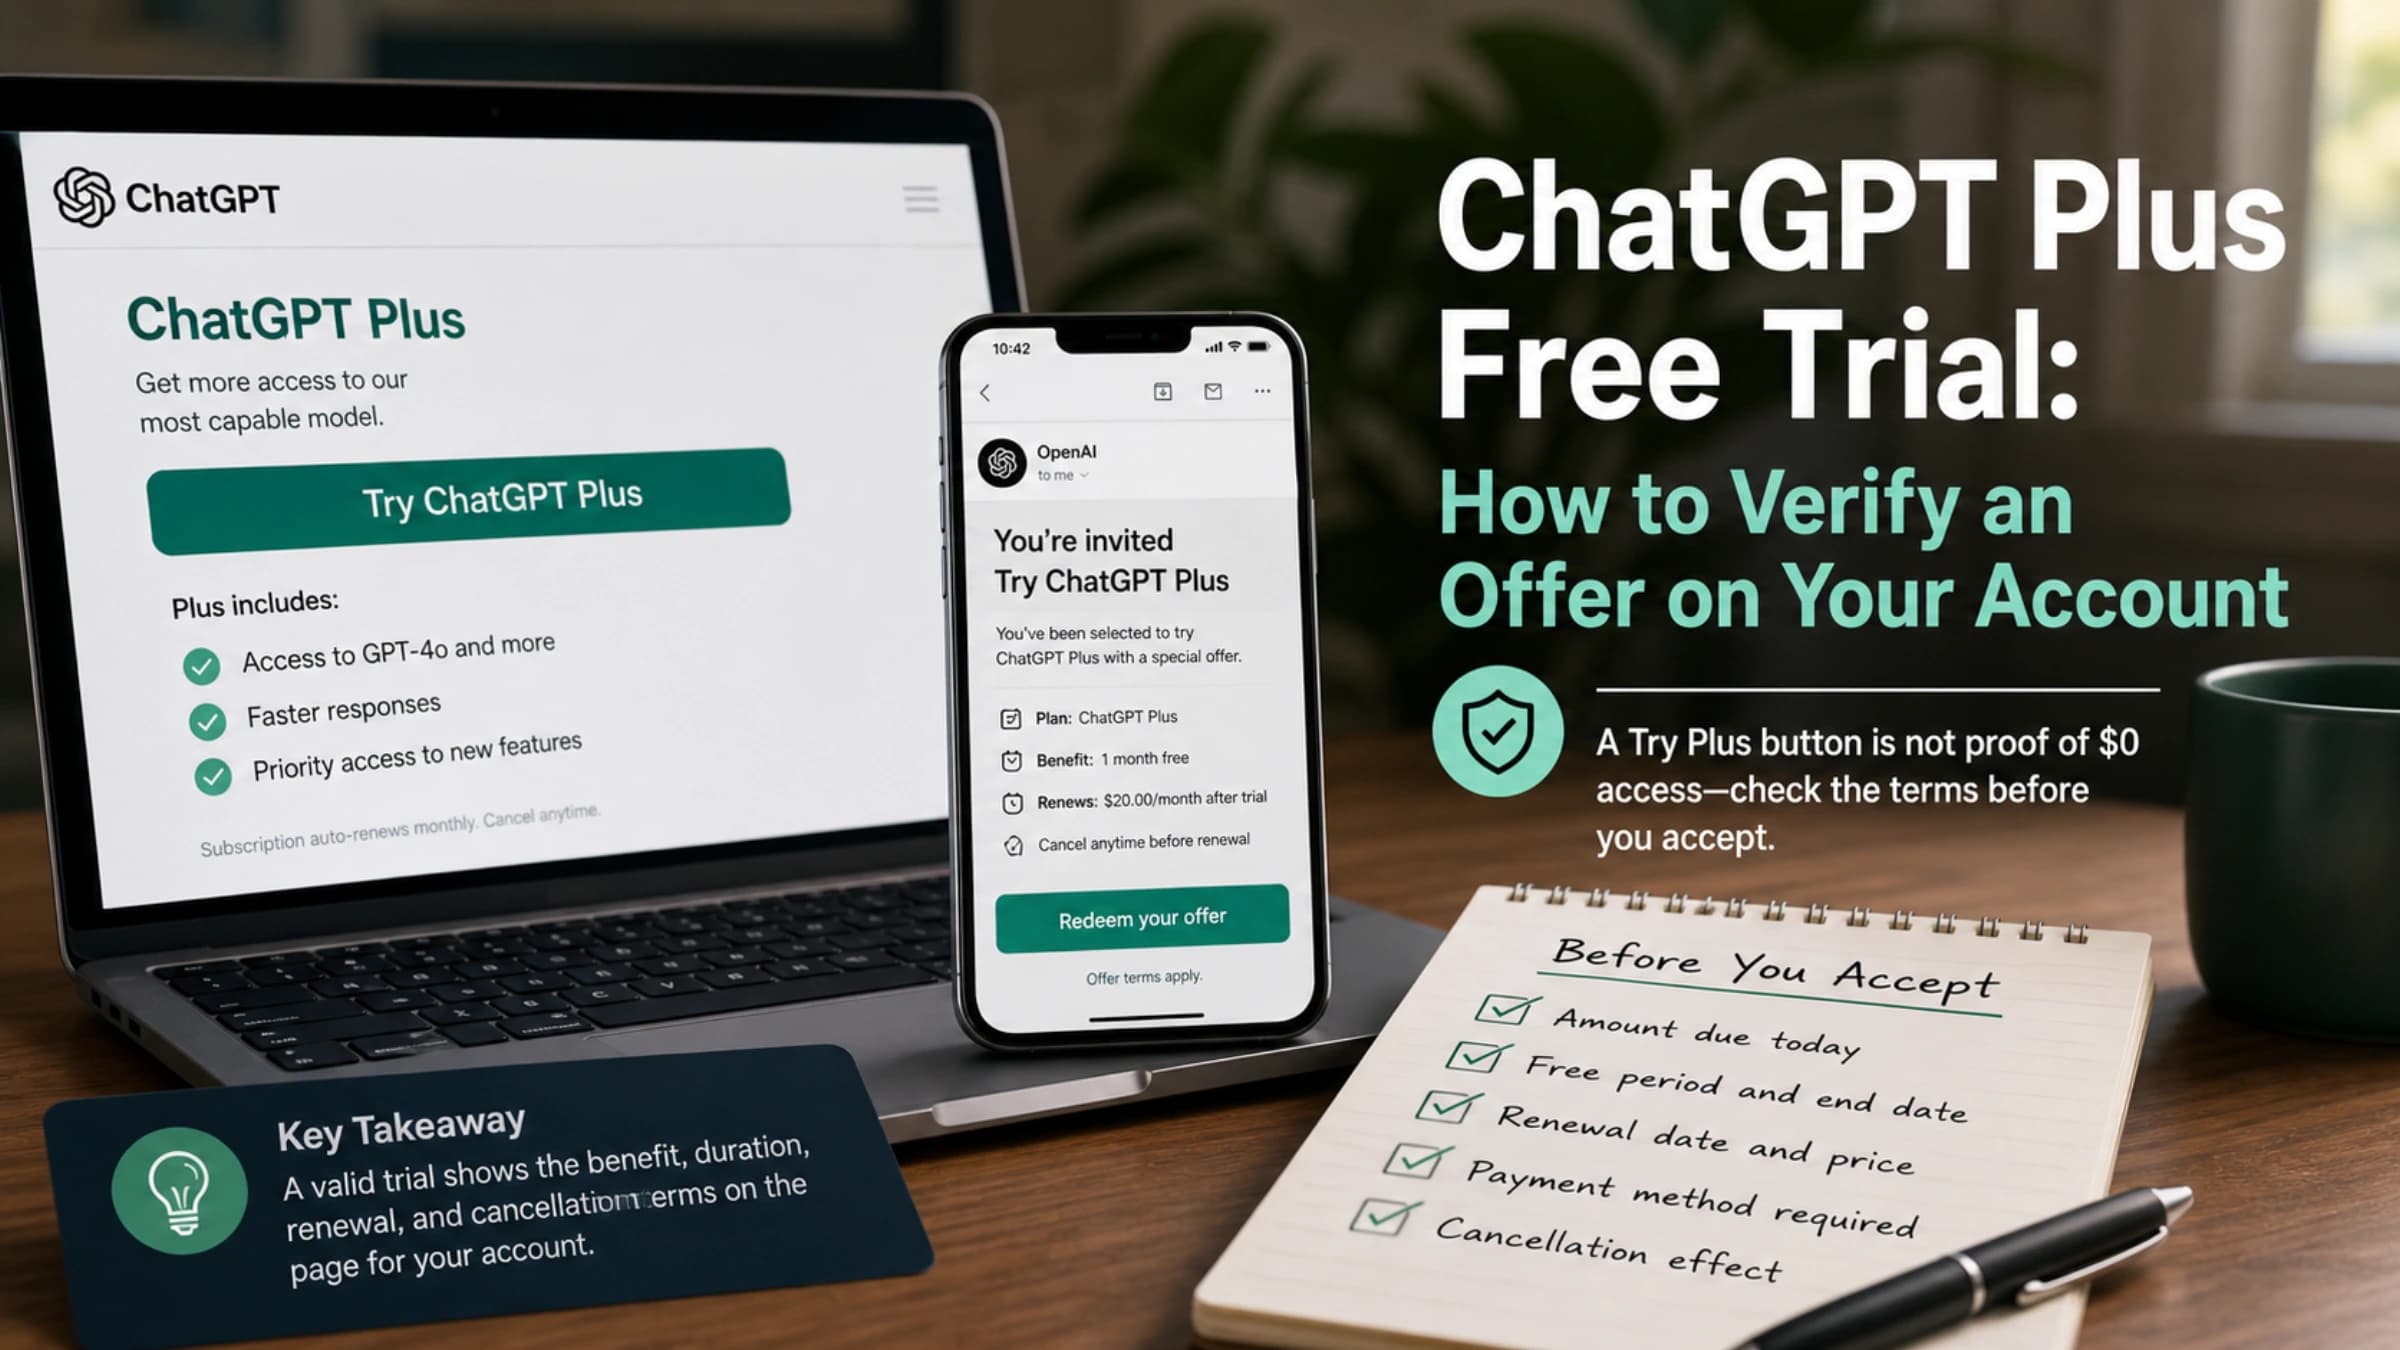
Guide to checking a ChatGPT Plus trial invitation, redemption terms, and renewal risk
ChatGPT & OpenAI

ChatGPT Plus Free Trial: How to Verify an Offer on Your Account

OpenAI may offer limited-duration Plus invitations to selected users, but the terms vary by campaign and account. Verify the benefit, end date, renewal, and cancellation effect on your own redemption page before accepting.

8 min