Gemini "Requests ending with a model turn are not supported" Fix
Gemini 3.6 Flash and later, including Gemini 4 Argon, reject any request whose last turn is model (assistant). End contents on a user turn to fix the 400.
On this page
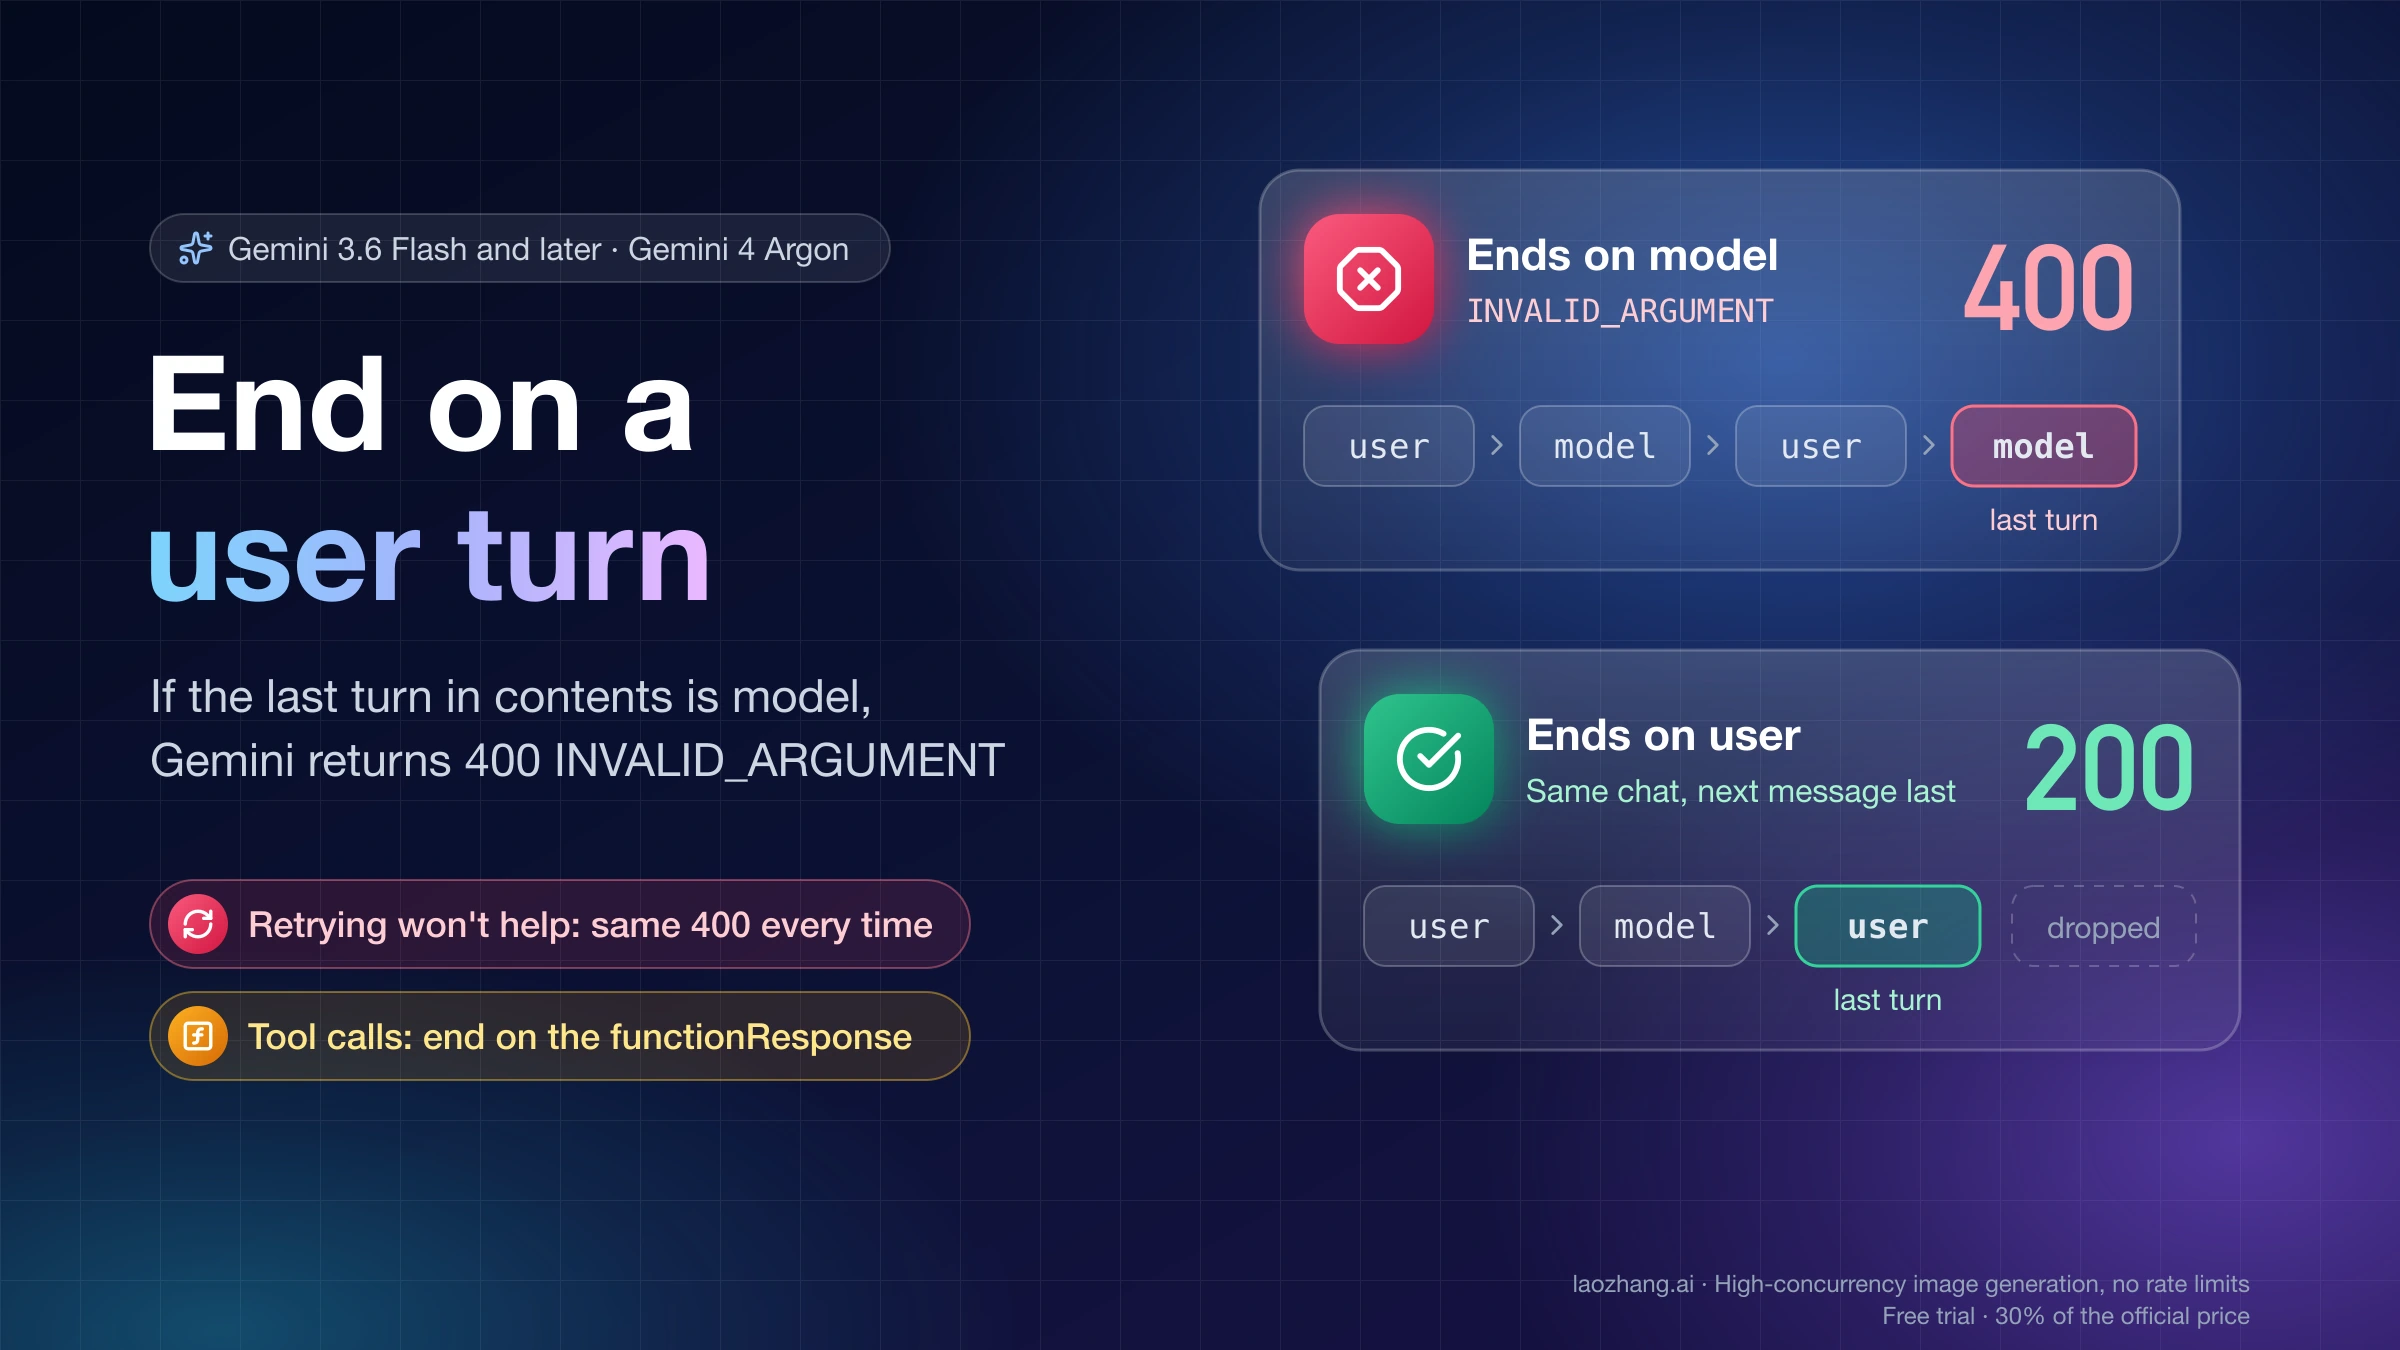
Requests ending with a model turn are not supported. is a 400 INVALID_ARGUMENT that Google returns when the last non-empty entry in your request's contents array has the role model, which is what OpenAI-style APIs call assistant. Google's What's new in Gemini 3.6 page applies the rule to Gemini 3.6 Flash, Gemini 3.5 Flash-Lite and every later model, so gemini-3.7-flash, gemini-3.8-flash and gemini-4-argon reject requests that older models accepted. Prefilling a model turn is simply no longer supported on these models.
The fix is to make the request you actually send end on a user turn. If your history stops on a saved model reply, append the user's next message before sending, or drop the trailing model turn. If you prefilled the start of the answer to force a format, move that instruction into systemInstruction or a JSON schema (structured output), which is what Google recommends instead. In a tool call, the last turn has to be the user turn that carries your functionResponse. Retrying the same request won't help, because it fails every time until its shape changes.
If you only use a tool, update or reconfigure it rather than your code. Gemini CLI fixed its rewind, interrupt and image cases in v0.65.0, and in SillyTavern-style front ends the usual cause is an assistant prefill or continue setting. The request-shape test below was run against gemini-4-argon on October 29, 2026, and the tool table further down covers opencode, LangChain, LiteLLM and OpenRouter-based agents.
What the error means and which Gemini models enforce it
Google checks the role of the last non-empty turn in the request, not what your chat window shows. The 3.6 migration page puts it plainly: "If the last non-empty turn in the request is a model turn, the API returns a 400 error," and the change applies to "these models and all future Gemini model releases." Gemini 4 Argon falls under that wording even though its own Gemini 4 Argon migration checklist (updated October 27, 2026) doesn't repeat the rule. In the test below, the same gemini-4-argon history returned 400 when it ended on the model's reply and 200 when it ended on the next user message, which is consistent with the rule. Older models are outside it: a LINUX DO thread from July 22, 2026 reports that prefill still worked on Gemini 3.5 Flash and stopped on 3.6 Flash, so the error says nothing about your key, account or quota.
The same rule reaches you under several wrappers. Most SDKs and issue logs show 400 INVALID_ARGUMENT with the short sentence. Some routes return the longer form, Requests ending with a model turn are not supported unless the last part is a function response., which names the one exception: a final user turn whose last part is a functionResponse. AI Studio-backed proxies may prefix [original: beyond::dependency::INVALID_ARGUMENT], role-play proxies print PROXY ERROR 400: {...}, and OpenRouter returns Provider returned error with Google's text inside error.metadata.raw. Some clients put "Please try again later" in front of it, which is misleading here.
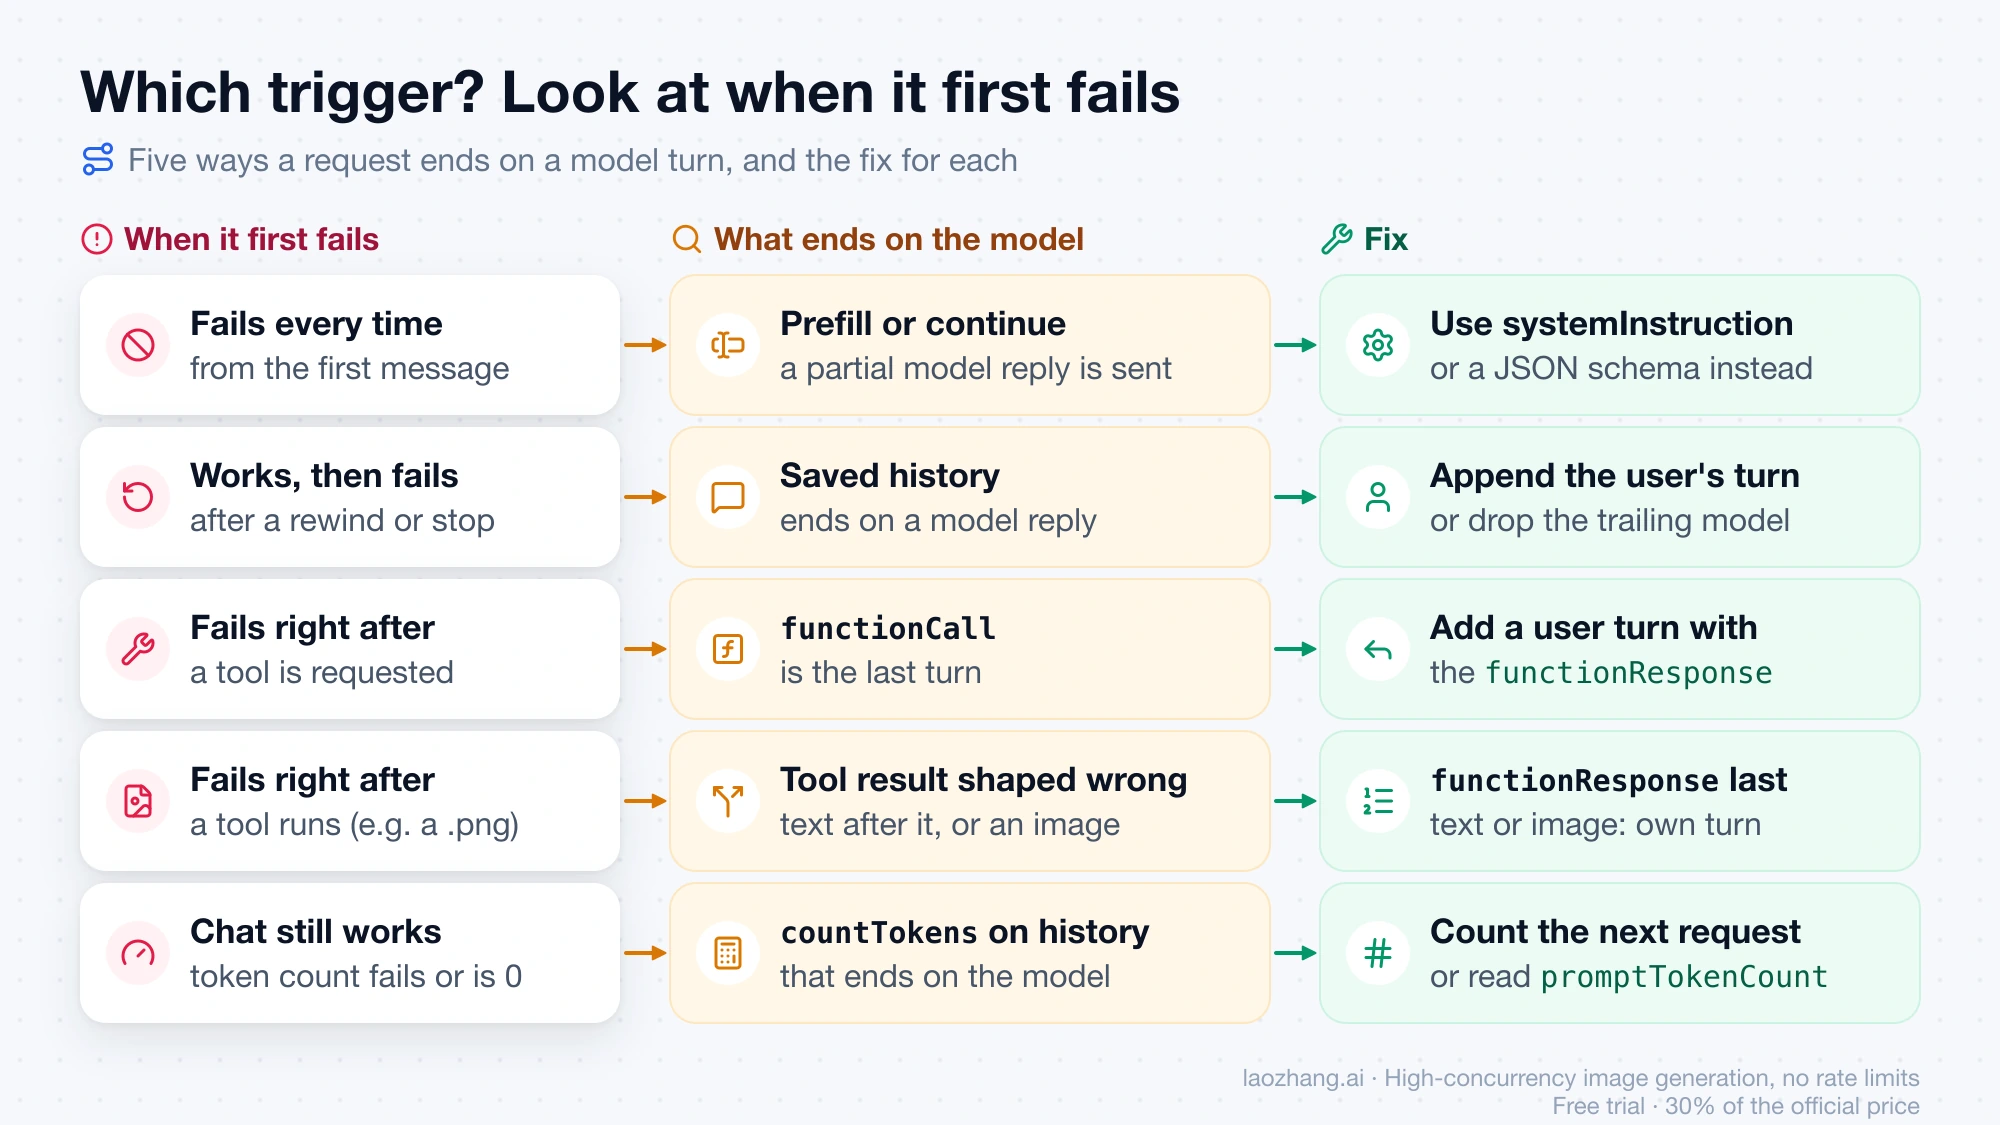
Which trigger are you hitting: five ways a request ends on the model
When the error first appears tells you most of what you need. If every request fails from the first message, something adds a model turn on purpose, which is prefill. If a session works for a while and then breaks after a rewind, an interruption or a tool call, the history was saved or converted with a model turn last. If replies still arrive but a token counter or context meter breaks, look at countTokens.
| Trigger | What you see | Fix |
|---|---|---|
| Prefill, "continue" or start-reply-with: a partial model reply is sent for the model to finish | Fails on every request, often from the first message | Put the instruction in systemInstruction or a JSON schema; turn off assistant prefill or continue settings |
| History saved right after a reply: rewind, an interrupted stream, voice barge-in, a step-limit note added as an assistant message, steps stored out of order | Works for a few turns, then fails; typing a new message lets it continue | Append the new user turn, or drop the trailing model turn, before sending |
Tool flow where the model's functionCall is the last turn | Fails right after the model asks for a tool | Send a user turn with the functionResponse before calling again |
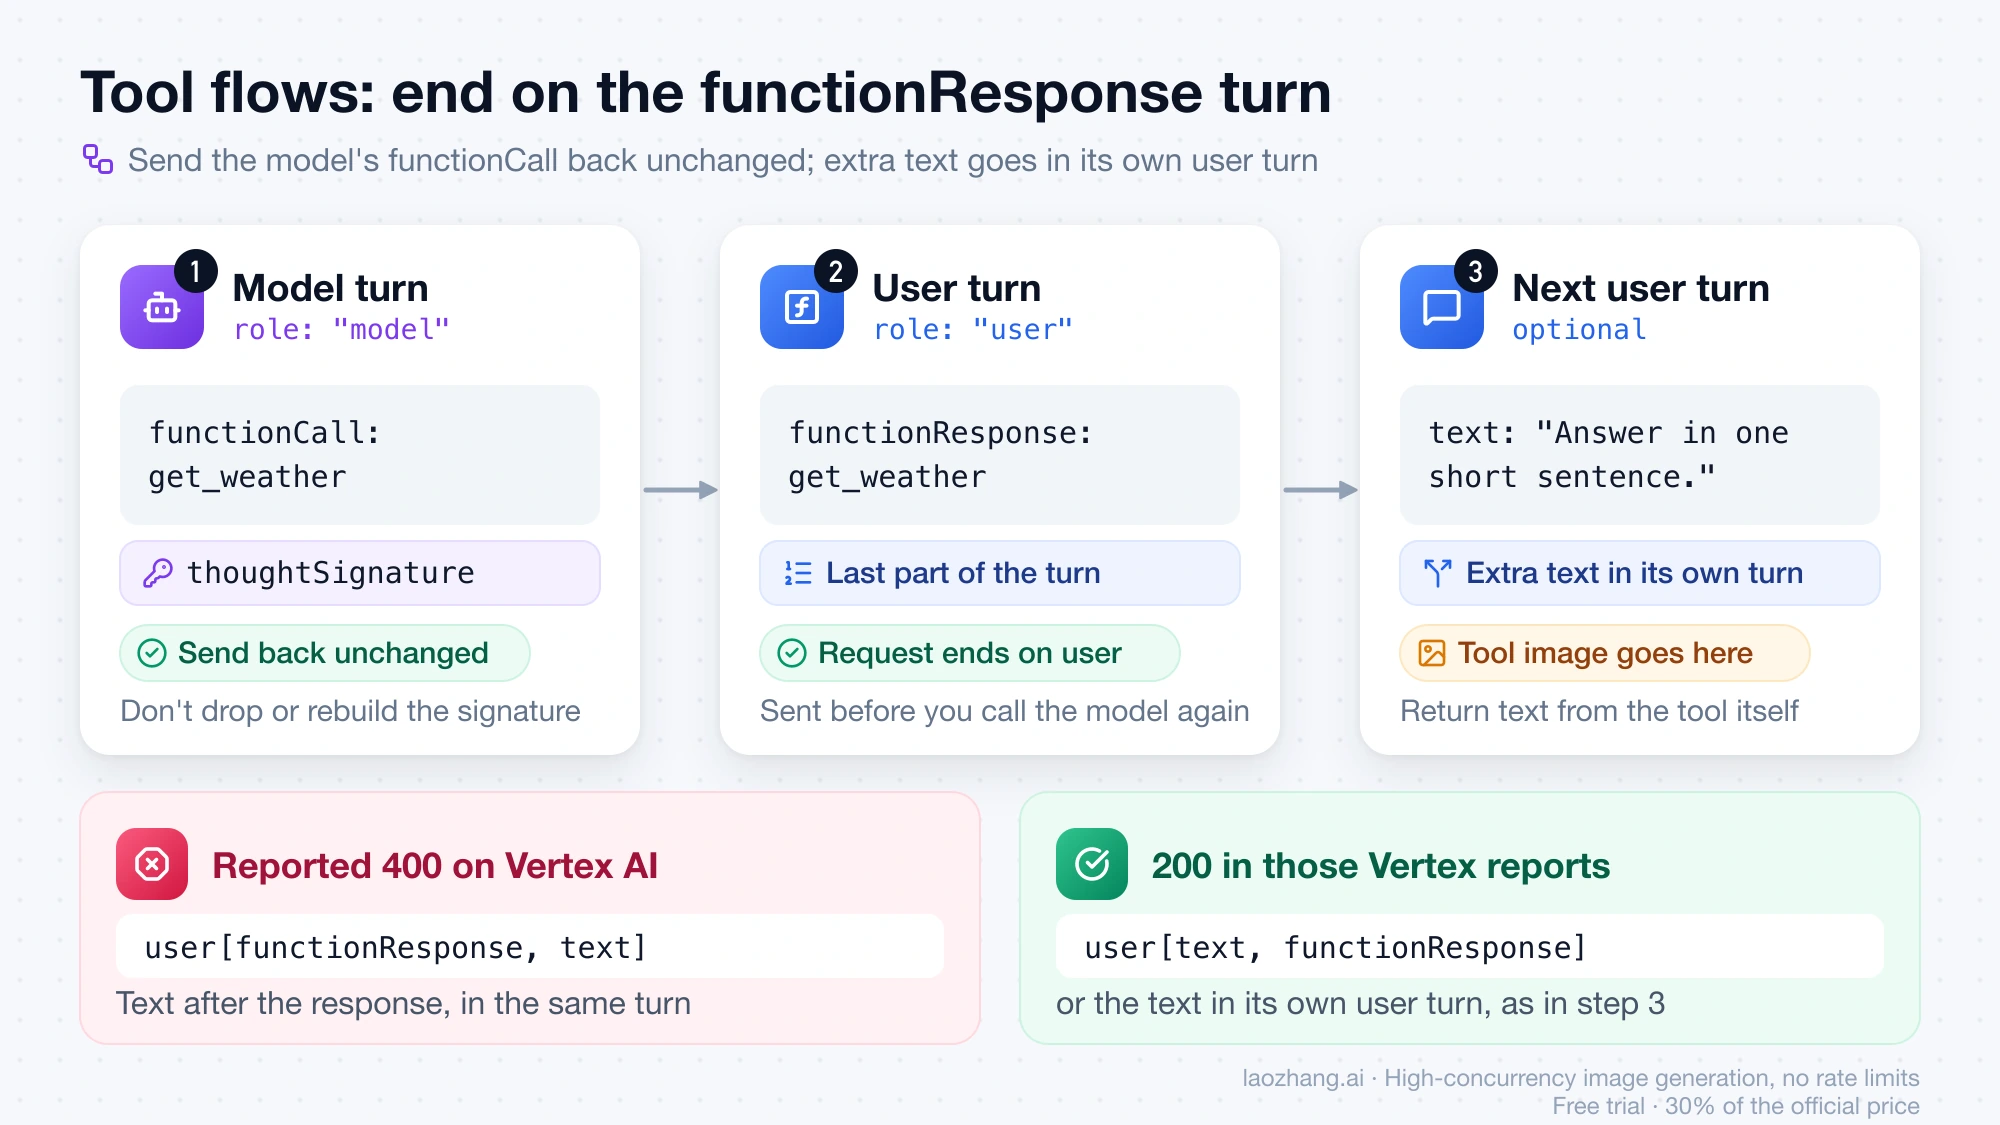
| Tool result shaped wrong: function response and text in one user turn on Vertex AI, or an image in a tool result | Fails right after a tool runs, especially after reading a .png | Keep functionResponse as the last part, and move extra text or the image into their own user turn |
countTokens on a history that ends on the model | Chat works, but the token count fails or reads 0 | Count the request you are about to send, or read usageMetadata.promptTokenCount |
A visible user message in the interface does not prove the request ends on a user turn. The EvoLink SillyTavern troubleshooting guide (October 16, 2026) notes that prefill, continuation, history conversion and extensions can all change the final message after you hit send. The only reliable check is the payload that leaves your client or proxy.
Test on gemini-4-argon, October 29, 2026: which request shapes return 400
On October 29, 2026, between 03:00 and 03:05 UTC, requests were sent to gemini-4-argon through the laozhang.ai Gemini-native generateContent endpoint, over plain REST with thinkingLevel: low, changing one thing per request. Every 200 below came back with modelVersion: gemini-4-argon, and every 400 carried the message Requests ending with a model turn are not supported. Each shape ran once, except prefill, which was repeated at 03:13 UTC with the same 400. This is one endpoint on one day.
Disclosure: laozhang.ai is our own service. Its prices are platform pricing, not an independent comparison.
contents sent (last item last) | Result |
|---|---|
[user] | 200 |
[user, model "Rain"], a one-word prefill | 400 |
[user, model, user, model], history saved right after a reply | 400 |
| The same history without the final model turn, ending on the new user message | 200 |
[user] plus a get_weather tool | 200, reply is a functionCall |
[user, model(functionCall)], no function response yet | 400 |
[user, model(functionCall), user[functionResponse]] | 200 |
[user, model(functionCall), user[functionResponse, text]] | 200 |
The two history rows are the fix in miniature: the conversation is the same, and the only change is whether the last turn is the model's saved reply or the user's next message. In the tool rows, the functionCall turn Argon returned was sent back unchanged, thoughtSignature included, which is also what Google's Argon checklist asks for in multi-turn and function-calling requests.
The last row is the one to be careful with. On this endpoint, a function response followed by text in the same user turn returned 200, but on Vertex AI senpi issue #3633 (October 18, 2026) measured 400 for that exact shape with Argon, and a LiteLLM 1.101.0 user on Google Cloud Express reported the same on October 28. That fits the longer error text, since the last part there is text rather than the function response. Treat it as route-dependent and use the shapes that returned 200 in those Vertex reports: text before the functionResponse, or the text in its own user turn. Those two shapes, and the systemInstruction and JSON-schema replacements for prefill, have no result from this test; they come from Google's documentation and the reports linked here. The 400 bodies arrived in the gateway's envelope ("type":"upstream_error"), while Google's own body uses "status":"INVALID_ARGUMENT".
How to fix it in your own code: end on a user turn
Work from the payload rather than from the chat UI, and go in this order, because the first step tells you which of the others applies.
-
Log the final
contentsafter your SDK, framework or proxy has converted it, and read the role of the last non-empty entry. In OpenAI-stylemessages, a finalassistantmessage becomes amodelturn, which is why the error also appears on Chat Completions-compatible endpoints. -
If the last turn is a saved model reply, add the user's new message before you send. A "continue" button with no new text should send a short user turn such as "Continue." rather than resend the model turn. To pick up a long Argon answer that stopped early, use its continuation mechanism instead, covered in Gemini 4 Argon API finish_reason: CONTINUATION and Empty Replies.
{
  "contents": [
    { "role": "user", "parts": [{ "text": "Summarize this file." }] },
    { "role": "model", "parts": [{ "text": "Here is the summary..." }] },
    { "role": "user", "parts": [{ "text": "Now make it shorter." }] }
  ]
}- If you prefilled to suppress a preamble or force JSON, move that into
systemInstruction, or set a response schema so the model has to return JSON. Google's own sample uses the Interactions API fieldsystem_instruction; ingenerateContentREST the fields aresystemInstructionandgenerationConfig.responseJsonSchema.
{
  "systemInstruction": { "parts": [{ "text": "Output only the translation, with no introduction." }] },
  "contents": [{ "role": "user", "parts": [{ "text": "Translate 'Hello world' to Spanish." }] }],
  "generationConfig": {
    "responseMimeType": "application/json",
    "responseJsonSchema": {
      "type": "object",
      "properties": { "translation": { "type": "string" } },
      "required": ["translation"]
    }
  }
}- In tool flows, send the model's
functionCallcontent back exactly as it came, then a user turn whose parts hold thefunctionResponse. Don't drop or rebuildthoughtSignature. On Vertex AI, keep the function response as the last part, so text goes before it or into the next user turn. If a tool returns an image, the Hermes Agent report on OpenRouter got 200 by returning text in the tool result and sending the image in a follow-up user message.
[
  { "role": "model", "parts": [{ "functionCall": { "name": "get_weather", "args": { "city": "Paris" } }, "thoughtSignature": "..." }] },
  { "role": "user", "parts": [{ "functionResponse": { "name": "get_weather", "response": { "temperature_c": 14 } } }] },
  { "role": "user", "parts": [{ "text": "Answer in one short sentence." }] }
]
- Mark this error as non-retryable in your client. Google's Gemini API troubleshooting guide says to retry only 429, 408 and 5xx, and not 400. Retry loops are how the LiveKit agents-js issue #2108 logged 84 errors and 21 lost turns in about 24 hours, and the senpi maintainer asked for this 400 to be treated as a request error, not a cooldown or fallback trigger.
Why countTokens returns 400 on Gemini 4 Argon
The public report comes from obsidian-gemini issue #1708, filed by the plugin's maintainer, Allen Hutchison, on October 27, 2026 and still open as of October 29. With gemini-4-argon as the chat model, the plugin's models.countTokens call on the first turn of a new session failed with {"error":{"code":400,"message":"Requests ending wi…are not supported.","status":"INVALID_ARGUMENT"}}, cut off in the log, while the same flow with gemini-flash-latest did not fail. His hypothesis, which he marks as unverified, is that right after a response is saved the session history ends on the model's turn, and Argon rejects a countTokens request whose contents end that way. The generateContent results above, where a history ending on the model returns this 400, are consistent with that explanation.
The visible symptom in that plugin was a token display and compaction threshold reading 0 on a fresh session, because its fallback used the last usage metadata. The proposed fix is to count up to the last user turn or add a trailing user turn, which in practice means counting the request you are about to send rather than the saved history. Firebase's Count tokens guide for Firebase AI Logic (updated October 27, 2026) lists gemini-4-argon as supported, charges nothing for countTokens, caps it at 3,000 requests per minute, and counts system instructions and tools in the input total. It also says usageMetadata comes back with every response at no charge, so usageMetadata.promptTokenCount is a documented alternative once the first reply arrives.
from google.genai import types

# Count what you will send next, not history that ends on the model's reply
pending = types.Content(role="user", parts=[types.Part(text=new_message)])
result = client.models.count_tokens(model="gemini-4-argon", contents=history + [pending])
print(result.total_tokens)
Behind a gateway, first check that :countTokens is forwarded at all. On the endpoint used for the test above, POST /v1beta/models/gemini-4-argon:countTokens returned 400 unsupported action: countTokens on October 29, 2026, whether the contents ended on a user or a model turn. That 400 comes from the gateway rather than Google, and no change to turn order fixes it.
Gemini CLI, opencode, SillyTavern and other tools: status as of October 29, 2026
If a tool builds the request for you, the fix is a tool update or a setting, and the table shows where each one stands as of October 29, 2026. "Open" means the issue had no merged fix you can install yet.
| Tool | What makes the request end on the model | Status and what to do |
|---|---|---|
| Gemini CLI | /rewind, an interrupted or aborted stream, rapid Ctrl-C, or ReadFile on a .png that drops the image part (#29530, #29574, #29588) | Fixes merged October 7 and 13, 2026 and included in v0.65.0, released October 20; update to v0.65.0 or later |
| opencode | Step-limit prompt appended as an assistant message (#45359); every step after read on a .png with openrouter/google/gemini-4-argon (#55694); steps stored out of order, also seen in Kilo Code | No confirmed fixed version; typing a new prompt lets the session continue |
| SillyTavern and other role-play front ends with an AI Studio key or a proxy | Assistant prefill, continue or start-reply-with style settings, extensions, prompt post-processing | Test a fresh chat that ends with your own message and prefill and continue turned off, then turn settings back on one at a time |
LangChain (langchain-google, Vertex AI) | A ToolMessage and the following HumanMessage merged into one user content (#1995) | Open; avoid a human message straight after a tool result on Vertex AI |
| LiteLLM | Vertex Gemini 3.7 Flash rejects history ending in a text-only assistant message (#38537); mixed response and text content on Argon | Open; send tool results and text as separate turns |
| instructor | Structured-output "reask" ends the request on a model turn (#2631) | Open; reasks fail every time on 3.6+ models |
| Hermes Agent via OpenRouter | Tool result with an image as the last message (#139313) | Return text from the tool and send the image in a follow-up user message |
| LiveKit Agents (JS) | Voice barge-in leaves a truncated assistant message last (#2108) | Reported on 3.6 Flash and 3.5 Flash-Lite; stop the retry loop and end on the user's turn |
| Android Studio Gemini | Listed in Google Issue Tracker 537423583 | Listed as "Assigned, P2"; the tracker entry shows July 22, 2026 |
For Gemini CLI, the update itself is an npm reinstall, covered in How to Install Gemini CLI (2026): Setup and Which Login Works. The v0.65.0 cutoff comes from the fix commits being part of that release; earlier 0.64.x builds may or may not carry them.
Requests ending with a model turn: related questions
Is this the same error as "role system is not supported"?
No. That 400 means the model or endpoint does not accept a role such as system, developer or tool at all, while this one is about which role comes last. The fixes differ, and Fix API 400 Unsupported Role Errors Without Breaking System Prompts covers that one.
I also use Claude. Does Claude reject prefill too?
Yes. Claude 4.6 and later models return their own 400 for a request that ends on an assistant message, with different wording and a different fix path, explained in Claude "Does Not Support Assistant Message Prefill" 400 Fix. Code that switches between providers needs both checks.
What about "Function call is missing a thought_signature" on Gemini 3 and later?
That is a separate 400 about a functionCall sent back without its signature. In senpi issue #3633 (October 18, 2026), Argon returned the model-turn 400 on a Vertex AI transcript, and the fallback model gemini-3.1-pro-preview then failed on the same transcript with the signature error. "Thinking budget is not supported" on Vertex AI is another unrelated 400, and fixing the turn order clears neither. Explicit caching through cachedContents is not supported on Argon and returns an error, according to Google's Argon migration checklist.
Sources18
External pages this guide links to, in the order they appear. Last updated Oct 29, 2026.
Sources18
External pages this guide links to, in the order they appear. Last updated Oct 29, 2026.
- 1.What's new in Gemini 3.6 pageai.google.dev/gemini-api/docs/whats-new-gemini-3.6
- 2.Gemini 4 Argon migration checklistai.google.dev/gemini-api/docs/generate-content/latest-model
- 3.LINUX DO thread from July 22, 2026linux.do/t/topic/2631609
- 4.EvoLink SillyTavern troubleshooting guideevolink.ai/blog/sillytavern-gemini-setup-troubleshooting
- 5.senpi issue #3633github.com/code-yeongyu/senpi/issues/3633
- 6.Gemini API troubleshooting guideai.google.dev/gemini-api/docs/troubleshooting
- 7.LiveKit agents-js issue #2108github.com/livekit/agents-js/issues/2108
- 8.obsidian-gemini issue #1708github.com/allenhutchison/obsidian-gemini/issues/1708
- 9.Count tokens guide for Firebase AI Logicfirebase.google.com/docs/ai-logic/count-tokens
- 10.#29530github.com/google-gemini/gemini-cli/issues/29530
- 11.#29574github.com/google-gemini/gemini-cli/issues/29574
- 12.#29588github.com/google-gemini/gemini-cli/issues/29588
- 13.#45359github.com/anomalyco/opencode/issues/45359
- 14.#55694github.com/anomalyco/opencode/issues/55694
- 15.#1995github.com/langchain-ai/langchain-google/issues/1995
- 16.#38537github.com/BerriAI/litellm/issues/38537
- 17.#2631github.com/567-labs/instructor/issues/2631
- 18.#139313github.com/NousResearch/hermes-agent/issues/139313